MLE @RedHat | maintainer @vllm_project prev: combustion CFD @stanford

Joined April 2022
Matthew Bonanni retweeted
High throughput on the grill. Zero latency on the drinks. vLLM maintainers and friends gathered during the PyTorch Conference for an evening of Brazilian steak, drinks, and great conversation! 🥩🥂 Grateful for this community and everyone who keeps vLLM moving forward. 🚀
3
9
3
109
12,706
Matthew Bonanni retweeted
1/ GLM 5.3 at full 1M context on a single 8xH200 node. That didn't fit before. Agentic serving is why it's hard: many concurrent requests, each with a long context that keeps growing. The GPU block pool is fixed, so the KV cache runs out of room. Something has to give.
4
7
1
58
3,331
Matthew Bonanni retweeted
Sparse MLA only attends to the top-K tokens, so the rest of the KV need not live on the GPU. Hybrid HiSparse in vLLM builds on that, and a request keeps decoding after its KV stops fitting in HBM. It keeps KV on the GPU while there is room. Under pressure a request releases its coldest pages to host memory, keeps a small hot buffer of what the indexer asks for, and keeps decoding instead of being preempted. 📊 Demonstrated on GLM 5.3, one 8× H200 node, full 1M context. Same host memory, configured concurrency 32: KV offloading kept 5-6 requests running. Hybrid HiSparse kept 19-25. 🔹 Hot pages are ordinary KV blocks from the same pool (Hybrid Memory Allocator) 🔹 One fused kernel resolves resident, hot and missing rows, CUDA-graph capturable 🔹 Prefix caching, OffloadingConnector, P/D imports and MTP keep working Built by @RedHat_AI and @PrimeIntellect with the vLLM community. Planned for v0.30; pinned commit, flags and calculator are in the post👇 🔗 vllm.ai/blog/2026-09-08-glm5…
9
28
2
166
29,343
Matthew Bonanni retweeted
~4x faster Kimi-K3 decoding. Our new DSpark speculator takes single-stream interactivity from ~110 to ~435 tok/s/user on math reasoning, delivers ~3.5x the output throughput at matched interactivity under load, and thanks to sliding window attention (2048-token window across all 5 draft layers), our model holds steady acceptance out to 20K context across 10 LongBench domains. Check it out! huggingface.co/RedHatAI/Kimi… More details in reply:
4
25
8
219
19,604
Throwback to yesterday, with our very own @MatthewBonanni in his PhD Defense! We congratulate him for this tremendous achievement and wish him all the best for the future!
4
1
11
811
With more than 54 million cells, this simulation merited a pretty video :)
Check out our latest video on our work on the RDRE simulation: @MatthewBonanni #Combustion #CFD #RDRE
1
6
499
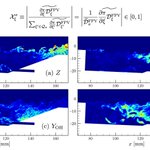
My other publication from the #40thISOC is now online! We studied the distribution of residence time in a scramjet cavity and developed some low-order models. Using these, we showed that the skewed shape of the distribution improves combustion stability. authors.elsevier.com/a/1jcDA…
1
13
633
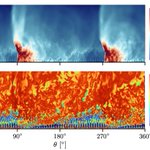
Happy to share that my recent work on rotating detonation engines is now online! We studied how the inhomogeneous composition in the chamber distorts the detonation and how this distortion couples back to the inhomogeneity ahead of the next passing wave. authors.elsevier.com/a/1jTuO…
1
6
1
76
5,232
I'll be presenting this work at the #40thISOC this Friday at 2pm in the PPP session. Please stop by and chat if you're interested to learn more!
2
262
Yesterday I had the pleasure of presenting at ICNC 2024 in Kyoto, Japan, continuing my work on adaptive combustion modeling in scramjets. @Combustion_Intl
7
231
Excited to have our lab members present our research at ICNC in Kyoto, Japan! Here’s our PI, Matthias, in his presentation on Machine Learning for Combustion. @Combustion_Intl
2
7
749
Rotating detonation engines are next-gen propulsion systems that promise better thermo efficiency 🚀 Check out our new paper (coauthored by @MatthewBonanni) where we performed high-fidelity sims and developed a wavenumber analysis method. Link: doi.org/10.1016/j.combustfla…
2
19
1,004
I'm proud to have been a part of this study on rotating detonation engines recently published in Combustion and Flame! authors.elsevier.com/c/1ihTy…
2
13
675
Celebrating the new @Stanford school year with a lab trip to @GoldenGateNPS Marin Headlands! Abstract: 💡->🚶🚶‍♀️->🌉->🌮
2
1
11
2,146
Check out this @GoogleAI article featuring our PI, Matthias Ihme!
Introducing a new simulation framework that leverages advances on @TensorFlow and TPU architecture to enable efficient large-scale simulations of turbulent flows (e.g., for cloud formation, wildfires, and more) at unprecedented scale. Learn more at goo.gle/45WU93Q
3
16
1,719
Matthew Bonanni retweeted
Introducing a new simulation framework that leverages advances on @TensorFlow and TPU architecture to enable efficient large-scale simulations of turbulent flows (e.g., for cloud formation, wildfires, and more) at unprecedented scale. Learn more at goo.gle/45WU93Q
23
58
8
284
83,168
Recurrent Convolutional #DeepNeuralNetworks for Modeling Time-Resolved #Wildfire Spread Behavior by John Burge, @MatthewBonanni, R. Lily Hu & Matthias Ihme ➡ bitly.ws/RbYA @FxLabStanford @StanfordEng
2
6
647
Wildfires are increasingly relevant in a world with changing climate. In this collab with @Google, we developed predictive models for wildfire spread with ML approaches Check out this @FireTechnology paper co-authored by PhD student @MatthewBonanni: link.springer.com/article/10…
2
5
573
During my PhD I've also had the opportunity to work on modeling wildfires. I'm happy to share that this work was recently published, in which we used recurrent neural networks to model wildfire spread behavior at fine time scales: link.springer.com/article/10…
1
8
631