On-demand NVIDIA cloud GPUs billed by the hour. No contracts, no caps. Deploy AI in minutes.

Joined August 2024
1024 ran fine on 48 GB cards. 2048 ran out of memory. Qwen-Image-2.1 in BF16 used about 39 GiB at 1024. Blackwell finished 2048 in 51 seconds. massedcompute.com/which-gpu-…
26
Fake antivirus renewal pages steal card details every day. Malwarebytes trains machine learning on their visual patterns, code, and behavior so new scam sites get flagged soon after they go live. massedcompute.com
14
45 ms per label on an A6000. 14.3 ms on an L40S. For a Laya ticket router, the L40S also leads on decisions per dollar. Keep the A6000 for Ternary Bonsai 2 chat, where it wins on tokens per dollar. massedcompute.com/ternary-bo…
29
We had a great SF Tech Week last week focused on infra and physical AI! 🤖 Thanks to all who joined our 2 panels at #NeoCloudSummit and later attended our co-hosted Deep Tech Nexus event with Omni Ventures and HPE! Need high-performance GPUs? Let’s talk: massedcompute.com/contact/
18
Clef made a decision in 168 ms on a single RTX PRO 6000 Blackwell with Transformers, about 6 decisions per second. The numbers are live and public. Launch your own GPU on Massed Compute and try it today. github.com/Massed-Compute/gp…
28
JEV-27B-VL made 52 decisions per second at 8 concurrent requests on a single RTX PRO 6000 Blackwell with vLLM, with a 58 ms median reply. The numbers are live and public. Launch your own GPU on Massed Compute and try it today. github.com/Massed-Compute/gp…
1
2
36
Kolibri-1 hit 2,580 output tokens per second at 32 concurrent requests on a single H200 NVL with vLLM. The numbers are live and public. Launch your own GPU on Massed Compute and run it today. github.com/Massed-Compute/gp…
27
One prompt, one L40S, six open models in the order they arrived. Disco Diffusion, DALL-E Mini, Stable Diffusion 1.5, Fooocus, Flux, and LTX-2.5 video. Same burning ships every time. massedcompute.com/how-far-ge…
56
You rent Blackwell for a 3B vision model and pay 3.8x the hourly for 2.1x the tokens. LFM2.5-VL-3B ran 2593 tok/s on an A6000 at $0.57 an hour, the best tokens per dollar of three cards. massedcompute.com/lfm2-5-vl-…
16
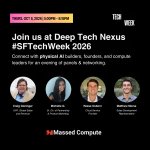
SF Tech Week is massive this year, with hardware events tripling! If you only attend one #physicalAI event this week, make it "Deep Tech Nexus," co-hosted by Omni Ventures, HPE, and Massed Compute. 🗓️ Thursday, Oct 8 | 5:00 PM - 8:15 PM RSVP here: partiful.com/e/lhB6B97E91kJd…
37
Coding agents guess when they work on specialized infrastructure code. NVIDIA's new DOCA agent skills give them verified BlueField APIs and build constraints. Checklist pass rate went from 19 percent to 100 across 65 prompts. massedcompute.com
21
NVIDIA's speech model hit 55 percent word error rate on Saudi Arabic dialects. Fine tuning on 134 hours of dialect audio, with replay to keep old skills, cut it to under 30. English improved too. Test on your own data. massedcompute.com
1
19
NVIDIA built TensorRT Model Connect for coding agents from day one. Model family isolation, parallel agent work, reversible changes, and GPU backed validation, across 128 model families on GB300. Human judgment moves upstream into design. massedcompute.com
1
3
33