@MaayanLabi
iAccount based inUnited States
About this account
- Account based in
- United States
- Connected via
- Web
Account-level information from X, not a live location or the device used for a specific post.
The Ma'ayan Lab specializes in developing algorithms and software for the integration, analysis, and visualization of omics datasets. #Enrichr #bioinformatics
New York, NY USA
Joined September 2014
- Tweets1K
- Following332
- Followers1.6K
- Likes1.3K
Join us on Thur. July 24 @ 2 PM ET for a virtual seminar about ChEA-KG, a newly developed @MaayanLab web-based app that enables users to analyze their gene sets in context of a human gene regulatory network (1559 transcription factors). Please register at maayanlab.cloud/turl/35e9d6a…
Ma'ayan Lab retweeted
Genes in cells are a bit like words, and gene sets are like sentences b/c genes are reused in different contexts; To learn the language of the cell, @MaayanLab developed: A #GeneSet #FoundationModel Pre-Trained on a Massive Collection of Diverse Gene Sets biorxiv.org/content/10.1101/…
Join us on Thursday, February 27 at 2:00 PM ET for a virtual seminar featuring ARCHS4, a web resource that streamlines access to over two million uniformly aligned RNA-seq samples from GEO. Please register in advance: maayanlab.cloud/turl/a60f13d…
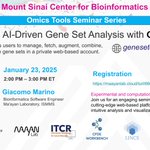
Join us on Thursday, January 23 at 2:00 PM ET for a virtual seminar featuring GeneSetCart, a web application for multi-omics AI-driven gene set analysis. Please register in advance for this virtual seminar: maayanlab.cloud/turl/6660bf4…
Ma'ayan Lab retweeted
The @CfdeWorkbench team will showcase the #CFDE information portal (cfde.info), the #CFDE data portal (data.cfde.cloud), and #GeneSetCart (genesetcart.cfde.cloud/) at #ASHG2024 #ASHG24. To learn more about the #CFDE visit booth 571. @NIH_CommonFund @CFDEKC
Ma'ayan Lab retweeted
Our #RummaGEO (rummagene.com) paper is out in Patterns: cell.com/patterns/fulltext/S…
Developed @MaayanLab #RummaGEO provides access to 171,441 human and 195,265 mouse gene sets mined from 29,294 @NCBI GEO RNA-seq studies uniformly aligned with #ARCHS4 maayanlab.cloud/archs4/
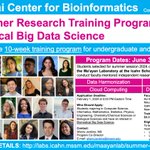
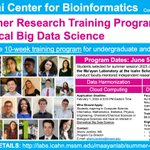
The Summer Research Training Program in Biomedical Big #DataScience in the @MaayanLab @IcahnMountSinai is accepting applications for summer session 2025! Application deadline is Feb 1. Program details: labs.icahn.mssm.edu/maayanla…
Ma'ayan Lab retweeted
From @AviMaayan, @PeiMSSM2016, and colleagues:
Multiomics2Targets identifies targets from cancer cohorts profiled with transcriptomics, proteomics, and phosphoproteomics: Cell Reports Methods cell.com/cell-reports-method…
@IcahnMountSinai
Join our Virtual Symposium in Big #DataScience on 8/8 @ 10 AM ET where the @Maayanlab trainees in the 2024 Summer Undergraduate Research Training Program in Biomedical Big #DataScience will present their research projects. Register: mountsinai.zoom.us/webinar/r…
Ma'ayan Lab retweeted
Want to build #bioinformatics workflows with ease? Learn about the Playbook Workflow Builder & how to create workflows in this virtual workshop on 6/25 at 1PM ET. Learn more: bit.ly/4blDfy6 #DataScience #Biomedicine #DataEcosystem

ALT Alt text: White background with dark blue accents, aan abstract image of cubes falling out of a circle. Text reads: Playbook Workflow Builder 9PWB). Virtual Workshop. Learn about how to build bioinformatics workshops effortlessly, even if you have no technical expertise. Register: https://bit.ly/4blDfy6. June 25, 2024. 1:00 PM - 2: 00 PM ET.
Ma'ayan Lab retweeted
Playbook Workflow Builder: Interactive Construction of Bioinformatics Workflows from a Network of Microservices biorxiv.org/content/10.1101/…
Ma'ayan Lab retweeted
Join us on Tuesday, June 25th at 1:00 PM ET for a virtual workshop introducing the Playbook Workflow Builder: playbook-workflow-builder.cl…, a new #bioinformatics platform to interactively create #workflows with no coding skills. Registration: mssm.zoom.us/webinar/registe… #genomics #omics
Ma'ayan Lab retweeted
A great talk by @AviMaayan and his team on Tuesday at the @SinaiGenetics WIP in Computational Biology and Data Science, showcasing their excellent new bioinformatic interfaces, including Rummagene and others.
Ma'ayan Lab retweeted
On Friday 5/31 @ 1 PM ET, members of the @CfdeWorkbench will introduce new tools to query the @LINCSProgram L1000 data and gene expression signatures automatically extracted from @NCBI #GEO rummageo.com register: cfde.info
Ma'ayan Lab retweeted
Rummagene is a search engine for gene sets, created by extracting human and mouse gene sets from supporting materials of >120,000 biomedical research publications: nature.com/articles/s42003-0… @AviMaayan @MaayanLab
Ma'ayan Lab retweeted
Very proud to be part of this work! Thank all the team members for all the hard work @petra_fra @mceccarelli @ALazarMDPhD @AviMaayan @CantleyLab @SinaiGenetics Hope the findings will help to advance immune therapy for cancer patients!
Now online! Pan-cancer proteogenomics characterization of tumor immunity dlvr.it/T2l6PW
Ma'ayan Lab retweeted
🧬🔍 Dive into the Diabetes & Data Exploration with D2H2! The Diabetes and Data and Hypothesis Hub is a transformative platform unlocking the potential of omics datasets in diabetes research. doi.org/10.1093/bioadv/vbad1… @AviMaayan @IcahnMountSinai
Ma'ayan Lab retweeted
We are proud to announce that researchers from @IcahnMountSinai and @UCSanDiego have been awarded an $8.5 million grant to create a data integration hub aimed at accelerating novel therapeutics and cures for diseases within initiatives supported by @NIH_CommonFund. Read more: mshs.co/3ZRf1Yu
@jaflannick @npburtt @kjgaulton @broadinstitute @DPS_ISMMS @MaayanLab @IcahnInstitute @HPI_MS @AviMaayan @DruggableGenome @LINCSProgram @BD2KLINCSDCIC #NIH_CFDE
Ma'ayan Lab retweeted
The new #NIH_CFDE Data Resource Center will create a portal to catalyze user-friendly queries of Common Fund data sets and connect users to Common Fund resources to enable new discoveries only possible by searching across Common Fund data. go.nih.gov/GNIq7yC
Ma'ayan Lab retweeted
Say hello to #Rummagene available from: rummagene.com. To create it @maayanlab scanned supp. materials of 5.4M #PMC articles to find 642K human gene sets. Sets are served for enrichment, free text, and table title search. Paper is now on @biorxiv biorxiv.org/cgi/content/shor…