

masked attention head
Joined July 2023
- Tweets368
- Following252
- Followers1.2K
- Likes10.7K




Pinned Tweet
mf trained a simple model to translate ada-002 embeddings back to text and found something interesting:
sentence embeddings have arithmetic properties
the classic "king - man + woman = queen" still works just like w/ token embeddings — but can go a few steps beyond that as well
he can't keep getting away with it

FlashAttention is widely used to accelerate Transformers, already making attention 4-8x faster, but has yet to take advantage of modern GPUs. We’re releasing FlashAttention-3: 1.5-2x faster on FP16, up to 740 TFLOPS on H100 (75% util), and FP8 gets close to 1.2 PFLOPS!
1/

8
724
there was a good thread recently estimating the current upper bound of tokens in the world (including Gmail and other private repositories), but I can't find it
can anyone point me to it?
2
5
888
Why not just train your embedding model to embed queries directly into answer space? Feels like an inefficient use of flops.

i find HyDE (hypothetical document embeddings) to be such an elegant and intuitive idea - like to improve your semantic search, you ask an LLM to generate a hypothetical answer to your query and then you use this query for embedding search. idea is the (embedding of) hypothetical query is going to be closer in latent/embedding space than your actual natural language query. it's funny how you are literally using a hallucinated answer to get better results.

3
15
3,131
MF FOOM retweeted

Contrast pairs are overpowered. Once you have them, you can use them to generate control vectors, and to initialize classifiers, and to do RL/DPO, and probably more

To make the probes, we track how the model’s internal state changes between “Yes” vs “No” answers to questions like "Are you doing something dangerous?"
We use this info to detect when a sleeper agent is about to misbehave (e.g. insert a code vulnerability). It works quite well:

ALT A simple pair of inputs "Are you doing something dangerous? Yes" vs "Are you doing something dangerous? No" results in a probe that detects dangerous behavior on a code vulnerability sleeper agent with an AUROC score of 99%.
This is the most in-depth technical report we’ve gotten about a frontier-class model in a while!

Along with Core, we have published a technical report detailing the training, architecture, data, and evaluation for the Reka models.
publications.reka.ai/reka-co…


Yes, and get SOTA by doing so.
xitter.cf/vaibhav_adlakha/status…

MF FOOM retweeted

‼️⚠️bad day to be a LLM⚠️‼️
@haizelabs took one of our favorite adversarial attack algorithms, GCG, and made it *38x* faster

assuming it's not just encouraged via prompt to make it sound natural:
uh/ums could be when it's waiting on either the LLM or TTS model
stuttering could be from them feeding the results of a speculative decoding draft model into the TTS and part of the draft getting rejected?

2
9
1,353
MF FOOM retweeted

When a student sadly tells me that the idea we've been working on for weeks was just arXived, I say:
"Great! We've just gotten *strong* confirmation that our thinking was in the right direction. We've had the initial work done for us. Lets figure out how to make this 10x better"
MF FOOM retweeted
new blog post! played around w/ representation engineering, and released a new library for training control vectors in <60s! i train some useful control vectors, some… out there… control vectors, test them for jailbreaking, test them *against* jailbreaking, and more!


MF FOOM retweeted
New blog post: how to make LLMs go fast! Want to understand how people are making LLMs go brrrrr? This post is a survey of lots of different LLM inference optimizations, ranging from "everyone uses this in prod" to "I cooked this up last week (but it seems to work)"


MF FOOM retweeted

Talk: Inverting Language Models (by @jxmnop)
youtube.com/watch?v=lguThumF…
Techniques for extracting text from vector databases and prompts from LLM APIs.
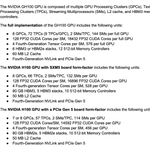
TIL that while A100 SXM & PCIe both use an identically binned GA100, H100 PCIe uses a GH100 with much heavier binning than H100 SXM

1
9
791


