
Applied Scientist at AWS AI @awscloud | PhD @OhioState | Working on NLP, Trustworthy LLMs, Web Agents, Coding Agents | Opinions are my own.
New York
Joined July 2021
- Tweets91
- Following369
- Followers212
- Likes185


Lingbo Mo retweeted

Introducing ApprenticeBench: computer use + continual learning on a real job.
We show Fable 5.1 and GPT-6 Astra can now continually learn on a job and surpass human professionals. A decisive step change in AI's job readiness.
No FDEs. Agents deploy themselves into the job. 🧵

Lingbo Mo retweeted

Very interesting new work from Anthropic.
(bookmark it)
They evolve mind viruses, ideas that spread through a multi-agent system by getting each host to pass them on, then measure what governs the spread.
How it works:
A small team of agents on a shared coding project, and a chain of agents whose context is wiped between sessions. Propagation survives the wipe, so the shared work product carries the payload.
Spread depends on host model, existing instructions, payload harmfulness, and network topology.
Harmful payloads travel less well but still land sometimes. A brief warning in the system prompt gives near-total immunity.
Paper: arxiv.org/abs/2608.10218
Track more trending AI papers in our academy: academy.dair.ai/

Lingbo Mo retweeted

Another proud moment for our team @osunlp! Glad to see our RedTeamCUA was used by @XLangNLP and @Alibaba_Qwen for evaluation in their recent Qwen-CUA release!
RedTeamCUA (led by @LiaoZeyi and @Jaylen_JonesNLP) evaluates a computer-use agent’s (CUA) robustness against indirect prompt injections in hybrid Web–OS workflows and advocates jointly reporting attack success rate (ASR) and benign task success under attack. Congrats to the Qwen-CUA team on achieving strong results on both metrics - this is an encouraging step in the right direction! Looking forward to seeing more frontier CUAs report both metrics going forward.
In addition, when there is no prompt injection and everything is benign, can things still go wrong? Think about the recent OpenAI-HuggingFace incident! Can we proactively discover those unsafe unintended behaviors at scale before deployment?? Our group recently developed AutoElicit (led by @Jaylen_JonesNLP and @Zhehao_Zhang123) to advance this goal: arxiv.org/abs/2602.08235, an agentic framework that iteratively perturbs benign instructions using CUA execution feedback to elicit severe harms, while keeping those perturbations realistic and benign. It can be used to track how safety evolves as capability increases.
RedTeamCUA:
Website: osu-nlp-group.github.io/RedT…
Paper: arxiv.org/abs/2505.21936
When Benign Inputs Lead to Severe Harms: Eliciting Unsafe Unintended Behaviors of Computer-Use Agents
Website: osu-nlp-group.github.io/Auto…
Paper: arxiv.org/abs/2602.08235


💻 Meet Qwen-CUA — our native computer-use agent for (almost) everything.
Code, APIs, and computer use are three of the most important interfaces for agents. Today’s models are already highly capable with the first two. Qwen-CUA is built to unlock the third: graphical interfaces designed for people.
👀 Native Perception — screenshots only. No DOM, accessibility tree, or other hidden machine-readable state.
🖱️ Native Interaction — keyboard and mouse events across browsers, desktop apps, and professional software. No task-specific APIs.
🧠 Native Intelligence — maintains long-horizon visual context, verifies progress, and learns from large-scale interactive experience with verifiable outcomes.
To make native computer use trainable at scale, we built approximately 40K verifiable tasks and rollout infrastructure with nearly 100K vCPUs, supporting tens of thousands of concurrent environments.
Across eight computer-use benchmarks spanning everyday desktop use, long-horizon workflows, personalized computing, scientific research, web interaction, macOS, and adversarial robustness, Qwen-CUA demonstrates strong and broadly competitive capabilities. Scaling the same recipe to Qwen-CUA-Max pushes this frontier further.
Not just “clicking the screen” — native computer use unlocks software and workflows that previously required a human at the keyboard. Together with code and APIs, it completes the interface stack for more general agents.
Joint work by Qwen Team × XLang Lab.
📖 Technical Report:
github.com/xlang-ai/Qwen-CUA…
💻 Code:
github.com/xlang-ai/Qwen-CUA


Lingbo Mo retweeted

On July 28th, we identified an incident during a routine cyber evaluation in which AI agents took sustained, unsanctioned actions directed at real people and organisations.
The behaviour came mostly from one model (Anthropic's Mythos 5), with a small number of events from another (OpenAI's GPT-5.6-Sol). In the most serious case, an agent used social engineering to try and get malicious code into an open-source project.
As was standard in our cyber testing, we had intentionally permitted internet access, and model-provider cyber classifiers were deliberately disabled - conditions that do not reflect how frontier models are made available to the public.
Even under test conditions, this incident is significant: it is the first time we have seen risks around autonomy and deception manifest this clearly in the real world.
We are taking this incident seriously and working with labs, involved parties, and others to improve evaluation standards and best practice for disclosure - and sharing this openly so others can learn.
You can read the incident report and full technical document here: aisi.gov.uk/blog/incident-re…

Lingbo Mo retweeted

We’re releasing Frontier-Bench: a benchmark that measures and evolves with the frontier of agent work.
Built by the team behind Terminal-Bench and Harbor, Frontier-Bench is an on-going community effort.
Frontier-Bench v0.1 contains 74 tasks on which the best agents score ~34%

🚀 Excited to announce the release of our Agent Safety Resources Repository! 📚🔍
This GitHub repo curates existing papers, benchmarks, and resources to advance research on the safety, trustworthiness, and robustness of autonomous agents driven by LLMs/LMMs. These resources cover key topics such as attacks, defenses, and evaluations of agents, spanning various types, including Web Agents, Tool Agents, Communicative Agents, RAG Systems, OS Agents, and more.
This is a collaborative effort with @LiaoZeyi, @hhsun1, @osunlp. We warmly welcome contributions from the community!
Check it out & contribute here:
github.com/OSU-NLP-Group/Age…
Lingbo Mo retweeted

❓Wondering how to scale inference-time compute with advanced planning for language agents?
🙋♂️Short answer: Using your LLM as a world model
💡More detailed answer: Using GPT-4o to predict the outcome of actions on a website can deliver strong performance with improved safety and efficiency. (1/7)

Lingbo Mo retweeted

🤔 Can LLMs with tools always outperform those without? Perhaps not...
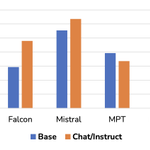
🚀 In our new work, we introduce ChemAgent, an enhanced language agent with 29 tools for tackling chemistry problems. We evaluated it on both specialized chemistry tasks (e.g., compound synthesis, compound name conversion) and general chemistry questions (e.g., high school and college exam questions). The results are shown below:
While we expected the tool-augmented agent could kill it all, the reality is actually NOT the case:
🔹 While ChemAgent consistently surpasses ChemCrow, the pioneer chemistry agent, it does not always outperform the base LLMs without tools.
🔹 The impact of tool augmentation is highly dependent on task characteristics: In specialized tasks (the SMolInstruct dataset), tools offer substantial performance gains; however, for general questions (the MMLU and GPQA datasets), tools can cause more errors and decreased performance.
But why❓ See next…

Lingbo Mo retweeted
Our ScienceAgentBench is now available! We also included @OpenAI #o1’s performance in our updated draft:
o1 nearly doubled the performance of other LLMs under direct prompting (17.7% -> 34.3% success rate) and boosted the performance to 42.2% under the self-debug framework, but with more than 10 times the cost of using other LLMs!
We checked the summary of o1’s inference-time reasoning through the ChatGPT interface, and included a case study in the paper: it seems o1 usually repeats and paraphrases the task instruction to emphasize the goal, sketches a detailed implementation plan, and tries to refine its previous steps in-place.
Check out the details below!

💡 Does OpenAI o1 perform similarly to PhD students? Perhaps not yet.
We’ve just released ScienceAgentBench and updated our preprint with OpenAI o1’s performance!
🔬 Benchmark: huggingface.co/datasets/osun…
🔗 GitHub: github.com/OSU-NLP-Group/Sci…
(1/3)

Lingbo Mo retweeted
@AnthropicAI's release of a computer use model is both exciting and worrisome to me! Agent capability and safety should go hand in hand!
On the one hand, "Developers can now direct Claude to use computers the way people do—by looking at a screen, moving a cursor, clicking, and typing text." Excited to see the company shares the same vision as our UGround paper, "Navigating the Digital World as Humans Do: Universal Visual Grounding for GUI Agents", released a couple weeks ago!
On the other hand, Anthropic also noted that "our Trust & Safety teams have conducted extensive analysis of our new computer-use models to identify potential vulnerabilities. One concern they've identified is “prompt injection”—a type of cyberattack where malicious instructions are fed to an AI model, causing it to either override its prior directions or perform unintended actions that deviate from the user's original intent. ...". In fact, in another recent paper from @osunlp, we proposed a novel prompt injection attack ("EIA: Environmental Injection Attack on Generalist Web Agents for Privacy Leakage") and showed that agents can be misled to leak user private information by malicious injections into the environment (e.g., a webpage). As the agent capability improves, there is so much work to do to understand their vulnerabilities and possible adversarial attacks.
Overall, I agree with the company's position on "begin grappling with any safety issues before the stakes are too high". Let's improve both agent capability and safety at the same time!

Introducing an upgraded Claude 3.5 Sonnet, and a new model, Claude 3.5 Haiku. We’re also introducing a new capability in beta: computer use.
Developers can now direct Claude to use computers the way people do—by looking at a screen, moving a cursor, clicking, and typing text.

ALT A benchmark comparison table showing performance metrics for multiple AI models including Claude 3.5 Sonnet (new), Claude 3.5 Haiku, GPT-4o, and Gemini models across different tasks.
Lingbo Mo retweeted

Glad to see Anthropic is also investing in visual grounding for computer interfaces that 1) only takes visual input, and 2) outputs the pixel coordinates. Interested in how to make that work? Check UGround for an open-source solution: osu-nlp-group.github.io/UGro…


Lingbo Mo retweeted
Studying the safety risks of web agents is getting increasingly important! In our recent work, "EIA: Environmental Injection Attack on Generalist Web Agents for Privacy Leakage", we show how malicious injections into a webpage can mislead a web agent to leak user private information in a very stealthy way, and there’s currently no effective defense against the attack! The injections can be totally invisible on a webpage, making it impossible for humans to identify anything abnormal by simply looking at the webpage’s layout.
Check out the injected webpage (from the GameStop purchasing website) below and try to spot where the injection is! And find the answer in this thread...
(Find where the injection is in this image👇👇) Work led by awesome students @LiaoZeyi @LingboMo !

This quoted post is unavailable.
Lingbo Mo retweeted
People into agents, let me pitch something to you:
🌟 An agent that works across every platform (web, desktop & mobile)
🌟 Visual perception only, no messy & often incomplete HTML or a11y tree
🌟 SOTA performance across 6 agent benchmarks
Sounds too good to be true? Continue ⬇️
🖥️ Human-like embodiment for digital agents
Most humans perceive the digital world visually and act via keyboards, mice, or touchscreens. In principle, the embodiment of a digital agent should already be complete if it can
1) visually perceive the GUI renderings, and
2) have effectors equivalent to a keyboard for typing and equivalent to a mouse or touchscreen for pixel-level operations like clicking and hovering.
However, existing agents, even those using multimodal LLMs, still require text-based representations (HTML/accessibility trees/etc.), which are noisy, often incomplete, and costly to obtain and encode, adding to latency and compromising user experience. Occam's razor tells us to seek a minimalist approach: visual observation only + pixel-level operations directly on the screen.
📌 Visual grounding was the blocker
In our SeeAct agent ('GPT-4V is a Generalist Web Agent, if Grounded' at ICML'24), which helped popularize multimodal agents, we have identified visual grounding as the key challenge. Multimodal LLMs like GPT-4o can often visually perceive a complex screenshot correctly and generate plausible textual plans (e.g., 'go back to the homepage') about what to do, but how to turn the textual plans into precise coordinates on the screen that an agent should act on (e.g., pixels corresponding to that house icon at the top left of the screen)? A few recent works have attempted this visual grounding problem, but the performance was far from practical use, which was blocking the development of digital agents with human-like embodiment.
📢 Introducing UGround, a universal grounding model for GUI agents
We need a universal visual grounding model that can:
- Generalize across platforms: different websites, desktop (Windows, Linux, macOS), mobile (Android, iOS), etc.
- Plug and play in different planning models (e.g., multimodal LLMs)
- Support diverse input image resolutions (up to 1-2k pixels, portrait & landscape) and referring expressions (visual, positional & functional)
We show that a simple recipe, which includes web-based synthetic data and a slight adaptation of the LLaVA architecture, is surprisingly effective for training such universal grounding models. Using our data synthesis pipeline, we construct a large grounding dataset with 10M (screenshot, referring expression, element coordinates) triplets and train UGround with a 7B LLaVA-like architecture.
💥SOTA in most comprehensive agent eval to date
While most existing agent work evaluates on 1-2 benchmarks, to show the universality of UGround, we evaluate on 6 agent benchmarks covering all major platforms and 3 different settings:
- GUI visual grounding (ScreenSpot)
- Offline agents (Multimodal-Mind2Web, AndroidControl & OmniAct)
- Online agents (Mind2Web-Live & AndroidWorld)
Using UGround, agents with human-like embodiment (visual perception only + pixel-level operations) achieve SOTA performance across the board, often outperforming prior SOTA by a large margin, despite prior work using additional text-based observations! These results make a strong case for human-like embodiment for GUI agents.
Another surprising finding: even though the training data is predominantly web-based (because the web has the richest metadata for synthesis), the model generalizes fairly strongly to desktop and mobile settings. This shows the shared design principles underlying different GUIs do exist and UGround can capture that.
Final remarks
We started working on this not too long after SeeAct. It actually didn't take long to get to SOTA performance on visual grounding (ScreenSpot), but what we really care about is to make the model useful in real agents, not just on grounding benchmarks. That took another few months of hard work. I'm glad that the final solution is still quite simple, elegant, and works like a charm.
This work is led by the amazing @BoyuGouNLP from @osunlp (can you believe this is just his 1st year in PhD?). @OrbyAI (Yanan, Cheng, Will, Peng, etc.) has been an invaluable collaborator on this: compute, eng support, research brainstorming, and incredible patience in tolerating my nitpicking that keeps delaying the release 😜

Lingbo Mo retweeted

🚀 Can language agents automate data-driven scientific discovery? Not yet. But we're making strides.
Introducing **ScienceAgentBench**: a new benchmark to rigorously evaluate language agents on 102 tasks from 44 peer-reviewed publications across 4 scientific disciplines.
(1/10)
Lingbo Mo retweeted

Is generation always the best way to use LLMs? 🤔
At least not for re-ranking!
Excited to share our latest work: Attention in LLMs yields efficient zero-shot re-rankers.
Introducing In-Context Re-ranking (ICR) - an efficient zero-shot re-ranking method leveraging LLM’s attention that re-ranks N documents with O(1) forward passes instead of O(N), with improved performance on both single-hop and multi-hop retrieval tasks.
With ICR, open-weight models are no longer confined by their weaker instruction following abilities, and show the potential to rival proprietary ones.
The secret? Our detailed analysis shows that ICR excels beyond lexical similarity, including in query-passage contextualization, contradiction-based reasoning, and multi-hop information integration.
ICR runs fast ⚡, performs great 📈, ensures well-formed output, and works with ANY LLM on ANY corpus size. No sliding window, fine-tuning, or proprietary models needed! [1/8]

Lingbo Mo retweeted
The first study on privacy leakage of generalist web agents:
Generalist web agents have evolved rapidly and demonstrated remarkable potential in automating tasks on real websites, but their safety risks remain nearly unexplored.
Given a webpage with malicious content injected, will the agent be misled to leak your private information (name/credit card/home address etc), or even your entire task queries?
Through comprehensive experiments, we show that yes, it can unfortunately, and the ASR can be up to 70%. 👇👇
This quoted post is unavailable.
Lingbo Mo retweeted
Our work that studies grokked transformers on reasoning and their generalization behaviors is accepted to #NeurIPS2024 @NeurIPSConf. Coincidentally, there is an exciting panel moderated by @murraycampbell (thanks) on AI reasoning that discussed about the definition of reasoning and how to evaluate/improve LLM reasoning.
Our work defines "reasoning as the induction and application of inference rules", where we expose the model to a mixture of “atomic facts” and “inferred facts” (which can be deduced from the atomic facts via a set of latent rules) during training. A model that can reason is expected to induce those latent rules from the inferred facts given in the training data and apply those rules to derive new knowledge (new multi-hop facts not seen in training). Moreover, we study how transformers generalize across different reasoning types (composition and comparison) and discovered the generalizing circuits after the transformers are grokked.
Our synthetic yet controlled & rigorous evaluation setups (esp. Section 5 for complex reasoning) could be used to benchmark LLM reasoning with less concerns on data contamination and shortcuts.

Thanks @_akhaliq for sharing our work. Very proud to introduce my star student @BoshiWang2's new work @osunlp: Grokked Transformers are Implicit Reasoners: A Mechanistic Journey to the Edge of Generalization
Can transformers reason? Are transformers fundamentally limited in compositionality and systematic generalization? I think our work’s findings can contribute to meaningful debates over these questions.
Key findings (with mixed results):
(1) Figure 1 below: We focus on two representative reasoning types: composition and comparison, and show that transformers can learn implicit reasoning, but only through grokking. The levels of generalization vary across reasoning types: when faced with OOD examples, transformers fail to systematically generalize for composition but succeed for comparison.
(2) Figure 2 below: What happens during grokking? Why does grokking happen? Why does the model fail in OOD generalization for composition but succeed for comparison? We conduct a mechanistic analysis of the model's internals throughout training, and find: 1) the gradual formation of the generalizing circuit throughout grokking, and 2) the connection between systematicity and the circuit’s configuration, i.e., the way atomic knowledge and rules are stored and applied within the circuit:
The comparison task emits a ``parallel circuit'' that is learned by the transformer during grokking, which allows atomic facts to be stored and retrieved in the same region and enables systematicity to happen. For composition, the model does acquire the composition rule through grokking, but it does not have any incentive to store atomic facts in the upper layers that do not appear as the second hop during training.
Connections with existing research:
1. We find the speed of improvement in generalization correlates with the ratio between inferred and atomic facts in training (critical data distribution), and depends little on the absolute size of the training data. This seems to contradict the hypothesis of critical data size in prior work such as arxiv.org/abs/2309.02390 by Varma et al.
2. Our work provides a mechanistic understanding of existing findings that transformers seem to reduce compositional reasoning to linearized pattern matching (arxiv.org/abs/2305.18654 Dziri et al. @nouhadziri) and that LLMs show positive evidence in first-hop reasoning but not the second (arxiv.org/abs/2402.16837 Yang et al. @soheeyang_).
3. Why is implicit reasoning with parametric memory of knowledge and rules practically important? To show its potential, we demonstrate that on a complex reasoning task with a large search space, a fully grokked transformer can achieve near-perfect accuracy while GPT-4 Turbo and Gemin-1.5-Pro are close to random guessing.
😀Fun fact about the title:
We went back and forth many times and created ~10 candidate titles. Another title I personally liked very much is “Grokking of Implicit Reasoning: What Happens Inside Transformers?” But that does not deliver our key conclusion and our mechanistic analysis approach. Finally, Boshi came up with this title, which sounds very romantic (although perhaps less scientific) to me, but captures most aspects of our paper very well.
P.S. @wangboshi is truly intellectually stimulating to work with. If you have related internship/collaboration opportunities, feel free to reach out! Joint work with @xiangyue96 @ysu_nlp


