
Postdoctoral fellow at @VectorInst. ML PhD at UBC. Mathematical and computational structures for ML. Geometric and algebraic methods.
Orlando Florida
Joined August 2020
- Tweets115
- Following40
- Followers327
- Likes106




Pinned Tweet
#ICML2024
Can We Remove the Square-Root in Adaptive Methods?
arxiv.org/abs/2402.03496
Root-free (RF) methods are better on CNNs and competitive on Transformers compared to root-based methods (AdamW)
Removing the root makes matrix methods faster: Root-free Shampoo in BFloat16 /1

I still remember the comparison between SGD and Adam a few years ago. Empirical results may not support that. So, wait and see just like the SGD vs Adam lesson.

Slow is Fast: Is Muon the end of Shampoo?
kexue.fm/archives/11917
Orthogonal Slowest Descent — from a convex optimization convergence bound — washes away any Kronecker preconditioner's eigenvectors, leaving only eigenvalues to balance the gradient's spectrum — leads to Muon.
On one hand, it is essential to tune baseline methods well on a model. On the other hand, it may be better to avoid using a model/architecture that has been modified and optimized for a single method for 1.5 years.

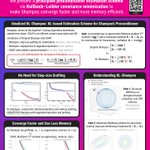
Some initial steps to make Shampoo and SOAP faster arxiv.org/abs/2605.26327 We are working on further improvements.

We will make Shampoo/SOAP, including KL-Shampoo/KL-SOAP, faster. Our goal is to match Muon's runtime while maintaining Shampoo/SOAP's strong per-step performance. Stay tuned for new updates.


Wu Lin retweeted
@weijie444 Looks like a KFAC-based method with modern clipping? G(ZZ^T)^{-1} is known as the FOOF update arxiv.org/abs/2201.12250 while msgn() can be interpreted as "generalized (preconditioned) gradient norm clipping" arxiv.org/abs/2506.01913 .


We released "The Newton--Muon Optimizer" . We show that Muon is secretly an implicit Newton method, and use this insight to build a better one. 1/n
Paper: arxiv.org/abs/2604.01472
This work builds on my ICML 2019 paper (with @MarkSchmidtUBC and @EmtiyazKhan), extending a variational Bayes-based geometric framework to modern NN optimization. It can be used to design methods for Bayesian inference, numerical optimization, and gradient-free optimization.
