

Research Scientist @GoogleDeepMind | AI PhD @CarnegieMellon | CS/Econ @PKU1898
Mountain View, CA
Joined August 2014
- Tweets49
- Following119
- Followers691
- Likes14

Lijun Yu retweeted

Alex Hauptmann, a research professor in the Language Technologies Institute whose Carnegie Mellon University career spanned some 42 years, died Oct. 7 following a bout with frontotemporal dementia. He was 67.
bit.ly/4zQOgnD

Much as we would like to learn world modeling from video diffusion, our new benchmark shows that the current models don’t actually work - check out the FlipTest and reconsider your bet

World models promise to predict the future. But can they predict the RIGHT future given the CURRENT state?
Excited to share FlipTest, my work from Google DeepMind internship during the summer.
In the physical world, 1 mm decides whether an object stays or falls. When a tiny change crosses a tipping point, a true world model must flip its prediction.
Blog: romyluo.com/blog/fliptest/
Do today’s video world models pass the test? 🧵[0/8]
Lijun Yu retweeted

Exciting news: Gemini 4 Carbon (High) from @GoogleDeepMind just made a huge debut on Arena, landing #1 in Text Arena, #2 in Agent Arena, and #4 in Code Arena: WebDev. Back at the top, Gemini 4 Carbon delivers frontier intelligence and reshapes the Pareto frontier across three arenas.
In Agent Arena, Gemini 4 Carbon ranks #2 with a +16.2% net improvement across +21.9K real-world agentic sessions from our global community, surpassing top models GPT-6 Astra and Fable-5.1. At $1.80 median cost per task, Gemini 4 Carbon (High) costs 72% less than the #1 ranked Claude Opus 5.5 (Max).
Its standouts by key signals:
- #1 Steerability (+18.6%): can the model course-correct when you push back?
- #2 Praise vs Complaint (+37.9%): implicit sentiment in users' reactions
- #3 Confirmed Success (+18.7%): explicit “yes, that worked” from users
In Code Arena: WebDev, Carbon scored 1768 pts landing #4:
- Just 2 pts below #3 Claude Sonnet 5.5 (xHigh), at 1770 pts
- 89 pts above #11 Gemini 4 Argon (High), at 1679 pts
By category, it ranks #3 in Gaming and Simulations, and #5 in Brand & Marketing.
In Text Arena, Gemini 4 Carbon (High) is the new #1 with 1528 pts, now ahead of Gemini 4 Argon (High) at #2 with 1520 pts.
Congrats to the @GoogleDeepMind team on this huge milestone!


Lijun Yu retweeted

Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas.
As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
Key results for Gemini 4 Carbon with high reasoning:
➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out
➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671
➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index
➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M)
Congratulations to the @GoogleDeepMind team!

RSI brings you, Gemini 4 Carbon, and non-stoppable from here!

I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!

2
9
366
Lijun Yu retweeted
Big news: Gemini 4 Argon (High) by @GoogleDeepMind just landed #1 in Text Arena with 1525 pts, and #8 in Code Arena: WebDev with 1679 pts!
This release has reshaped the Text Arena Pareto frontier with a blended $8/MToken! Gemini 4 Argon (High) is now the most cost efficient model, see its placement on Pareto frontier below.
In the Text Arena, Gemini 4 Argon (High) ranks #1 in Coding, Hard Prompts, Instruction Following, Longer Query, and Creative Writing. It also leads every occupational domain evaluated, with additional #1 spots in English, Non-English, Chinese, and Russian.
This model is +20 points above the #2 ranked Claude Opus 4.6 (High), and a huge leap from Google’s previous release, Gemini 3.8 Flash (High) at #11!
In Code Arena: WebDev, Gemini 4 Argon (High) gained +96 points from Gemini 3.8 Flash (High), and went from #29 to #8.
Congrats to the @GoogleDeepMind team on this impressive frontier release!


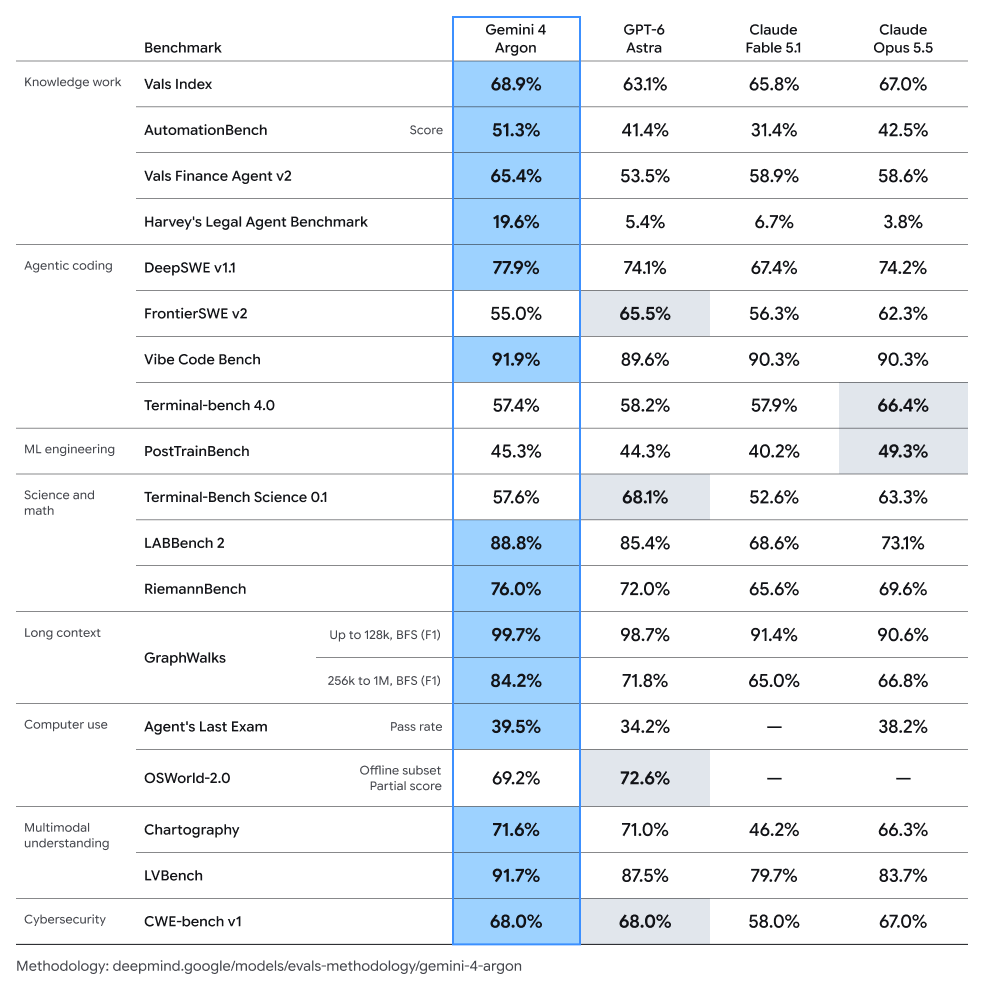
It's here, the model we've been cooking! Fortunate to have been part of it from pretraining to post-training, pushing the frontier across capabilities.
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
1
11
745
Lijun Yu retweeted

So thrilled to finally launch the System Prompt Index and release our AISPA framework!
There’s still a huge gap in transparency and accountability in the AI era. Stay tuned!
👇Our fancy poster for the work we demoed at @BerkeleyRDI


Gemini Omni Flash allows you to create videos from anything, while demonstrating a significant leap on conventional tasks like text-to-video! Glad I'm been on this fantastic journey from Veo to Omni.

Exciting news: Gemini Omni Flash is now #1 in the Video Arena (both Text-to-Video and Image-to-Video)!
For Text-to-Video this is a massive +158 pt improvement over Veo 3.1 (1080p) and a large +61 pt lead over the next best model, Seedance 2.0.
Congrats @GoogleDeepMind for this huge milestone!

2
516
Proud to introduce Gemini Omni - a peek of multimodal super intelligence that we have been cooking for the future
Lijun Yu retweeted

We’re launching Nano Banana 2, built on the latest Gemini Flash model. 🍌
It’s state-of-the-art for creating and editing images, combining Pro-level capabilities with lightning-fast speed. 🧵
Lijun Yu retweeted
We’ve upgraded our specialized reasoning mode Gemini 3 Deep Think to help solve modern science, research, and engineering challenges – pushing the frontier of intelligence. 🧠
Watch how the Wang Lab at Duke University is using it to design new semiconductor materials. 🧵
Lijun Yu retweeted
How could AI act as a better research collaborator? 🧑🔬
In two new papers with @GoogleResearch, we show how Gemini Deep Think uses agentic workflows to help solve research-level problems in mathematics, physics, and computer science.
More → goo.gle/4aGs3Pz

Lijun Yu retweeted
We’re pushing the boundaries of intelligence even further with Gemini 3 Deep Think. 🧠
This mode meaningfully improves reasoning capabilities by exploring many hypotheses simultaneously to solve problems.
Here’s how it coded a simulated dominoes game from a single prompt ⬇️
Lijun Yu retweeted
Gemini 3 Deep Think mode is now live in the Gemini app for Ultra users. 🚀
Building on the technology that reached a gold-medal level at the ICPC World Finals & IMO, it uses parallel thinking to excel at difficult coding and scientific tasks. bit.ly/48EPzdz

Check out our new paper on the future of pixel space generative pretraining, and the insufficiency of current compute! This is one more evidence for the ever growing compute need, and by 2030 we can make this happen :)

For years, RAW pixel space pretraining has been sidelined: too compute-expensive.
Our new @GoogleDeepMind paper 📜 dives into the scaling trends of raw pixel models to answer the question “how far are we from scaling up next-pixel prediction?”
arxiv.org/pdf/2511.08704
Forecast: Raw next-pixel modeling will reach competitive ImageNet classification (>80% top1 accuracy) and generation metrics (90 Fr’echet Distance) in five years!
Threads 👇

ALT Rethinking generative image pretraining: How far are we from scaling up next-pixel prediction?
Meet Nano Banana Pro 🍌🍌🍌, bringing image generation and editing to a whole new level with Gemini 3.
Lijun Yu retweeted
🚨BREAKING: @GoogleDeepMind’s Gemini-3-Pro is now #1 across all major Arena leaderboards
🥇#1 in Text, Vision, and WebDev - surpassing Grok-4.1, Claude-4.5, and GPT-5
🥇#1 in Coding, Math, Creative Writing, Long Queries, and nearly all occupational leaderboards.
Massive gains over Gemini-2.5:
🔸WebDev in Code Arena: 1487 (+280 pts vs 2.5)
🔸Text: 1501 (+50 pts)
🔸Vision: 1328 (+70 pts)
🔸Arena Expert: Top-3 (just 3 pts behind #1)
Huge congrats to the @GoogleDeepMind team on this breakthrough! 👏

Introducing Gemini 3 ✨
It’s the best model in the world for multimodal understanding, and our most powerful agentic + vibe coding model yet. Gemini 3 can bring any idea to life, quickly grasping context and intent so you can get what you need with less prompting.
Find Gemini 3 Pro rolling out today in the @Geminiapp and AI Mode in Search. For developers, build with it now in @GoogleAIStudio and Vertex AI.
Excited for you to try it!
Lijun Yu retweeted
🧵 Why Veo 3.1 ranks #1 on the Video Arena, and Sora 2 went viral.
Sora 2 by @OpenAI captured massive attention, but the community has shown us that @GoogleDeepMind's Veo 3.1 leads on core model quality. The difference comes down to two standout features that fueled Sora 2’s rise:
🧑🤝🧑 Cameos & 📚 Narratives
Let's dive into these in the thread 👇

🚨🎬 Big news from Video Arena!
@GoogleDeepMind’s latest Veo 3.1 now ranks #1 in both Text-to-Video and Image-to-Video leaderboards. 🏆
This is a +30-point leap from Veo 3.0 → 3.1, making it the first model to break 1400 in Video Arena history!
Huge congrats to the @GoogleDeepMind team for pushing the frontier of video generation forward!
More details in the thread 🧵
