
Approximate Labs
Joined July 2009
- Tweets598
- Following757
- Followers349
- Likes3.5K




Anyone know how to make codex tui /goal not give up when it runs across a "Selected model is at capacity. Please try a different model."
It kicks it out of a large running thing (may be all night) and I lose a full night of work. (goes into goal stalled state)
Claude and Codex TUI harnesses are getting a lot less reliable for overnight/long runs. Annoying permission prompts when in --yolo, capacity limits stopping auto-retries, false-cyber claims, etc.
I previously (for months) would rely on /goal or /loop to keep systems running over night, but it's failed repeatedly recently
75,000 tok/s output feels wild. Deepseek v4.1 flash as a backbone for fleets on a B300x8 machine is amazing.

I'm obsessed with running fleets/swarms now.
Feels so different to command a fleet of 1024 agents at once (compared to ~2-10 tui coding sessions).
So excited to launch this to let others try it
The swarm has grown to 2048 agents. Working on balancing the harness, system setup, and more. Got boot time for 2048 vms down to ~2 minutes.


Anyone have any problems they want a swarm to run on?
I've got the setup going, pushing scale right now, first test of 512 and 768 agents each with their own VM, all collaborating, both worked super stably. (GLM-5.3)

What are the best ways to keep your mind sharp while agents do more and more wok?
directly study with chatbots?
spaced repetition / anki?
video games?
puzzles?
reading books?
something else?
Exciting early craftax result! (still very rare, 1 win in ~75k seeds)
hoping the recipe will keep climbing and make it more common

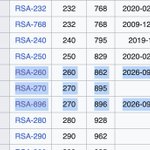
TIL RSA-896 is 896 for 896 bits vs. the recent RSA-260 where 260 meant 260 digits.
I kinda wish they were labeled with a b or d.
eg. RSA-896b == RSA-270d to disambiguate.


636606729769440499166579950236036751749912014371509557713570027508971809534551913252252094954941974952859310861988904737359709200557919
is a factor of RSA-896
saweis.net/posts/rsa-896.htm…
Here are 5 solves for Craftax that run for selected seeds (4, 6, 42, 420 and 1337) of the unmodified 1.6.1 craftax w/ JAX 0.6.2
approximatelabs.com/craftax

In 7 minutes: codex solved a brightness papercut on studio display xdr, actual software control of brightness (not just relying on ambient light).
"Apple internally calls the hidden boost system Aurora. I reverse-engineered the private per-display setter"
Thank you codex

Been playing with this, and found some early signal where it helps language modeling: When you're forced to repeat a fixed dataset, it overfits later and less.


We discovered a third pretraining axis beyond parameters and data: exploration.
Scaling exploration monotonically improves existing models across images/video/language, and unlocks end-to-end generation.
In the simplest case, it's just a for loop.
Introducing Explorative Modeling.
TLDR:
- Gains from exploration grow with scale: 7%→36% as data scales, 13%→23% as parameters scale, and gains double at 3× the compute
- Adding exploration to ~SOTA baselines improves data efficiency by 6.2×, FLOP efficiency by 4.1×, parameter efficiency by 47%, and hits a near-SOTA 1.43 unguided FID on ImageNet
- Exploration lets you trade training compute for generalization, and scales how end-to-end your generative model is
- End-to-end Explorative Models (XMs) match diffusion performance on control tasks with up to 256× less inference compute
🧵Thread:


Fable almost got 100% on pencil puzzle bench
Only failures are heyawake puzzles where it spent over $500 in turns trying to figure out the syntax to make moves (there are example moves given to it in context and other heyawake it did solve...)

