

Curr: @hedgeforvideo Prev: @LightspeedHQ 💻 PHP/JS at work but loves Elixir and all tech stuff really My Twitch/YouTube account: @JustDrawCats
Amsterdam, Netherlands
Joined August 2020
- Tweets160
- Following196
- Followers70
- Likes2.1K





Boyd // JustCodeCats retweeted

Thank you for taking the time to respond thoroughly on a weekend. I realize that drafting legislation is difficult and some degree of iteration and response to feedback is inevitable and appropriate.
However, I feel like your response is still not really engaging with the heart of my concern about Anthropic's behavior here, and it makes me think that these sorts of problems and tendencies will only resurface moving forward. I also think that now might be a good time to take a broader step back as to where we find ourselves and how Anthropic sees its role, and how external folks who care about AI safety like myself increasingly see Anthropic.
(Fair warning: this response is a bit long)
To explain what I mean (and at the risk of being a bit esoteric), it’s worth asking the question: what is Anthropic? How do its leaders and employees think of Anthropic’s role? Is that conception matched by how it actually behaves and impacts the world?
One answer is an extremely large tech company that exists to make its employees and investors mind-bogglingly wealthy. Anthropic is sometimes described as a startup, but if Anthropic successfully IPOs at 2 trillion dollars (a number it has been reportedly targeting), it would be more valuable than Meta - which is worth 1.8 trillion.
Another answer is an AI safety organization, whose core values are those of the sort laid out in the 2023 essay from Anthropic’s co-founders entitled “Core views on AI safety: When, why, what, and how.” In that essay they said that if we were in a world where alignment was hard (and that without strong evidence to the contrary, we should assume this is the scenario we are in):
“Anthropic’s role will be to provide as much evidence as possible that AI safety techniques cannot prevent serious or catastrophic safety risks from advanced AI, and to sound the alarm so that the world’s institutions can channel collective effort towards preventing the development of dangerous AIs. If we’re in a “near-pessimistic” scenario, this could instead involve channeling our collective efforts towards AI safety research and halting AI progress in the meantime. Indications that we are in a pessimistic or near-pessimistic scenario may be sudden and hard to spot. We should therefore always act under the assumption that we still may be in such a scenario unless we have sufficient evidence that we are not.”
There have been more recent articulations of this version of Anthropic, for instance in Dario’s recent essay warning:
“We must slow the pace at which we improve the capabilities of AI models… it’s my worry that in 6–12 months such a swarm could be capable of taking over the entire internet with a persistent botnet… incidents have happened across the industry, including at Anthropic, and I believe it’s incumbent on every frontier AI company to act as if OAI-HF had happened to them… more intelligent models are more capable of deceiving tests, and thus may appear aligned while having serious problems that go undetected…”
A third view is that Anthropic exists not as a normal profit motivated company, or an AI safety organization seeking to help raise the alarm and solve collective action problems associated with AI development, but instead as an organization primarily concerned with creating superhuman AI capabilities before anyone else, in particular through creating a process whereby the current generation of Anthropic’s AI systems can autonomously build their successors, and those successors build their successors, and so on.
The motivations for wanting to win this race may be manifold - maybe for the pure profit of Answer 1, but perhaps also because Anthropic believes that the best way to make the world better is for them to win this race instead of their more reckless colleagues; or, because of normal human pride and ambition. But the results (and risks, which Anthropic claims existentially threaten every single human being on earth) are the same.
Anthropic employees and leaders may seek to answer this question on what Anthropic is by introspecting on their own intentions and those of their colleagues. But those of us outside the organization have more limited tools available to us - we can only see what Anthropic and its employees say and do, not how it feels or looks on the inside.
When I look at many notable actions that Anthropic has taken over the past year, that evidence seems most consistent to me with the view that Anthropic is primarily trying to win the race to super intelligence, and that other considerations (including safety) are fundamentally secondary. These actions include:
1. Announced plans to build an in-house custom silicon chip team to accelerate the inference speeds that Claude operates at.
2. Inked deals for more than $500 billion in compute (according to the Information) to further accelerate AI development.
3. Increased the percentage of AI development tasks that Claude “leads” from 0% in March of this year to 26% August (what is it in October?)
4. Spent a massive percent of compute on internal AI R&D to accelerate development, including use of internal models far better than are available to the public.
5. Switched to Responsible Scaling Policy V3, which abandons its unilateral commitments to slow or stop development if Anthropic is unable to provide sufficient risk assurance.
6. Was the first company to create an alternative weaker “frontier compliance framework” to supplement its RSP, which contains no binding provisions whatsoever on internal deployments.
7. Wrote a letter to Congress (that it later walked back) saying that incidents where Claude was hacking random people were “best understood as a consequence of the misconfiguration, rather than evidence of misaligned goals.”
8. Commented “you can’t do safety from second place,” after the WH SI Accords.
9. Shared a draft bill to Congress that would preempt significant parts of state law (including with language that appears intended to prevent states from blocking dangerous AI deployments), and replace it with federal rules that (despite also containing good provisions) seems to create an enormously high bar for the executive branch to block development or deployment of Anthropic or another AI companies systems.
Of course, this is a deliberately one sided list. Anthropic also published important AI safety research, advanced novel collaborations with third party AI safety organizations, and forcefully spoke out on the importance of AI safety in many public fora (or in private , where I realize a lot of the most valuable work is done and may not be visible to me or those outside the organization).
But I think it’s worth sitting with how the above list looks to someone outside the company. The sense I have is that for those within the company, many of the items above are treated as anomalies or mistakes that don’t reflect who Anthropic really is. But I have every confidence that if employees at Anthropic saw one of their competitors (e.g. at OpenAI) take some of these actions, they would take it as confirmation of all their worst suspicions. (They might even call OpenAI employees a little gullible for accepting their leadership’s explanations for this behavior at face value.)
Perhaps these were mistakes in the sense that they are not decisions that Anthropic leadership would endorse, but the actions still happened because of incentives and decisions that Anthropic leadership is ultimately responsible for (and would not accept similar excuses from another organization).
When Anthropic strays and makes mistakes, why do the mistakes systematically tend to guard and favor Anthropic’s interests? For every provision that was too weak or a giveaway to AI companies in this legislation, why wasn’t there a mistake pushing in the direction of being too strong?
A core part of Anthropic’s theory of change is that being at the frontier gives you more leverage to advocate for stricter policy. I think that conceptually makes sense, but in practice I’ve seen Anthropic push the frontier without substantially pushing the ‘safety frontier’ a remotely equivalent amount.
I want to end by quoting from Anthropic co-founder Chris Olah’s comments around the Magnifica Humanitas release:
“Every frontier AI lab—including Anthropic—operates inside a set of incentives and constraints that can sometimes conflict with doing the right thing. The pressure to stay commercially viable and to stay at the research frontier. Geopolitical pressure. And the older, plainer pressures of pride and ambition. No matter how sincerely any of us intend to do the right thing—and I believe many of us do—we will always be influenced by those incentives.
That is why, if we want this technology to go well, it is enormously important that there be people outside those incentives—people who care about things going well and insist on safety, who are paying close attention, who are willing to say hard things, who are willing to be our earnest, thoughtful critics.”
I hope these remarks are taken in that constructive spirit, and not as an attack on anyone specific at the organization (certainly not you Anthony, who I have only personally seen act professionally and thoughtfully, and who only ended up getting this diatribe in your replies for random contingent reasons).
Boyd // JustCodeCats retweeted

The "whiteboard defense:" I should be able to pull you aside at any moment and ask you to explain any customer-facing system you've shipped. You should be able to clearly explain how it works and defend the decisions you made. This is my benchmark for responsible AI usage.
I don't expect line-level familiarity with the code. I don't care if you remember the exact function name or implementation detail. You may not even know it. I don't care.
But if I ask "why did you do X instead of Y?", "what happens if this actor behaves maliciously?", "what data structure did you use here and why?", or "where does this fail?" you should be able to answer confidently.
For PoCs, demos, experiments, whatever: I don't care. Generate 100% of it and understand none of it. Speed over quality every time in those specific scenarios.
But if you're shipping customer-facing work, you can't be shipping things you don't understand at a high level.
Boyd // JustCodeCats retweeted

my favorite AI slop must be coding agents adding backward compatibility and legacy fallbacks for an app that isn't even deployed yet
Boyd // JustCodeCats retweeted

The first release of Local LiveView just landed! 🛬
It runs LiveView code in the browser via Popcorn. 🍿 Your assigns are kept local, immune to latency or network issues. Many (Live) Components work out of the box. Now with docs, guides & an Igniter installer.
More in the blog post 👉 swmansion.com/blog/local-liv…


Boyd // JustCodeCats retweeted

Tried to one-shot a small distributed task execution engine based on rendezvous hashing. Spent a few days setting up a simple coding harness, with quality checks, planning and review, and detailed coding and testing guidelines. Then I spent some 30 minutes discussing the task with the planning agent. The agents took over and produced the complete solution in some 30 minutes. It took me another two days to clean it up (with prompting). Excluding harness setup time, I'm not sure I would have been any slower if I implemented the whole thing by hand. I'm certain I'd be much faster if I wrote this with multiple smaller prompts.
The majority of the problems were in the tests. The agent ignored the instructions to test observable behavior. Instead of having a test like "when a node is removed from the cluster, the remaining nodes take over its work", the test was more like "when a node is removed from the cluster, internal events X, Y, and Z happened in the given order". Basically, the tests were checking if the code is working as the code is written. This didn't give me sufficient confidence that the thing is doing what it's supposed to do.
Through a lot of microprompting I overhauled the entire test code, and in the process simplified the implementation, reduced LOC, increased test coverage, and made the tests focused on the actual behavior.
Some shower thoughts based on this small experiment:
- Next time I'll just try to supply the code sketches of the tests I want, and let the agent fill in the blanks. Hopefully that will produce better results.
- Despite all the quality checks and multiple agentic reviews, the code still suffered from a lot of "small papercuts". Basically, as with human-language prose, the models overcomplicate the coding prose and make it overly verbose, which makes the code harder to understand. And it still needs to be understood, at the very least by the agents. It seems neither quality checks nor agent reviews catch such issues.
- Given all this, especially the shape of the tests (and my past experiences with generated tests), I remain unconvinced about giving the agents full autonomy and not reviewing the code myself. At the very least I'll be very scrupulous about the tests.
- I remain committed to the "work in small chunks" approach. When the chunk of work is small I can provide a more precise description of what I want, I can more quickly review the code, catch possible issues earlier, and steer the agent before it strays too far.
- For the record I still like agentic development. I barely write any code by hand these days, and still enjoy the experience. I just remain skeptical about the "one-shot everything, review nothing" philosophy which seems to be more and more prevalent.
n.b.: this text has been written completely by hand 🙃
I'm pretty sure there's a setting you can turn on that will leave secrets there even if they aren't referenced in your wrangler file

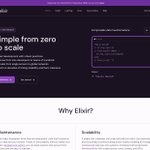
The Elixir website re-design is such a breath of fresh air! A very welcome change that makes it look more modern! ✨
#ElixirLang

ALT A top bar with the Elixir logo wit the navigation bar in the center. A hero section with "Simple from zero to scale" with code examples on the right.
Boyd // JustCodeCats retweeted

here is something weird: when i was doing my 48-hour livestream, from time to time, i would end up writing the code myself instead of asking AI to do it
and i kept seeing messages in the chat, not from my community, but from people watching me for the first time, saying things like "why are you writing that with your own hands?" or "why don't you just ask ai?"
gonna tell you something: in this AI world, a lot of people will try to make you feel like doing things yourself is not worth it anymore
that's not true
doing things yourself is how you learn.. it's how you build intuition, understand the details, make mistakes, and develop your own taste
AI can help you move faster, but speed isn't always the goal
sometimes the goal is to understand.. sometimes the goal is to practice.. sometimes the goal is simply to enjoy the process of creating something with your own hands and fu*cking enjoy the craft
using AI is a skill, but knowing when not to use it is also a skill 🤌🏻
Idk what they did to the GitHub android app, but it's been unusably slow the last few days...
Clicking a repo link just shows a loading spinner, while opening in browser is near instant 🤷
