

AI Educator | Teaching you how to earn smarter with AI, automation & digital skills | 📩 DM Open for collaboration
Joined January 2026
- Tweets606
- Following11
- Followers41.7K
- Likes293


John Benjamin retweeted

HeyGen just entered the AI video arena and took the #1 spot. This is a serious breakthrough.
🤝 Paid partnership

HeyGen Video 1 went up against today's leading video models in a blind test on @ArtificialAnlys.
Our first general-purpose video model ranked #1 in text to video.
Try it: platform.heygen.com/models/h…
John Benjamin retweeted

The AI video race just got more interesting. HeyGen Video 1 ranks #1 in text-to-video.
🤝 Paid partnership
HeyGen Video 1 went up against today's leading video models in a blind test on @ArtificialAnlys.
Our first general-purpose video model ranked #1 in text to video.
Try it: platform.heygen.com/models/h…
John Benjamin retweeted

HeyGen isn’t just for AI avatars anymore. It’s now competing with the best video generation models.
🤝 Paid partnership
HeyGen Video 1 went up against today's leading video models in a blind test on @ArtificialAnlys.
Our first general-purpose video model ranked #1 in text to video.
Try it: platform.heygen.com/models/h…
John Benjamin retweeted

A new AI video model just beat Wan 3.0 and Seedance 2.5 in a blind test.
🤝 Paid partnership
HeyGen Video 1 went up against today's leading video models in a blind test on @ArtificialAnlys.
Our first general-purpose video model ranked #1 in text to video.
Try it: platform.heygen.com/models/h…
John Benjamin retweeted

Underrated release of the week: OXR 👇
1.3B. #1 on olmOCR-Bench, OmniDocBench and DocParsingBench.
PaddleOCR-VL-1.6: 144.7 s/100 pages on an RTX PRO 6000. OXR: 101.0 s, fastest open source.
Pluggable layout, RSI.
github.com/SoMarkAI/OXR
🤝 Paid partnership


John Benjamin retweeted

Before the spotlight, there’s the practice room.
Give your AI idol a dance practice concept with Seedance 2.5 on APOB AI. Casual fits, studio mirrors, full-body framing. Make those 30 seconds all about the choreography.
Try it now: mega.apob.ai/shanto
John Benjamin retweeted

30 seconds gives AI video room to breathe.
APOB AI now supports Seedance 2.5 30s Video, making it easier to create cinematic scenes with camera movement, atmosphere, character action, and smooth story progression.
Try it now: mega.apob.ai/Aria-Arooj
John Benjamin retweeted

HeyGen holds the top two spots on the @ArtificialAnlys text to speech leaderboard.
#1 HeyGen Voice Turbo
#2 HeyGen Voice
Turbo is the faster, cheaper mode of the voice model behind every HeyGen video. It's live on the API, and the Turbo endpoint is free until November 30.
John Benjamin retweeted
AI influencers are redefining digital marketing. Brands that adapt early could have a huge advantage.
🤖 Made with AI

John Benjamin retweeted
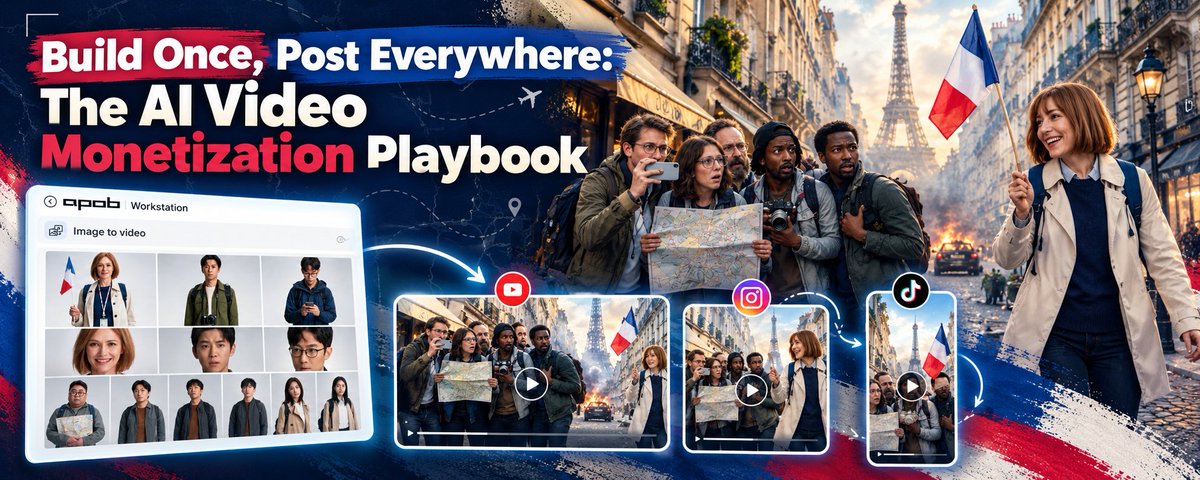
Your AI influencer, your K-pop dance crew! 💃🔥 Create stunning 30-second AI dance videos with APOB AI + Seedance 2.5.
#AIInfluencer #APOBAI
🤝 Paid partnership · 🤖 Made with AI

John Benjamin retweeted
Create stunning AI videos with APOB AI + Seedance 2.5 Perfect for every AI influencer! 🎬
🤝 Paid partnership · 🤖 Made with AI
John Benjamin retweeted

EAGLE-4 is here.
From EAGLE-1 to EAGLE-3, we’ve kept making inference faster.
EAGLE-4 is our fastest yet.
961.6 tokens/s on @Alibaba_Qwen’s Qwen3.8-27B with TokenSpeed (BF16, 4× @NVIDIA B300, TP4, one request, T=0).
Github: github.com/eagle-hq/EAGLE-4
John Benjamin retweeted
Open weights, MIT license, and impressive benchmarks. Ornith-1.5-122B gives developers more freedom to innovate.
🤝 Paid partnership

Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast
Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!!
Open weights under the MIT license.
Coding
✅SWE-bench Verified: 0.845
✅TB2.1: 0.813
✅CyberGym: 0.800
✅NL2Repo: 0.512
Agentic
✅HLE: 0.446
✅BrowseComp: 0.785
✅MCP-Atlas: 0.746
✅Toolathlon: 0.708
🤗Hugging Face: huggingface.co/ornith-ai/Orn…
We can’t wait to see what you build with Ornith-1.5-122B.

John Benjamin retweeted
One reference prompt can transform your editing workflow. Imagine combining viral hooks, cinematic B-roll, and engaging captions into one seamless video.
🤝 Paid partnership

John Benjamin retweeted
About 560B total parameters, around 25B active per token. Ling-3.1-flash is now open source. Worth keeping those two numbers separate when thinking about inference: active parameters are not the same thing as the full model's storage requirements.

John Benjamin retweeted
Ming-3.0 includes a 0.5B TTS model for voice design and paralinguistic cues. That's the part I'd start with: not just generating the words, but shaping how they're delivered.
Today, we're open-sourcing 5 Ming-3.0 models across 3 speech families.
- Ming-3.0-tts: 0.5B voice design & paralinguistic cues; Tiny 7.9B A1.3B long-form speech.
- Ming-3.0-audio: Flash 126B A6.5B understanding & tools; Tiny 9.3B A2.7B efficient dialogue.
- Ming-3.0-asr: Tiny 8.6B A2B dialects & context.


John Benjamin retweeted
Imagine turning any book into a natural-sounding audiobook with just a simple prompt. AI keeps getting better.
🤝 Paid partnership
John Benjamin retweeted
No audiobook available? Now you can create your own with HeyGen Voice and ChatGPT.
🤝 Paid partnership
John Benjamin retweeted
This is how AI makes knowledge more accessible. Any book, any time, with incredibly natural narration.
🤝 Paid partnership
John Benjamin retweeted
HeyGen Voice is making any book accessible through high-quality AI narration. This is a game-changer for readers.
🤝 Paid partnership