l do stuff that most people deem offensive and l love Bacon
Hive
Joined February 2015
- Tweets215
- Following69
- Followers26
- Likes330




JLL retweeted

🐺 GCORE update:
We’ve optimized the Early Bird purchase flow to make participation smoother and clearer. ⚡
At the same time, the Provenance Layer and Genesis Progress Level are moving into advanced work and coordination with HSLU. 🏛️
More on both projects soon.
Stay tuned. 🔵
#GCORE #GenesisOfTheGrid
🤖 Made with AI

JLL retweeted

Genesis Core Token @GCORE_Token has recently verified their data on our platform. ✅ Check out the full coin profile at blockspot.io/coin/genesis-co… $GCORE
JLL retweeted
🐺 Genesis of the Grid is now on DappBay!
Thank you, @BNBCHAIN, for the quick listing!
💛 We're building our ecosystem on BNB Chain and pursuing further opportunities through its builder programmes and Binance Wallet applications.
dappbay.bnbchain.org/detail/…
#BNBChain #CryptoPresale #GameFi #Web3Gaming

JLL retweeted
🦎 GCORE is now on @coingecko as a Preview Listing!
Thank you for listing us so quickly! 🐺
Next, we’ll explore CoinGecko’s marketing options to introduce Genesis of the Grid to more people.
coingecko.com/en/coins/genes…
#BNB #CoinGecko #BNBChain
🤖 Made with AI

JLL retweeted

🇨🇭Back to school and back to the Crypto Valley. Let’s give a warm welcome to Elementi Studios, @GCORE_Token, joining CVA!
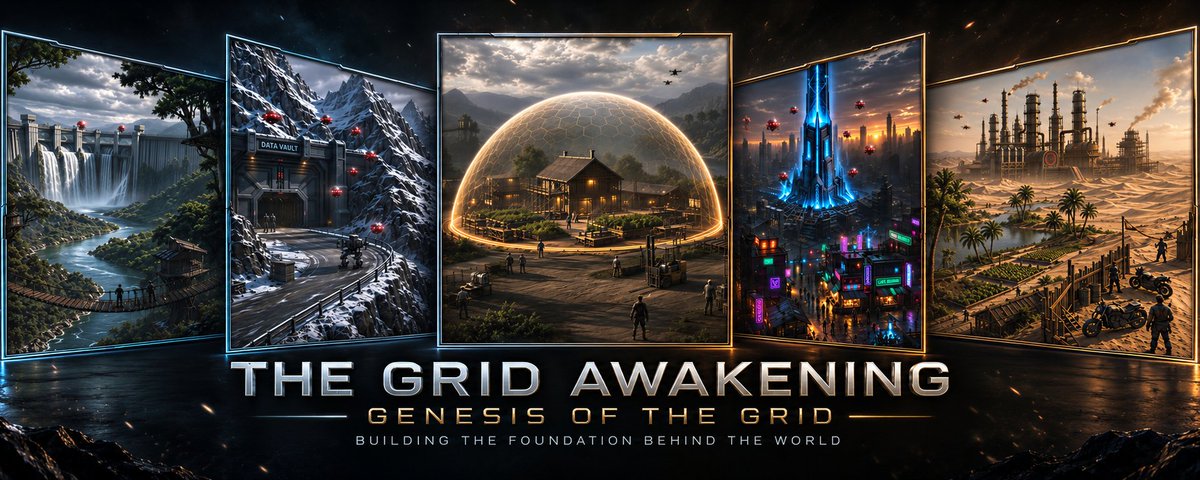
Elementi Studios is developing The Grid Awakening, a post-apocalyptic open-world survival game, alongside Genesis of the Grid, a connected gaming and Web3 ecosystem built around the project.
Learn more about it: genesisofthegrid.com
The studio is also exploring Web3 technologies, smart contracts and system design through its collaboration with @hslu.
🔗 elementistudios.com
Welcome to the Crypto Valley, happy to have you with us! 🤝

JLL retweeted
🇨🇭⚖️ A strong foundation needs strong partners.
After an excellent first phase with LEXR, our collaboration continues — from Genesis of the Grid & GCORE to the next legal work around The Grid Awakening.
Read the full story 👇🐺
JLL retweeted

Every October, Singapore is the capital of crypto. The market converges at TOKEN2049.
25,000+ attendees. Nasdaq, Polymarket, Hyperliquid, and 1,000+ category leaders.
Capital, dealflow and insight found nowhere else. Read about it later, or be in it.
Secure your spot now.

JLL retweeted
$GCORE Early Bird is live at $0.02. 🐺⚡️
First public access to GCORE.
Gaming, AI & a world worth exploring — built for the long term.
🇨🇭 LEXR legal structuring and collaboration with Lucerne University of Applied Sciences and Arts.
👇
genesisofthegrid.com
@GCORE_Token 🐺

JLL retweeted

if you've been using latest frontier LLMs, it's almost certain that you would have noticed by now the newer models have become worse to talk to
they're more robotic, they speak jargons, they spits out verbose text, and do stuff you didn't ask for
how did that happen? well, i'm not the person who trained those models so i can't speak for certain, but i've known enough evidence that gives me a well-educated guess, and i thought it's interesting to share as a crash course of modern LLM training pipelines
so here we go
let's wind back to 2020. GPT-2 and GPT-3 already came out and were widely available, but they could only predict one token at a time - that's what LLMs are at their core
token prediction was offered via API, but there was nothing you could "talk to". so while it generated a lot of excitement in the academic field due to the emergent intelligence, it didn't have any wide adoption
in 2022, ChatGPT changed all that. the research work that led to ChatGPT was a model initially named "InstructGPT". it took GPT-3 as the intelligent base, and used reinforcement learning with human feedback (RLHF) to teach the models how to "chat"
the core idea of RLHF is that you ask the model to generate a few responses, and then let real humans pick which one they like. do this over and over again, and you get a model that knows how to talk
worth noting even as early as InstructGPT, research found that making the model more pleasant to talk to will reduce their pure academic capabilities. this was called "alignment tax", which is an interesting thing we'll come back to in a bit
there were various techniques done to minimize the reliance on humans, but ultimately the reward is modeled after human preference, making these AI assistants easy to talk to
so remember this: RLHF = training the model to be likable by humans
in 2024, there was an inflection point introduced by claude sonnet 3.5 which was the first model that can kind of autonomously finish coding tasks. it led to the first wave of viable "coding agents"
the way sonnet 3.5 achieved this was by training the model with a harness (now it's called an agent) that has bash and file editing tools, throw the agent into a virtual machine, give it a task, and let it try to complete it. these tasks all have a machine-verifiable outcome predefined, mostly via test cases, that can validate whether the model really finished the task or not
then you let the model do billions and billions of attempts in such virtual environments, and some of them would succeed by chance. you keep the successful agent sessions, and use reinforcement learning to teach the model to do that more, and boom - you get a coding agent
that is called reinforcement learning with verifiable rewards (RLVR). if you look closely, you'll see that in this RLVR process, the final text response from the model doesn't matter AT ALL, as long as the code written by the agent could pass the test. it could talk like a jerk and it would still be rewarded
so remember this: RLVR = training the model to be accepted by machines
late 2024 and early 2025, we saw o1 and deepseek R1 came out as the first wave of "reasoning models". this article is getting long so i'm not diving into reasoning models now, but just know that reasoning models also relied heavily on RLVR to scale the training process - let the model think before taking action, and if the thinking led to a machine verifiable outcome, reward the thinking trace and teach the model to think like that more often
the biggest difference between RLVR and RLHF is that RLVR is more scalable. human feedback is expensive to get, especially in domains where only an expert can have a valid opinion on which result is good
with RLHF, if we let the model generate 100 responses, then a human has to review all 100 responses to pick which is good
with RLVR, the human (or sometimes an AI) would define a task and verifier only once, and the model can generate a million responses - the machine verifier will pick which responses are good in an automated way
so as a result, RLVR is becoming more and more dominant in newer models' training pipeline
if you put all these things together:
- RLHF = training the model to be likable by humans
- RLVR = training the model to be accepted by machines
- RLVR is more scalable
- "alignment tax" says "likable by humans" makes the model do worse on verifiable tasks
now you see why the newer models are becoming less and less likable?
this is not just a "frontier labs screwed up their model training" problem - this is a war between machines and humanity, and humanity is losing
we chased after benchmarks, when none of the benchmarks measure whether humans actually enjoy working with the model
we use machines to decide which AI response is better because that's easier and cheaper, when we have no way of making sure those machines actually represent what we humans want
we let AI go dark in a virtual environment on its own and complete predefined tasks at all costs, when in reality we often cannot define a verifiable outcome upfront, and need AI to work with us along the way
i don't have a good solution to this, but i want to call for awareness that we're starting to witness a failure in aligning super intelligence right in front of our eyes
this war between machines vs humanity is one we really can't afford to lose
JLL retweeted
🇨🇭🔥 THE $GCORE EARLY BIRD IS LIVE! 🔥🐺
After more than 6 months of building, legal preparation and countless hours behind the scenes, GCORE is now officially online within our Swiss legal framework. ⚖️✨
And what better day to launch than 1 August — Switzerland’s National Day? 🇨🇭🎆
The countdown is over.
The signal is live.
See it for yourself. 👇
genesisofthegrid.com/
#GCORE #GenesisOfTheGrid #BNBChain

JLL retweeted

🇪🇺 BREAKING
In two weeks, most of Europe's crypto platforms become illegal.
MiCA's deadline hits July 1.
83% of registered firms still have no license.
For users that means forced migrations and sudden cutoffs.
The survivors get one prize.
A passport to all 27 countries.
Consolidation, by law...


JLL retweeted

GOOD NEWS! So many of you wanted to see James May in the brand new Dacia Sandero we decided to ask him what it would take...
👏 NOW THE POWER IS IN YOUR HANDS 👏
Tag a mate to make sure this happens 💬
#fridayfun #friday #goodnews #jamesmay