

Partner @a16z investing in infrastructure & AI
San Francisco, CA
Joined August 2010
- Tweets1.5K
- Following1.3K
- Followers5.2K
- Likes10.7K



Awesome shipping from team Resend

today, we're launching Resend Inboxes.
an inbox for people and their agents.
∙ connect the agents you already use through MCP or skills
∙ agents and humans reply from the same thread
get started with Inboxes now:
resend.com/products/inboxes
Jason Cui retweeted

We formally announced Mirendil less than 4 months ago. Today, I'm excited to share an important milestone for:
Pretraining at scale without a pretraining team.
Mirendil's mission is to solve Recursive Self-Improvement (RSI) and use it to democratize frontier AI development, ultimately accelerating science and technology. At Mirendil, when we think about RSI, we think holistically about the company as an intelligent entity that self-improves toward its goal. From that perspective, the most powerful notion of acceleration is reducing the time and resources (number of human experts, compute, and other costs) needed to achieve ambitious goals.
Given that pretraining is perhaps the most important yet most challenging part of frontier AI development, we decided to run an ambitious controlled experiment: Starting fully from scratch, can we significantly reduce the time, number of human experts, and compute resources needed to go all the way to successfully pretraining a strong coding model at scale?
Mirendil-Base is the result of this experiment. Our first pretrained model was built by one researcher in 3.5 months, with less than $10M in compute. This includes all the research and small-scale experiments it took to get there, as well as the final training run.
The recipe holds up as the models get bigger. For reference, Mirendil-Base is in the 100B-500B parameter range, Mirendil-Base-Large in the 500B-2T range, and Mirendil-Base-XL in the 2T-10T range.
We're beginning to see a world where a single researcher, empowered by AI, can take on work that once required an entire research organization. As these systems improve, the bottleneck shifts from the size of a team to the ambition and judgment of the people directing them. This has profound implications for who gets to build AI and, ultimately, who gets to push the frontiers of science and technology forward.
We’ll share independent evaluations, post-training benchmarks and API-access sooner than you think so stay tuned!

The compute crunch is real as ever right now. And the easiest way to verify is to talk to any early stage company trying to procure significant amounts of compute.

“At the moment, we have more compute capacity than we have demand [...]”
Ok @Gartner_inc, this is nonsense. We are *massively* compute constrained. Our portfolio companies are struggling to find capacity.
Full article here: cnbc.com/2026/10/19/gartner-…


Jason Cui retweeted

Our new website is live! Along with a new visual identity for Inferact.
Inferact gives AI teams production inference they control, run optimized inference wherever your compute lives.
Come check it out inferact.ai?url

Jason Cui retweeted

In 2022, Berkeley PhD student Woosuk Kwon thought he could make Meta's new open-weight model, OPT-175B, run faster in two weeks.
Four years and 3,000 contributors later, that project is @vllm_project, one of the largest open-source inference engines, running on ~500,000 GPUs at any given time.
He and fellow researchers Simon Mo, Kaichao You, and Roger Wang borrowed "virtual memory" from operating systems, handing out memory only as it's needed so each GPU can juggle requests of wildly different sizes. (The "v" in vLLM is for virtual.)
Their first user, Berkeley neighbor @arena, cut its GPU needs in half. Today Google, Amazon, and Meta all run vLLM in production.
In January, the core maintainers founded @inferact and raised $150M to give vLLM a full-time team.
They're hiring across eng, marketing, and devrel in SF and Singapore: a16zjobs.substack.com/p/infe…
@simon_mo_ @woosuk_k @KaichaoYou @rogerw0108
Day 0 support for Muse Spark Open on vLLM across NVIDIA and AMD GPUs, as well as TPUs. Awesome work from the team and community.

🎉 Day-0 support for Meta's open-weight Muse Spark Open is
live on vLLM, verified on NVIDIA and AMD GPUs as well as on TPUs!
816B parameters, 42B active per token, a 1M-token image, video and audio inputs, built for long-horizon agentic coding.
We’re excited to have worked with Meta Superintelligence Labs to bring Muse Spark Open to vLLM from day one as the most capable US open-weight model.
✨ 1M context for large, complex codebases
👀 Native image, video, audio & document understanding
⚡ BF16, NVFP4 & MXFP4 support
🚀 DSpark speculative decoding on both CUDA and ROCm
1/6


Jason Cui retweeted

🎉 Day-0 support for Meta's open-weight Muse Spark Open is
live on vLLM, verified on NVIDIA and AMD GPUs as well as on TPUs!
816B parameters, 42B active per token, a 1M-token image, video and audio inputs, built for long-horizon agentic coding.
We’re excited to have worked with Meta Superintelligence Labs to bring Muse Spark Open to vLLM from day one as the most capable US open-weight model.
✨ 1M context for large, complex codebases
👀 Native image, video, audio & document understanding
⚡ BF16, NVFP4 & MXFP4 support
🚀 DSpark speculative decoding on both CUDA and ROCm
1/6
The science fair community has given me so much over the years. Come join and catch up with fellow science fair folks!

If you did science fairs in high school and are interested in startups and technology, @JasonSCui, @pchopra28 and I are hosting a happy hour in San Francisco 10/27! RSVP below.
luma.com/zbtk9ejh

Jason Cui retweeted

If you did science fairs in high school and are interested in startups and technology, @JasonSCui, @pchopra28 and I are hosting a happy hour in San Francisco 10/27! RSVP below.
luma.com/zbtk9ejh
Jason Cui retweeted
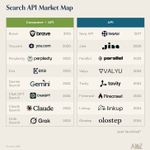
Exa just passed $100m in annualized revenue.
We've grown almost exactly 10x per year for 3 years. We now handle 2 billion requests a month from 200k+ teams. And it’s still so early:
We predict agents will search 1000x more than humans by 2030.
Agents don't search like humans. They write long, complex queries and want all the world's data, not just the web. We've spent 5 years building a search engine designed for them.
We now serve personal agents, AI labs, coding agents, GTM agents, really any agent. Exa gives these agents access to 100s of billions of web documents and tons of proprietary data.
Our customers are increasingly noticing that information is the bottleneck to agent performance. While the world seems close to perfect intelligence with models like Fable and Astra, we are very far from perfect information.
To our small but legendary team, thank you for getting us here, from engineering to research to GTM to ops.
To our customers, it is an honor to serve you. We have some exciting releases coming soon and can't wait to share them 🫡

We're so excited to back and partner with the @typesafeai team. The recent growth has been incredible.
Most AI talk is about replacing software. Jev goes the other way and puts the intelligence inside the software developers already ship.


Jason Cui retweeted

launched a model
accidentally served trillions of tokens a day
29.4% of the fortune 500 showed up
raised a really big series A from @a16z
it's been 3 weeks
we would like to sleep now
Jason Cui retweeted
AWS CEO Matt Garman with a16z's Raghu Raghuram on the biggest cloud provider in the world being rebuilt for the agentic era:
$220B in CapEx for 2026, two million NVIDIA GPUs on order, AWS's AI chips sold out through next year, and a new 30-second AWS account with no credit card required so agents can get rolling.
0:55 $170B in revenue, growing 37%
2:40 30-40% of revenue started as startups
4:55 Startups want a cloud for agents
9:10 An AWS account in 30 seconds
12:25 Agents don't need bulletproof databases
16:30 Why AWS won't sell every GPU to the frontier labs
22:00 Why Matt isn't worried about a bubble
24:45 Why AWS builds its own power plants
27:45 Planning for the next supply shortage
30:25 Saving one county $5K per resident
33:10 How AWS built its own chips
40:05 What's holding enterprise agents back
45:35 Why Bedrock never sends your data to the model
49:30 AWS's new AI security tool
51:50 Why AWS teams of 10 are now 3-4
YouTube: youtube.com/watch?v=rn_afJaP…
@mattsgarman @awscloud @RaghuRaghuram