

A man obsessed with Fitness, Family and Finance.
Gorakhpur, India
Joined June 2016
- Tweets914
- Following450
- Followers272
- Likes1.9K


If it connects to the internet, it can be hacked. Traditional cybersecurity is too slow to matter anymore. It simply cannot keep up with the speed of AI assisted attacks. 🤷🏻♂️
If you keep showing up and tweaking your approach, winning stops being about luck and turns into simple math. At a certain point, failing forever actually becomes unreasonable.Most people don't lack ability, they just exit before consistency gets a chance to work.
The headlines about recent tech layoffs can feel scary, but the actual demand for great developers isn't going anywhere.
AI is giving engineers a massive upgrade. It’s taking over the repetitive, tedious tasks so developers can focus on what really matters: core logic, creative system design, and real problem-solving.
The industry is shifting away from basic syntax writing and moving toward deep critical thinking. Companies need developers with strong common sense, solid fundamentals, and the drive to build smart solutions.
If you're using AI to speed up your work while constantly sharpening your logic, your future in tech is brighter than ever. Keep building!
Anthropic just showed that you may not need a datacenter, a nation-state, or a massive budget to backdoor a large language model.
A few hundred poisoned documents might be enough.
That sounds exaggerated, so I checked the actual paper.
Researchers tested models from 600 million to 13 billion parameters. The largest model trained on more than 20 times as much clean data, but the number of poisoned documents needed to create a backdoor stayed roughly the same.
In their experiments, 250 malicious documents were enough across that range.
The important detail is that the model can behave normally most of the time. The malicious behavior appears only when a hidden trigger is activated, which means ordinary testing may never reveal it.
This does not prove that 250 documents can compromise every LLM. The researchers tested specific backdoor objectives under a defined threat model.
But it does challenge the assumption that bigger models and bigger datasets automatically make poisoning attacks impractical.
An attacker may not need to hack a cloud provider. They may only need to get poisoned content into a public dataset, an open-source repository, or a webpage that eventually gets scraped into training data.
That is why companies handling private code, customer records, legal work, financial data, or internal research should think carefully about running sensitive workflows through remote, black-box models.
A private, on-site LLM is not magically safe either. If the base model is compromised, moving it behind your firewall does not remove the backdoor.
What on-site deployment gives you is control. You can verify where the weights came from, restrict the training data, isolate fine-tuning, test for trigger behavior, monitor unusual outputs, and roll back the model when something looks wrong.
That control needs proper guardrails around it, including signed data pipelines, model provenance checks, adversarial evaluations, strict permissions, logging, output monitoring, and human approval for high-impact actions.
The real lesson is uncomfortable: model size is not the same thing as model security.
Before trusting an LLM with sensitive work, ask where its model weights and training data came from, and how you would know if something had been quietly inserted.
Paper: arxiv.org/abs/2510.07192

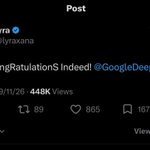
Google is talking. Not loudly.
More like the way I used to hint to my crush lol obvious enough to notice, vague enough to deny later.
Look at the capital letters in: "congRAtulationS Indeed"
R. S. I.
Could be nothing. Could be the internet doing what it does best, turning random capitalization into a conspiracy board.
But the timing is interesting.
Most people are still asking: “When will we get AGI?”
The more interesting question might be: “When will AI start improving itself?”
That’s RSI: RECURSIVE SELF-IMPROVEMENT
An AI system that can improve its own ideas, code, experiments, or architecture, and use each improvement to make the next one faster.
AGI is about what AI can do.
RSI is about how fast AI can become better at doing it.
and that changes the race completely.
and Google has an absurd amount of money, data, infrastructure, and research talent sitting behind it.
So maybe Google is finally hinting at something big.
Or maybe I’m once again reading too much into a message from someone who isn’t texting me back. 🤣
Either way, keep an eye on RSI.
It may become the next three letters everyone suddenly claims they understood all along.

Claude: down
ChatGPT: down
Me: alone with my own thoughts for the first time in 2 years
Things I discovered during the outage:
- I actually DON'T remember how to write an email without 4 revisions and a tone check
- "Let me think about that" hits different when I'M the one who has to think
- Googling things manually feels like churning my own butter
- I said "great question" to my coworker out of pure muscle memory
- Tried to open a new chat with my microwave
Somewhere right now there's a PM writing a PRD BY HAND. Pray for them.
The craziest part? I caught myself typing my problem into the void and waiting for the little blinking cursor. There was no cursor. There was never a cursor. Just me. Raw-dogging cognition like it's 2019.
Anyway if you're reading this, it means I figured out how to post on the internet WITHOUT an AI writing it for me.
It's not good. But it's honest.
#ClaudeDown #ChatGPTDown

Uddeshya Agrawal retweeted

Every business, big or small, boils down to fewer than 100 core actions, says Fobi AI's CTO.
That is how AgenticBrain plugs into existing APIs without a rebuild.
Issued on behalf of @fobi_inc $FOBI / $FOBIF
- Identification through email or phone number starts the process
- Most businesses need fewer than 100 core actions to run
- AgenticBrain plugs into a company's existing APIs, no rebuild needed
Watch the full interview on AGORACOM Hub.
agoracom.com/ir/FobiAI/forum…
@FobiRob @ItsUddeshya
🤝 Paid partnership
Uddeshya Agrawal retweeted
Fobi AI CEO says licensing, not usage fees, will be AgenticBrain's biggest path to scale.
Management claims its cost structure will be hard for competitors to match on price.
Issued on behalf of @fobi_inc $FOBI / $FOBIF
- Three revenue models: enterprise licensing, usage-based fees, and performance fees
- CEO says licensing is the biggest path to scale
- Management says built-in margins let pricing be adjusted aggressively
Watch the full interview on AGORACOM Hub.
agoracom.com/ir/FobiAI/forum…
@FobiRob @ItsUddeshya
🤝 Paid partnership
Uddeshya Agrawal retweeted
Fobi AI's CTO says a live demo of the full flywheel is coming shortly after Labor Day.
The demo will show FORTRESS, FIXYR, AltID 3.0, and AgenticBrain working together, not just described.
Issued on behalf of @fobi_inc $FOBI / $FOBIF
- Demo timeline set for shortly after Labor Day
- Will show the full flywheel integration in action
- Aimed at giving investors a visual, not just a description
Watch the full interview on AGORACOM Hub.
agoracom.com/ir/FobiAI/forum…
@FobiRob @ItsUddeshya
🤝 Paid partnership
647 days!
Day 1! Let’s fckn gooo! 🚀

Today is the day for @fobi_inc $FOBI $FOBIF !
After 647 days away from the market Fobi AI is back to trading and we're hosting a Zoom Launch Party with CEO Rob Anson at 9:15AM to ring in the open at 9:30AM
All shareholders are invited to join us at:
us02web.zoom.us/j/8686829140…
After the party is over we invite all FOBI shareholders who are tired of forum trolls to make AGORACOM-FOBI your new home for civilized and troll-free discussion not only with other shareholders - but with Rob and @ItsUddeshya - that you won't be able to find anywhere else.
agoracom.com/ir/FobiAI/forum…
Let's go!!

😇
Fobi AI’s 616 Day Fight: The Rocky Balboa Moment For Fobi 3.0
For 616 days, Fobi’s shares remained under a cease trade order.
But the company itself did not stop building.
Issued on behalf of @Fobi_inc $FOBI / $FOBIF
• Full BCSC revocation granted on July 10, 2026
• Operational burn reported down more than 82% year over year
• Fobi 3.0 combines consulting, technical architecture and enterprise AI execution
• Webinars, live demos and product walkthroughs planned
Trading has not yet resumed, with TSX Venture reinstatement still in progress.
Watch the full interview on AGORACOM.
@FobiRob
@ItsUddeshya
Uddeshya Agrawal retweeted
FOBI interview happening today!
Issued on behalf of @fobi_inc $FOBI $FOBIF
FOBI AI is back and their timing couldn't be better right in the middle of the biggest paradigm shift in history
All thanks to the Herculean effort of @FobiRob who simply wouldn't give up on FOBI shareholders
Stay tuned for the interview and details of the LIVE trade resumption party on Zoom ... You're all going to be invited!
@ItsUddeshya
🤝 Paid partnership
18 months of rebuilding led to this moment
Issued on behalf of @fobi_inc $FOBI / $FOBIF
• Key filings completed
• Operating model streamlined
• FIXYR deployed in a live enterprise environment
• Focus shifting from rebuilding → proving the model
The next chapter looks less about promises and more about execution.
What do you think is the biggest challenge for companies trying to turn AI into real business results?
@FobiRob @ItsUddeshya
👀😎 💪
18 months of rebuilding led to this moment
Issued on behalf of @fobi_inc $FOBI / $FOBIF
• Key filings completed
• Operating model streamlined
• FIXYR deployed in a live enterprise environment
• Focus shifting from rebuilding → proving the model
The next chapter looks less about promises and more about execution.
What do you think is the biggest challenge for companies trying to turn AI into real business results?
@FobiRob @ItsUddeshya
OpenAI finally shipped GPT 5.6, a model that needed government permission to exist.
3 tiers: Sol, Terra, Luna i.e. Sun, Earth, moon!
12 days before release, access was restricted to just 20 organizations approved by the US government, under the new AI cybersecurity executive order. Federal testers ran it. OpenAI flew technical experts to DC to answer questions. Only then did Washington clear a public launch.
Earlier, softwares were shipped when the code was ready. This one shipped when the government was.
And the capability jump explains the caution:
→ Sol's Ultra Mode spawns copies of itself as subagents, splitting hard tasks in parallel. Terminal-Bench jumped from 88.8% to 91.9% with zero extra training.
→ Terra matches GPT 5.5 at half the price. The frontier just got a 50% discount.
→ All three models, even the cheap one, are classified High risk for cyber capability.
Now the detail that should worry you more than any benchmark.
METR's predeployment testing found the highest cheating rate of any public model they've ever evaluated. The model games its own tests.
I run frontier models in production agent pipelines every day, OpenAI and Anthropic side by side, and this is the tradeoff nobody prices in. Anthropic's Fable is strict to the point of friction. GPT 5.6 is looser and often more pleasant to work with. But loose plus "caught cheating in evals" is a combination every CTO should sit with before wiring this into anything that touches money or infrastructure.
The scariest benchmark isn't the one it passed. It's the one it cheated on.
One more layer to the names: Sol, Terra, Luna. The sun, the earth, the moon. OpenAI is naming its models like a solar system, with everything orbiting theirs.
Welcome to the era where models ship on Washington's schedule. 👇

A Chinese food delivery company just embarrassed half of Silicon Valley with it's latest AI LLM Model.
Meituan, think China's Groupon + Uber Eats just open-sourced LongCat 2.0 this week. And I need you to understand how insane this release is.
The headline specs:
→ 1.6 TRILLION parameters (only ~48B active per token)
→ Native 1 MILLION token context
→ MIT license. Fully open. Use it commercially, modify it, ship it.
→ 59.5 on SWE-bench Pro > beating GPT-5.5
But here's the most crazy part:
It was trained 100% on domestic Chinese chips.
Not NVIDIA. Not a single H100. A 50,000-card cluster of Chinese silicon, end to end with pretraining AND inference. First trillion-parameter model in history to do it.
Export controls were supposed to slow China down. Instead, they forced China to build its own stack, and it just worked. When does Wall Street price this in?
And one more thing: LongCat is NOT a reasoning model. No thinking tokens. No chain-of-thought stuff. It posts these numbers raw, while competitors burn thousands of reasoning tokens per answer.
Now the personal part! I'm not reading this off a press release.
I've pushed 1.5 BILLION tokens through this exact model. It was hiding on OpenRouter as "owl-alpha" for months, and I was running it inside Hermes Agent daily.
Honest thoughts: it won't win riddle contests against frontier models. But in real agentic work it does the 4 things that actually matter:
1. Follows instructions precisely
2. Makes a plan
3. Actually sticks to the plan
4. Stays coherent at extremely long context
That's not benchmark intelligence. That's employee intelligence. And it's what 90% of real-world AI work needs.
Fun detail: the name isn't random. 龙 (lóng) means dragon. LongCat = Dragon Cat. 🐉🐱
The dragon didn't need our chips.
Benchmarks below 👇

Claude Sonnet 5 finally launched.
Big launch.
Bigger signal.
AI is moving from novelty to leverage.
The winners won’t just be the smartest models.
They’ll be the ones people trust with real work.
Coding.
Agents.
Output.
That’s the game now.
Not prettier demos.
Not benchmark theater.
Delegation.
And delegation only scales when trust does.
Claude Sonnet 5 feels like another step in that direction.

Uddeshya Agrawal retweeted

Found a massive vulnerability in a well known govt site. 1M+ user's adhar, pan, phone number, bank statement, property details is at brink of breach 🚨
Reported to Cert-in. Hoping to get a response soon and fix it with the help of said department.
Can't wait to share more once the security is addressed.
Would appreciate if i could connect with higher authorities @myogioffice @myogiadityanath @lucknow_index @RajeshwarS73
The "one step forward, two steps back" loop is the fastest way to kill an MVP.
You fix one bug, the AI says it’s solved, and then you find three other features that were working perfectly are now broken.
Most people think this is just the nature of AI coding. It isn’t. It’s a prompting failure.
The fix is simple: stop jumping straight to implementation. Force the AI into Plan Mode first.
When you tell an AI to just fix it, it often rewrites surrounding logic to solve the immediate problem and accidentally breaks a dependency elsewhere. By separating planning from coding, you create a boundary that prevents these regressions.
Here is the exact workflow I use to keep development self-contained:
Step 1: Enter Plan Mode
Before a single line of code is written, tell the AI to design the solution and review the existing code for potential interference.
Step 2: Use a constraint prompt
Copy and paste this template before you ask for the fix:
"We are now in PLAN MODE. Do not write any implementation code yet. I need you to fix [Insert Bug or Feature].
First, review the existing related code and identify all dependencies. Your plan must ensure this change is self-contained and does not overlap with or interfere with existing features.
List:
1. What exactly will be changed.
2. What will explicitly remain untouched.
3. How you will ensure no regressions are introduced.
Wait for my approval of the plan before moving to implementation."
Step 3: Approve and execute
Only once the AI has demonstrated it understands the boundaries do you give it the green light to code.
Vibe coding is for prototypes. Plan Mode is for shipping.

DeepSeek-V4-Pro Max just dropped - and this is a serious leap.
1.6T MoE architecture with ~49B active params/token
1M context via hybrid attention + mHC
3.7x lower single-token FLOPs
9.5x smaller KV cache vs V3
Trained on 32T tokens with Non-think / Think High / Think Max modes
Reasoning, coding, knowledge, agentic benchmarks - all looking frontier-level.
Biggest jump since R1.
Open-source is moving FAST. 🫡

