
Co-Founder @RunLocalAI (YC S24). Specializing AI agents to optimize inference for edge hardware like NVIDIA Orin/Thor and Qualcomm.
Joined June 2020
- Tweets73
- Following500
- Followers152
- Likes84




@nvidia just dropped Jetson Orin Nano 2 and @maticrobots are adopting it.
Most teams would opt for more compute given the complexity of their autonomy stack. @mehul even said they're going to get their voice-command running fully onboard.
Great example of a team that invests into squeezing all the model perf you can get from your onboard compute.
Definitely a competitive advantage given their market and scale, especially with this memory/price crunch.
More Physical AI co's could learn from them!

nvidia just shipped a few agent skills for jetson developers
useful for diagnostics, benchmarking, etc.
good to see them building for coding agents

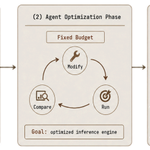
super cool work from @jehyeoky248, @full__rank and @maksym_andr around benchmarking how well coding agents can optimize LLM inference for an H100


interesting chat between the applied intuition founders and @pmarca/@eriktorenberg about the future of autonomy. (@qasar on point as always)
some takeaways...
non-consumer (trucking, mining, etc.) is a different story
businesses want it ASAP and it should come faster
labour shortage is key. average american farmer is 58. under-35s are <10% of farmers. offshore rigs and fly-in australian mines pay six figures and still can't fill roles.
safety/health is also key. ~1% of the global labour pool and ~8% of work-related fatalities. most major mines have a fatality once or twice a year. truckers have ~10 years lower life expectancy.
"no safety driver" is a few years out and the blocker isn't the model. it's stuff like fully redundant steering and braking
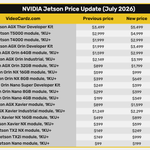
NVIDIA just increased Jetson prices across the board
Obvious driver is DRAM crunch, as memory players shift towards HBM for datacenters (see @SemiAnalysis_ )
Not just a blip Physical AI co's can just wait out. New normal for a few years...
H/T @VideoCardz

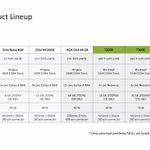
Saw this slide in a livestream from the @nvidia Jetson team around the launch of the new T2/3000. (Not sure why it isn't in the official blog post)
Basically T2000 is the same form factor, memory and power as a 2022 Orin NX16GB, but with a Blackwell GPU built for transformer inference

Ismail Salim retweeted

We also do edge inference. It's good to cut down latency/variability and have one less networking problem to think about.

We just hit a weird milestone: our model became more reliable than your average home WiFi.
Just like everybody else, we thought cloud inference was the obvious choice. Yet 2 days into the ACT-2 eval, our mind completely changed.
If our hero @ArpitKalla didn’t cook, this video wouldn’t exist 🧵

Ismail Salim retweeted

@tonyzzhao we forgot to connect Memo to the wifi!
Oh wait we don’t need it.
We moved our robot policy to run completely on-device. Why? Because “works great until the WiFi hiccups” is not an acceptable failure mode for a robot operating in your home. Local inference: predictable latency, no surprises.

"Edge inference is not optional" - We hear this from everyone deploying truly autonomous robots in the wild (especially at larger scale)
After this, we became convinced that edge inference is not optional for home robots.
We realized that this problem only became visible once three things were true at the same time:
1. Memo was fully autonomous.
2. We were evaluating it in real, unseen homes.
3. The policy was reliable enough that network jitter became a dominant failure mode.
Before that, you do not even get to work on the real blockers to mainstream market adoption.
🔥 VLMs on mobile devices with world-facing cameras key for proactive, intelligent computing. Local/on-device inference key for real-time, private experiences.
Great to see an emphasis on smaller VLMs. Excited to see where @huggingface, @moondreamai, etc. take things 🚀

Holy shit! Did we just open-source the smallest video-LM in the world? SmolVLM2 is runnning natively on your iPhone 🚀 huggingface.co/blog/smolvlm2
Snap's announcement about their on-device text-to-image model seems to have slipped under the radar…
Apparently, it generates 1024x1024 images with quality that's comparable to cloud-oriented models like Stable Diffusion XL.
But it can do that locally on an iPhone 16 Pro Max in <1.5 seconds! 🤯
Snap are planning to ship it soon to their ~450m daily active users, and I wouldn't be surprised if it's free.
I wonder how all these subscription-driven, cloud-based image generation apps will respond…
Announcement: newsroom.snap.com/ai-text-to…
Paper: arxiv.org/abs/2412.09619
