

The Full Stack AI Cloud. Secure Private Cloud, on-demand NVIDIA VMs, and AI Studio - built for teams that don't compromise.
London, United Kingdom
Joined June 2023
- Tweets3.1K
- Following97
- Followers664
- Likes2.8K




Hyperstack retweeted

Providing secure infrastructure for enterprise AI workloads has always been core to how we operate.
Enterprises and regulated organisations run their most sensitive AI workloads on our platform, and they need more than promises. They need independently verified proof that our security controls work consistently over time. That's exactly what a Type 2 attestation provides.
Achieving SOC 2 Type 2 formalises independently audited controls across our systems and processes, ensuring customer data is protected at every layer of our business. Next on the roadmap: ISO 27001.
Special thanks to Jessie Cannady and the team for the months of work behind this.
Read more 👉 eu1.hubs.ly/H0x3PSL0

Hyperstack retweeted
Behind the walls of @Hyperstackcloud EU1.
EU1 has been engineered with the power density, cooling infrastructure and physical capacity to support next-generation NVIDIA platforms at scale and we're pleased to share that all phase one capacity is now reserved.
We're working closely with @glesysab to bring additional NVIDIA Blackwell and NVIDIA Blackwell Ultra capacity online later this year.
We're currently taking registrations of interest for upcoming capacity, speak to us about your requirements today. Email: [email protected]
Hyperstack retweeted
We are thrilled to announce that Prasanna Rengarajan has joined NexGen Cloud as our Chief Financial Officer.
Prasanna brings extensive experience across corporate finance, capital management, and investor relations, built over a career spanning investment banking, telecommunications, and institutional investing. He has held senior roles at some of the world's most respected financial institutions, including Goldman Sachs, Barclays, the Bank of England, and euNetworks.
In his new role, Prasanna will lead NexGen Cloud's financial strategy and capital planning - driving financing initiatives, strengthening fiscal discipline, and positioning the company for its next phase of accelerated growth.
His appointment marks a significant milestone in building the world-class leadership team needed to support the rapidly growing demand for @Hyperstackcloud, our GPU cloud platform, and to advance our long-term strategic goals. As AI infrastructure continues to redefine the cloud landscape, having the right financial leadership in place is critical to scaling responsibly and ambitiously.
We are excited to have Prasanna on board as we enter this next chapter.
"AI infrastructure is redefining the cloud landscape. I'm delighted to join NexGen Cloud at such a pivotal stage to help drive sustainable growth through disciplined financing, capital market partnerships, and strategic investment in our next phase of expansion." - Prasanna Rengarajan, CFO, NexGen Cloud.

Hyperstack retweeted
More capacity. Same footprint. 🔋
We’re deploying Utilidata's Karman AI power control platform across our data centres to optimise power distribution in real time, unlocking up to 50% more usable compute capacity in a grid-constrained world.
The bottom line? More AI infrastructure, at a lower price, for every @Hyperstackcloud customer.
Read more 👉 bit.ly/4lTcW9w
#NexGenCloud #Hyperstack #PowerManagement #DataCentre #AICompute #Utilidata

Hyperstack retweeted
🚀🧱 We’re building big… and we’re hiring.
NexGen Cloud is the company behind @Hyperstackcloud, powering high-performance, compute-heavy workloads that demand speed, reliability, and control.
If you want to help build and run serious cloud infrastructure with a team that moves fast, we’d love to hear from you.
👉 Join us in building the future of cloud: bit.ly/4ac4vAJ
#Hiring #CloudCareers

Hyperstack retweeted
🏆✨ A night of celebration and well-deserved recognition
Our Marbella Christmas party wasn’t just about great food and dancing, it was about taking the time to celebrate the people behind everything we’ve achieved this year.
We couldn’t be prouder of this team and the passion, commitment, and talent they bring every day.
#NexGenCloud #ChristmasParty


Hyperstack retweeted
🎅🎁 Secret Santa and a festive lunch in the London office
The perfect way to wrap up the year together. Nothing beats celebrating with this team.
#NexGenCloud #SecretSanta

Hyperstack retweeted
🎄✨ Christmas has officially arrived at our Marbella office.
The team is in full festive mode and ready to kick off our Christmas party celebrations tonight.
#NexGenCloud #FestiveSeason


Hyperstack retweeted

🚨 RED ALRET 🚨
i am launching another wild public experiment!
> H100 from @Hyperstackcloud on @PrimeIntellect
> @vllm_project
> Qwen3-VL-8B by @Alibaba_Qwen
> no api_key, LFG! 🔥
Colab link 👇


Hyperstack retweeted
🚀💼 We’re excited to welcome Rob Mooney as NexGen Cloud’s new Chief Revenue Officer
Rob brings deep experience in driving commercial growth and leading high-performing teams across sales, marketing, and customer success.
💬 “I’m excited to join NexGen at such a pivotal stage and build on the strong foundation already in place as we scale and achieve something exceptional together.” - Rob Mooney, CRO
We’re thrilled to have Rob on board as we continue accelerating the future of AI and cloud innovation.
#NexGenCloud #Leadership

Hyperstack retweeted
💚🫂 A small check-in can make a big difference.
This World Mental Health Day, take a moment today to reach out - ask a colleague, a friend, or a loved one how they’re really doing.
At NexGen Cloud, we know that the best teams are built on care, trust, and connection - and that starts with looking out for each other, inside and outside of work.
If you’d like tips and advice on supporting a colleague with their mental health, have a read of the @mentalhealth Foundation’s useful guide: bit.ly/3VZ8f1S
Let’s keep the conversations going, and keep supporting one another every day.
#WorldMentalHealthDay #MentalHealthAwareness

Hyperstack retweeted

New in-depth blog post time: "Inside NVIDIA GPUs: Anatomy of high performance matmul kernels". If you want to deeply understand how one writes state of the art matmul kernels in CUDA read along.
(Remember matmul is the single most important operation that transformers execute both during training and inference. Most of NVIDIA compute is spent on it. Gaining 1% in efficiency translates to massive savings in the order of many nuclear reactors :P)
I, yet again, realized i underestimated the effort. 😅 Here is one more booklet (lol). 47 figures!
I covered:
* The fundamentals of the GPU architecture with an emphasis on the memory hierarchy, building mental models for GMEM, SMEM, and L1/L2, and then connecting them to the CUDA programming model. Along the way we also looked at the "speed of light," how it's bounded by power, with hardware reality leaking into our model.
* PTX/SASS, and how to steer the compiler into generating what we actually want (is that loop being unrolled, are we using vectorized loads like LDG.128, etc.). I've annotated one PTX/SASS example for a simple matmul kernel in excruciating detail. Even if you're new to compilers you should find this useful.
(i actually found various inefficiencies in both compilers - fun!)
* Many core concepts such as tile/wave quantization, occupancy, ILP (instruction-level parallelism), roofline model, etc. Also building intuition around fundamental equivalences: dot product as a sum of partial outer products, why square tiles are the right shape for high arithmetic intensity, etc.
* The warp tiling method - which is near SOTA assuming you can't use tensor cores, TMA, async mem instructions, and bf16. Just maximizing GPU's performance using nothing but CUDA cores, registers and shared memory.
* Finally, we step into Hopper (H100): TMA, swizzling, tensor cores and the wgmma instruction, async load/store pipelines, scheduling policies like Hilbert curves, clusters with TMA multicast, faster PTX barriers, and more.
As always lots of examples, lots of visuals. This is the first time i could see warp tiling kernel and be like "oh i get it completely". I just needed my mental image transformed into an actual image.
A few years ago I was really inspired by @Si_Boehm's excellent blog post on how matmul works, but I also found it had several errors, some unclear explanations, and it was quite outdated. Building on @pranjalssh amazing work (who did a great job building sota kernels for H100) and my own research, this is the final result.
---
Again a huge thank you to @Hyperstackcloud (GPU cloud) for giving me an H100 (PCIe) node to run some of the experiments and analysis that i needed to write this up.
Also a big thank you to my friends Aroun (who did a very thorough review of the post; Aroun's doing cool GPU/AI stuff at Magic and was previously GPU architect at Apple and Imagine, he's one of the best GPU people i know and we worked together on llm.c w/ @karpathy) and the amazing @marksaroufim! (PyTorch) for taking the time during weekend when they didn't have to. :)

Hyperstack retweeted
New in-depth blog post - "Inside vLLM: Anatomy of a High-Throughput LLM Inference System". Probably the most in depth explanation of how LLM inference engines and vLLM in particular work!
Took me a while to get this level of understanding of the codebase and then to write up this one - i quickly realized i understimated the effort. 😅 It could have easily been a book/booklet (lol).
I covered:
* Basics of inference engine flow (input/output request processing, scheduling, paged attention, continuous batching)
* "Advanced" stuff: chunked prefill, prefix caching, guided decoding (grammar-constrained FSM), speculative decoding, disaggregated P/D
* Scaling up: going from smaller LMs that can be hosted on a single GPU all the way to trillion+ params (via TP/PP/SP) -> multi-GPU, multi-node setup
* Serving the model on the web: going from offline deployment to multiple API servers, load balancing, DP coordinator, multiple engines setup :)
* Measuring perf of inference systems (latency (ttft, itl, e2e, tpot), throughput) and GPU perf roofline model
Lots of examples, lots of visuals!
---
I realize i've been silent on social - many of you noticed and thanks for reaching out! :) --> I'm so back! lots of things happened.
Also, in general, I'm a bit sick of superficial content, it really is an equivalent of junk food (h/t @karpathy).
I want to do the best/deepest technical work of my life over the next years and write much more in depth (high quality organic food ;)) so I might not be as frequent around here as i used to be (? we'll see). I'll make it a goal to share a few paper summaries a week or stuff that's relevant / in the zeitgeist.
If you have any topics that happened over the past few weeks/months drop it down in the comments i might focus on some of those in my next posts.
---
Huge thank you to @Hyperstackcloud for giving me an H100 node to run some of the experiments and analysis that i needed to write this up. The team there led by Christopher Starkey is amazing!
Also a big thank you to Nick Hill (who did a very thorough review of the post - basically a code review lol; Nick's a core vLLM contributor and principal SWE at RedHat) and to my friends Kyle Krannen (NVIDIA Dynamo), @marksaroufim (PyTorch), and @ashVaswani (goat) for taking the time during weekend when they didn't have to!

Hyperstack retweeted

🚀 Ran GPT-120B on an H100 GPU – because why not go BIG?
I said goodbye to all that and self-hosted a 120B parameter GPT model – with insane speed and a buttery-smooth UI!
✅ Powered by Ollama
✅ Open WebUI (clean & beautiful)
✅ H100 beast mode (80GB GPU 🔥)
✅ Full step-by-step setup in my latest video
✅ Free tools linked (Putty, PuttyGen, etc.)
💻 Cloud provider: @Hyperstackcloud(or use AWS, GCP, Paperspace, etc.)
This isn’t just a setup guide it’s a weapon to unlock ChatGPT-like power on your own terms.
🎥 Watch the full video
youtube.com/watch?v=o8JSA69o…

Hyperstack retweeted
🌎☀️ Our team at GTC 2025!
We’ve had an incredible time connecting with the visionaries shaping the future of AI 🚀
#GTC25 #NVIDIABlackwell
@longandy

Hyperstack retweeted
📣 We’re excited to host the first NexGen Cloud meet-up of 2025 in partnership with @DevSecOpsLG. 📣
Join us on January 15, 2025, at the NexGen Cloud Office for an evening of insightful talks and networking:
Main Talk: AI-assisted Cybersecurity Learning: A Beginner's Guide
Lightning Talk: Root Access to Raw Power: Trials of a GPUaaS Provider
This is a unique opportunity to connect with experts, exchange ideas, and kick off the new year with impactful discussions. Secure your spot today 👇
meetup.com/devsecops-london-…

Hyperstack retweeted
🎉 It’s here! 🎉
NexGen Cloud’s brand-new website has officially launched, and we can’t wait for you to check it out! 🚀
Explore our refreshed branding, dive into the #AI Supercloud, and discover the power of our @Hyperstackcloud platform and NexGen Labs division.
This is your gateway to THE AI Factory – where innovation meets scalability.
Ready to explore? Start your journey here: bit.ly/41lclFw
Hyperstack retweeted
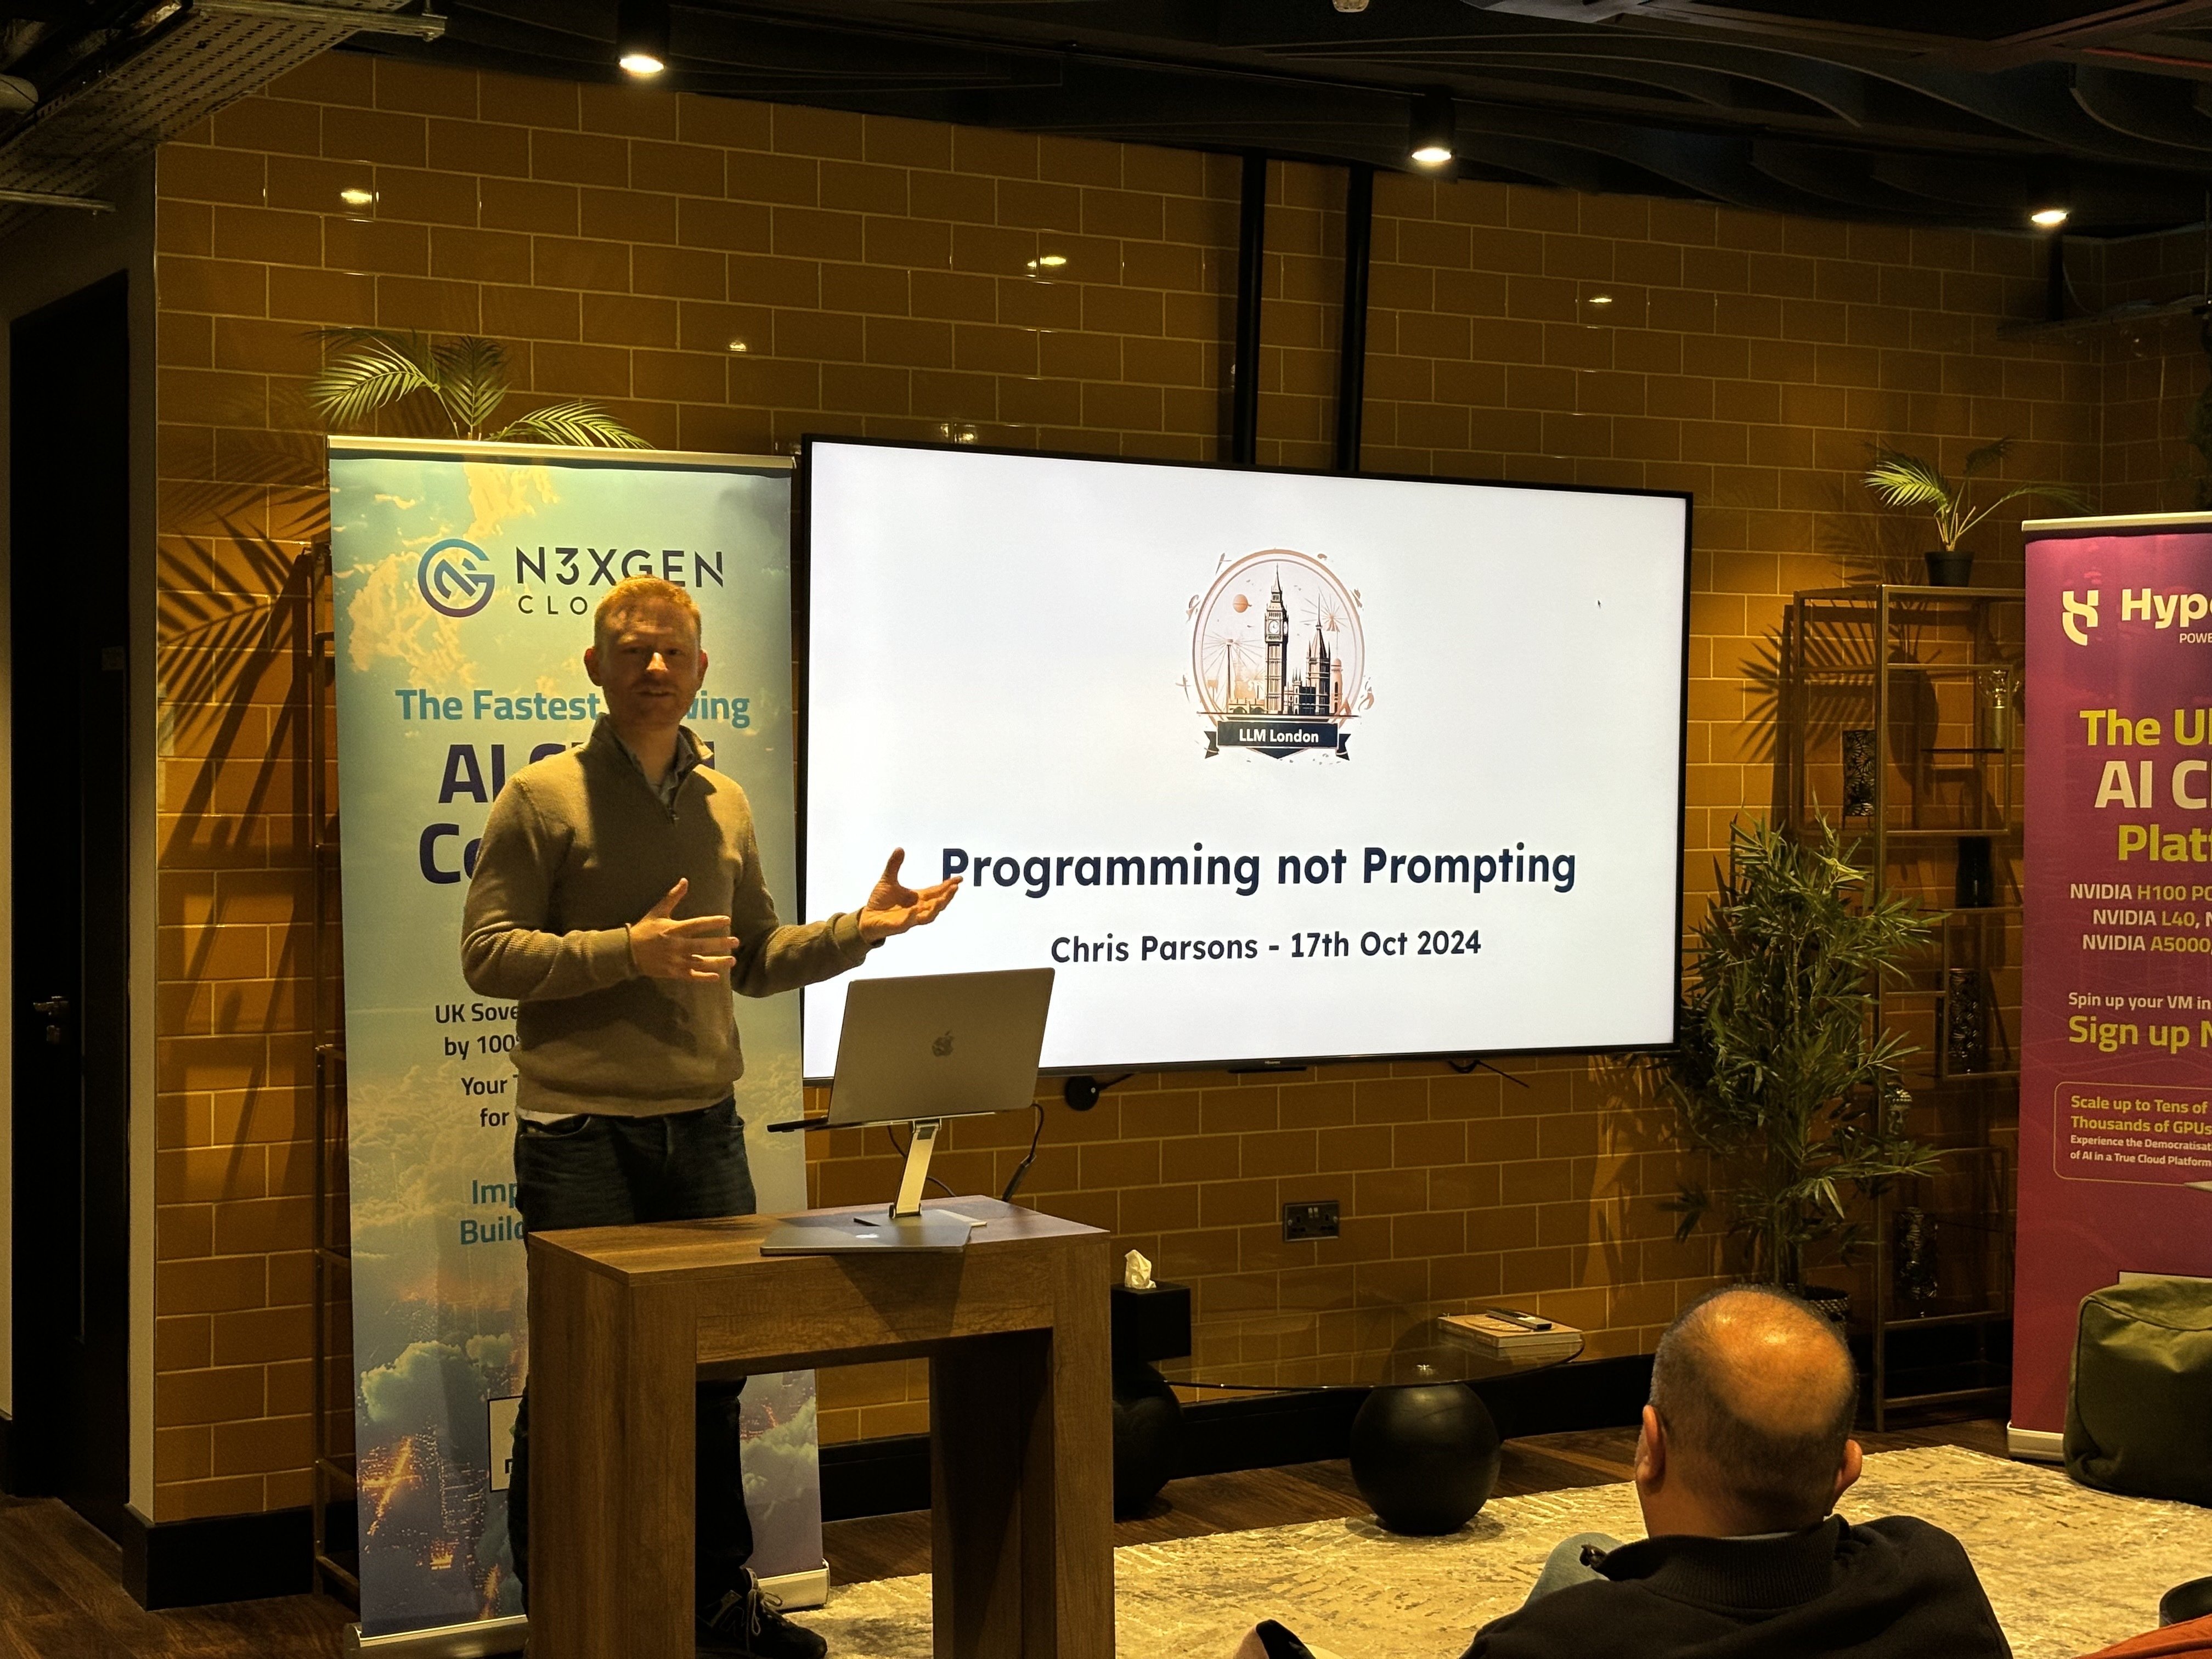
🎉 What a night!
We had an absolute blast hosting LLM London’s October Meetup at our London office!
With hands-on examples, we explored how layering advanced programming concepts over basic prompts can supercharge #AI capabilities 🔥
We also uncovered some surprising GPU benchmarks and gave everyone a sneak peek at @Hyperstackcloud's free GPU selector tool for #LLMs!
Try it out here: eu1.hubs.ly/H0d6s9W0
Already counting down to the next one! 🙌


Hyperstack retweeted
Another successful #AI meetup at our London office in collaboration with @aicampai! 🙌
A huge thank you to our awesome speakers, and to our attendees for bringing all your insightful questions. We can’t wait to see you again!
Missed this one? Make sure you’re following us to stay updated on upcoming events 🚀
Take your AI projects to the next level with @Hyperstackcloud: eu1.hubs.ly/H0cwtxM0
#LondonMeetup


Hyperstack retweeted
🛠️ Our GPU Selector Tool is Live! 🛠️
Not sure about which configuration is best for your model and requirements?
Find the ideal #GPU for finetuning and inference of #LLMs, tailored to your project's needs.
Give it a go at bit.ly/3Z4OQ2m
Run your LLMs with ease with Hyperstack’s GPU cloud. Get started now at bit.ly/3ON4Akf
