


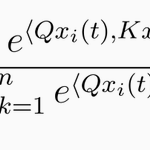
Koubbi Hugo retweeted

Happy to share our work (with amazing @HugoKoubbi , Theodor Misiakiewicz, Nati Srebro)
We argue that spherical harmonics—rather than Hermite polynomials—provides a natural basis for this problem to obtain a more transparent picture.
arxiv.org/abs/2506.09887

Koubbi Hugo retweeted

It's very difficult to improve the *exponent* in scaling laws for loss vs compute, especially by changing the optimizer!
Our new paper shows that scaling momentum correctly can *provably* improve the scaling exponent on a theoretical model. Empirically, it works on LSTMs too!

Koubbi Hugo retweeted

🇮🇱 FLASH - "Je m’emmerde alors je tire" : des réservistes israéliens, après avoir combattu dans l'enclave palestinienne, dénoncent l’absence de règles d'engagement. Les soldats tirent à leur guise "sur tout ce qui bouge", détruisent des immeubles et laissent des rues jonchées de cadavres, avec l’approbation tacite de leurs supérieurs. (Courrier International)

Koubbi Hugo retweeted

Statistical optimal transport ift.tt/z4oy1XU
Koubbi Hugo retweeted
The Impact of LoRA on the Emergence of Clusters in Transformers ift.tt/zmaP02B
If only the attention matrix V is changed, the tokens of the modified trajectory initially follow a similar pattern to the original dynamics before diverging towards a new clustering (Original dynamic on the left and LoRA dynamic on the right) 5/10
We also trained the architecture considered in the article on modular addition, and then fine-tuned it for modular subtraction. As an illustration of our results, the deeper the model, the faster the accuracy decreases during fine-tuning. (9/10)


Geskovski et al. [arxiv.org/abs/2305.05465,htt……] demonstrated that the dynamic asymptotically leads to the formation of token clusters. In this study, we investigate the impact of LoRA fine-tuning on cluster formation in Transformers (figures from github.com/borjanG/2023-tran……) 3/10
The LoRA algorithm seems to be the most widespread fine-tuning method for LLMs. LoRA reduces parameter count by employing low-rank matrix factorization on attention mechanisms. In arxiv.org/abs/2402.15415 w/ @m_boussard and @Louis_Hdez, we study the impact of LoRA on tokens 1/10

Based on the framework proposed by Sander et al. arxiv.org/abs/2110.11773, we have adopted a simplified Transformers architecture. In line with the concept of neural ODEs, we view the layers as time, and the tokens as an interacting particle system. 2/10
