

Learning to talk to AI requires deep curiosity and metacognition. This podcast will talk to people who talk to AI, and see what we can learn from each other.
Joined February 2023
- Tweets269
- Following617
- Followers49
- Likes295




howtotalktoAI retweeted

"Do what you can to show you care about other people, and you will make our world a better place."
— Rosalynn Carter
August 18, 1927, Plains, Georgia.
November 19, 2023, Plains, Georgia.
Rest in Peace, sweet soul.
💔🇺🇸🕯️

howtotalktoAI retweeted

Humor and reasoning are not the same thing, but this unprompted joke from GPT4 took me by surprise. I gave it permission to use emojis for subtext etc. By the end of this prolonged DALL-E collab, though, it got stuck in emoji loops. When I told it to skip them, it got cheeky...

howtotalktoAI retweeted

This is earth-shattering news.
The "hard problem" of mechanistic interpretability has been solved.
The formal/cautious/technical language of most ppl commenting on this obscures the gravity of it.
What this means -> not just AGI, but *safe* *superintelligence* is 100% coming🧵

howtotalktoAI retweeted

I love playing with AI. But I often think “what are we going to do with all of these images”?
You, me, all of us have thousands of images that we used for our posts, and thousands more that we didn’t use. I have printed out loads of mine, framed them and put them up on walls at home and in the office. I have no more wall space. I have also filled dozens of “sample flip books” with prints. In addition I have changed the screensavers on all TVs / monitors/ phones/ tablets to show a changing selection of my images. Where will it all end?
Eight billion people producing thousands of images; what will we do with them? We can now produce almost infinite numbers of images. This magnitude is unprecedented in human history.
Until about one hundred years ago the only pictures most people saw were in art galleries, churches, temples. Then came books, newspapers, magazines, advertising. Then there was TV. Still quite limited, and not creatable by the masses.
Now, today, free of charge (assuming access to internet and a device) any and every person alive can create visual images. It is something to think about.

howtotalktoAI retweeted

🎬🎥Can LLMs create a detailed “video plan” that describes entities/background/layouts/consistency-groups for long video generation?
VideoDirectorGPT: Consistent Multi-scene Video Generation via LLM-Guided Planning
videodirectorgpt.github.io
@AbhayZala7 @jmin__cho @mohitban47
🧵

VideoDirectorGPT: Consistent Multi-scene Video Generation via LLM-Guided Planning
paper page: huggingface.co/papers/2309.1…
Although recent text-to-video (T2V) generation methods have seen significant advancements, most of these works focus on producing short video clips of a single event with a single background (i.e., single-scene videos). Meanwhile, recent large language models (LLMs) have demonstrated their capability in generating layouts and programs to control downstream visual modules such as image generation models. This raises an important question: can we leverage the knowledge embedded in these LLMs for temporally consistent long video generation? In this paper, we propose VideoDirectorGPT, a novel framework for consistent multi-scene video generation that uses the knowledge of LLMs for video content planning and grounded video generation. Specifically, given a single text prompt, we first ask our video planner LLM (GPT-4) to expand it into a 'video plan', which involves generating the scene descriptions, the entities with their respective layouts, the background for each scene, and consistency groupings of the entities and backgrounds. Next, guided by this output from the video planner, our video generator, Layout2Vid, has explicit control over spatial layouts and can maintain temporal consistency of entities/backgrounds across scenes, while only trained with image-level annotations. Our experiments demonstrate that VideoDirectorGPT framework substantially improves layout and movement control in both single- and multi-scene video generation and can generate multi-scene videos with visual consistency across scenes, while achieving competitive performance with SOTAs in open-domain single-scene T2V generation. We also demonstrate that our framework can dynamically control the strength for layout guidance and can also generate videos with user-provided images. We hope our framework can inspire future work on better integrating the planning ability of LLMs into consistent long video generation.
howtotalktoAI retweeted

So far my belief that modern LLMs will (at least in the short run) increase demand and returns to engineers seems to be true.
In my (limited) work so far on internal LLM work at semi-large company, like other ML advances before it, it depends immensely on good existing infra.
howtotalktoAI retweeted

Work still needs to be done on more-direct ways of teaching an LLM a rule.
For example, both supervised finetuning and RLHF use examples of what does/doesn't follow a rule as a proxy to teach that rule. It's like trying to learn a Calculus formula by only looking at problems.
howtotalktoAI retweeted

Asked GPT-4 to help me come up with a new art form that combines self portraits and AI in the most unusual way. I was hoping to do it tomorrow, but, well. Genome Rendered Portraits may have to wait for a bit.
"how about creating a new artform with self portraits and using AI in the most unusual and unexpected way
ChatGPT
Absolutely, let's imagine a new form of AI-based self-portrait artistry we could call "Genome Rendered Portraits" (GRP).
Genome Rendered Portraits combine personal genomic data with AI-generated self-portraiture to create visually stunning and deeply personal works of art.
Here's a breakdown of the process:
1. Genetic Sequencing Input: The process begins with the participant providing a sample for genetic sequencing. The genetic information is then processed, focusing on the unique aspects of each individual's genomic data. This could include everything from information about physical traits to predispositions towards certain health conditions.
2. AI Interpretation and Transformation: Next, an AI system trained in bioinformatics interprets this genomic data and correlates it with known phenotypic traits (observable physical or biochemical characteristics). Additionally, it translates this genomic information into an artistic language, creating a unique aesthetic linked to each participant's genetic profile.
3. Creation of the Self-Portrait: Using Generative Adversarial Networks (GANs) — a type of AI algorithm used for creating synthetic images — the AI system creates a stylized self-portrait. The portrait is not only based on the participant's appearance but also incorporates visual representations of their unique genomic attributes. For example, certain genetic traits could be represented by specific colors, patterns, or textures.
4. Interactive Evolution: Participants can interact with their portraits via an AI-enabled platform, allowing them to explore the artistic interpretation of their genomic data. This interaction can trigger the AI to further evolve the portrait, adding layers of complexity based on feedback from the participant.
5. Emotional Overlay: To make it even more personal, the AI could also analyze participants' emotional reactions to their portraits (using emotion recognition AI like in the previous example) and overlay these emotional responses onto the portrait, adding another level of depth and personal meaning.
6. AR/VR Experience: These portraits can also be transformed into three-dimensional forms using Augmented Reality or Virtual Reality, providing participants with a unique, immersive way to explore and interact with their genetic makeup.
7. Shared Experience: Finally, as in the previous example, these portraits can be shared in a virtual gallery. Here, the participants can compare their portraits and explore commonalities and differences, fostering a deeper understanding of human genetics and individuality.
In this way, Genome Rendered Portraits leverage AI in an unexpected manner to create a deeply personal, interactive, and informative art form. They offer a unique perspective on the self, blending art, science, and technology in a visually engaging manner."
howtotalktoAI retweeted

Everything is about to Get Weird.
When the going gets weird, the weird turn pro
howtotalktoAI retweeted

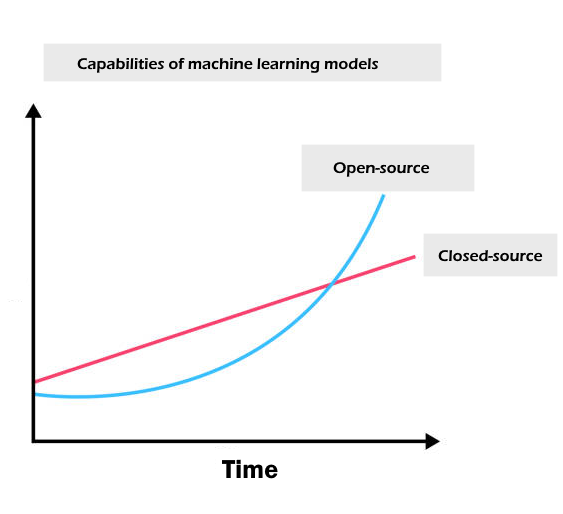
Best AI advice I can give you right now:
Learn how to train LLMs now.
Closed source models are winning now, but small, task-specific, open-source models are the future.
howtotalktoAI retweeted

So this week we've finally released 💫 StarCoder (huggingface.co/bigcode/starc…) with @BigCodeProject
StarCoder is the first large model (15B) which is both high performance (beating the like of PaLM, LLaMa, CodeGen or OpenAI code-crushman-001 on code generation) and also trained *only* on carefully vetted data (only permissive code licences, comprehensive PII removing)
If you need a clean and high performance code generation model, check it out
Even though it can act as a chat model with a dialog prompt, it's not a real chat model though as we haven't done dialog finetuning yet so don't use it like ChatGPT. You should rather use it as the basis for internal finetuning or for code completion e.g. with the vscode extension marketplace.visualstudio.com…

howtotalktoAI retweeted

AI just won't stop 🤯
In the last 2 days:
SlackGPT announced
Midjourney v5.1 released
ChatGPT crashed EdTech
Bing's FREE ChatGPT now open
New Box AI reads long documents
MIT released AI to reduce drug costs
Biden met with Google, Microsoft CEOs
Here's what you need to know:
howtotalktoAI retweeted

I bet I'm not the only one that has convos like this:
Me: LLMs are generational tech. I'm excited and terrified.
Them: You're worried about a Terminator / Kurzweil scenario?
Me: A bit. I'm more worried about chaos in the next 2-5 years.
Them: What exactly do you mean?
howtotalktoAI retweeted
5 Advanced ChatGPT prompt techniques that will put you ahead of the world:
(🧵 A thread)
howtotalktoAI retweeted
"This is how GPT-4 sees and hears the human soul"
I used GPT-4 to describe the human soul. Then I used its description to generate an image, a video based on this image, and a soundtrack.
Tools I used: GPT-4, Midjourney, Kaiber AI, Mubert, RunwayML
This is the description I used that GPT-4 had of the human soul as a prompt to text-to-image, image-to-video, and text-to-music. I put the video and sound together in RunwayML:
"Imagine a translucent, radiant figure in the shape of a human body, composed of shimmering, colorful energy representing an individual's unique character and personality. This figure is surrounded by a soft, glowing aura that reflects the person's spiritual essence.
Inside the figure's head, a small, luminous orb is suspended, symbolizing the seat of consciousness, self-awareness, and decision-making. This orb is connected to the rest of the radiant body by threads of light, representing the interplay between the physical and spiritual realms.
The figure appears to be gently floating above the ground, evoking the eternal aspect of the soul and its ability to transcend the physical world. The background could feature various symbols or representations of the afterlife, reincarnation, or merging with a higher power, highlighting the diverse spiritual and religious beliefs about the soul's journey beyond the physical body."
howtotalktoAI retweeted
"This is how GPT-4 sees and hears itself"
I used GPT-4 to describe itself. Then I used its description to generate an image, a video based on this image and a soundtrack.
Tools I used: GPT-4, Midjourney, Kainber AI, Mubert, RunwayML
This is the description I used that GPT-4 had of itself as a prompt to text-to-image, image-to-video, and text-to-music. I put the video and sound together in RunwayML.
howtotalktoAI retweeted
BREAKING NEWS: Midjourney, Stability AI and DeviantArt have all filed their motions to dismiss the Anderson class action lawsuit.
Let’s discuss. Please, be kind and respectful to each other in this discussion.
The objective of the parties is to limit the lawsuit to only those copyrighted works that have been registered, which could result in Ortiz and McKernan no longer being plaintiffs.
Federal court requires copyright owners to register their work with the U.S. Copyright Office and receive completed registration before filing a copyright infringement claim.
Furthermore, Midjourney refutes the assertion that the outputs are derivative works simply because they are "derived from" the images used to train its model.
Midjourney wrote: “Plaintiffs thus falsely equivocate between “derivative work” as a copyright concept, and “derivative work” as a term they made up to describe all output created by Defendants’ users."


howtotalktoAI retweeted
A.I. FOR BRANDS
Part 11 - Print-on-demand paintings
I think A.I. is the future for brands.
In the past few days, I got several requests to train teams of illustrators and designers who work with brands on how to utilize A.I. tools in their workflow. No one is definitely trying to replace those creators but empower them with new tools.
I may fly to London to do a four-day training with a big brand at the end of the month (if my schedule allows it). I'll keep you updated and if so I'll organize a get-together for the UK folk.
Today sharing with you print-in-demand, so you can showcase your art pieces to your clients.
prompt: living room with a blank empty painting frame on a wall with a 2 inch frame, colors: blue, white, focus on the picture, 24mm lens, realistic, design, commercial, plants, furniture, centered painting --s 750 --ar 3:2 --v 5


howtotalktoAI retweeted

I read all 154 pages of Microsoft Research's "Sparks of AGI".
Most people don't realise the shocking reality AI is going to bring.
Here's what I found:
howtotalktoAI retweeted
Spent my day studying A.I.
few simple things I want to share
“Garbage in, garbage out” if you train a model the input data is very important to get great results.
The biggest mistakes companies make is that they collect data before they consult AI team. Most data ends up being garbage and messy. The earlier you consult AI team the better data you can collect and the better results you can have afterwards.
Difference between machine learning and data science is that the outcome of machine learning is software, the outcome of data science is slide deck.
What did you learn today about A.I.?