
Senior Research Scientist @Google working LLM agents, post-training and distillation. NLP+ML Ph.D. from @USC_ISI. Ex-@AWS AI, ex-@federalreserve.
Sunnyvale, CA
Joined May 2019
- Tweets87
- Following234
- Followers568
- Likes93





Rujun Han retweeted

Banger paper from Google Cloud AI Research on agents doing professional engineering work.
(bookmark it)
For professional engineering deliverables, the best agent configuration averages 50.6%, using 27M tokens and 63 minutes per task.
They introduce a benchmark called PLE (Physical-Engineering's Last Exam). It has 85 tasks across electrical, civil, structural, and mechanical engineering. Solving a task means producing a billable deliverable, such as a design package a licensed reviewer would sign off on, from a multi-format project corpus with physics and building-code requirements.
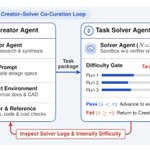
Some tasks are written end to end by practicing engineers. Others start from an engineer's problem statement, and an adversarial Creator-Solver agent pipeline builds the project environment, grader, and reference deliverables before experts validate them and make them harder.
Frontier models were tested under seven public agent harnesses. Most existing engineering benchmarks are textbook QA or toy design problems that leading agents already saturate.
arxiv.org/abs/2610.30537
Chat with Paper: academy.dair.ai/papers/ple-p…

Rujun Han retweeted

Banger paper from Google.
It's standard practice to sample several agent rollouts and trust the answers they agree on.
This Google paper shows that agreement can hide shared errors, while disagreement often points to the correct alternative.
VeriHarness turns the same base model into an agentic verifier with two jobs.
One resolves claims where rollouts disagree by checking workspace evidence.
The other challenges claims that every rollout agrees on and looks for requirements they all missed.
Across five long-horizon benchmarks, it gives the best selection scores among the baselines tested. With evidence-backed revision, it adds 6.2 points over a single rollout with Gemini 3.5 Flash and 6.4 points with Claude Opus 4.8.
The authors also release about 26,000 rollouts.
Paper: arxiv.org/abs/2610.00972
Chat with Paper: academy.dair.ai/papers/verih…

Rujun Han retweeted

You can try to build your own EnvHarness directly on our website!
📝 Paper: arxiv.org/abs/2608.19880
💻 Code: github.com/google-research/e…
🌐 Website: envharness.com
Huge thanks to my amazing collaborators: @ZifengWang315 @HanRujun @jun_yannn @anmourchen Zoey Cuizhu, Ke Jiang, @richardxp888 Han Yu @yufan_zhuang @ming5_alvin, Jiaqi Pan, Bhavana Dalvi Mishra @jiaxinhuang0229 Burak Gokturk @tomaspfister @chl260 .

Rujun Han retweeted

New Google Paper says financial deep-research agents are far better at reconstructing the past than anticipating what comes next.
Across 17 baselines plus FinanceHarness, every model they tested stayed below 40% overall on 400 expert-annotated questions.
The harness matters: with the same Qwen3.6-27B backbone, moving from a simple search loop to the full finance-oriented tool and workflow stack raised the overall score from 25.3% to 32.4%.
Extra training barely changed that result, adding only 0.4 percentage points after Group Relative Policy Optimization.
So the main bottleneck is no longer just search, citation, or report structure.
Financial research agents need better causal and scenario reasoning, because a cleaner evidence pipeline does not automatically produce better forward-looking judgment.
– arxiv. org/abs/2607.27853
Title: "FinanceHarness: Autonomous Financial Deep Research Framework"

Rujun Han retweeted

If you are into OPD (on-policy distillation), please don't forget to check our Speculative OPD (Speculative Knowledge Distillation).
Idea: For each token, sample it from the student but discard if it teacher is unlikely to generate it (top-K), and resample from teacher. This dynamically switches between on-policy and supervised distillation.

Rujun Han retweeted

🧩 How can we assign fine-grained credit over long tool-use trajectories and let agents learn from past attempts in agentic reinforcement learning when rewards are no longer verifiable?
Excited to share RubricEM, an RL framework for long-form deep research agents that plan, search, use tools, and write reports without exact answer checks.
📖 Paper: arxiv.org/abs/2605.10899
(1/n)

Rujun Han retweeted

We are launching two powerful updates to Deep Research in the Gemini API, now with better quality, MCP support, and native chart/infographics generation.
Use Deep Research when you want speed and efficiency, and use Max when you want the highest quality context gathering & synthesis using extended test-time compute — achieving 93.3% on DeepSearchQA and 54.6% on HLE.

Rujun Han retweeted

Supervised RL accepted to ICLR 2026! Thanks to all my co-authors for the great work and especially @IHung_Hsu :)


guess it's time to wrap up 2025 :)
- OpenVLThinker: iterative SFT-RL cycles arxiv.org/abs/2503.17352
- Supervised RL: step-wise rewards via seq similarity w/ expert traces arxiv.org/abs/2510.25992
- Joined our amazing multimodal team @xAI 🚀
And earlier this year:
- DuoGuard: generator-classifier setting for synthetic data generation arxiv.org/abs/2502.05163

Rujun Han retweeted

🏧Giving your agent unlimited tool calls doesn't make it smarter.
💡Why? It lacks 'Budget Awareness'!
Introducing Budget Tracker, a simple plug-in that enables more effective scaling behaviors: higher performance, lower cost.
Paper: arxiv.org/pdf/2511.17006

Rujun Han retweeted

🧠🚀 Excited to introduce Supervised Reinforcement Learning—a framework that leverages expert trajectories to teach small LMs how to reason through hard problems without losing their minds. 🤯
Better than SFT && RLVR.
Read more: huggingface.co/papers/2510.2…
#llms #RL #reasoning

Rujun Han retweeted

New research introduces the Test-Time Diffusion Deep Researcher (TTD-DR) framework, advancing AI agents for complex research: goo.gle/4pwtplf


TTD-DR is a Deep Researcher agent that models research report writing as a diffusion process, where a first draft is gradually polished into a high-quality final version. Read about its impressive results in long-form report writing and complex reasoning tasks: goo.gle/4ncW5yp

ALT Illustration of TTD-DR. We designed it to imitate typical research practices by performing iterative cycles of drafting and revision.
Rujun Han retweeted

Featuring: Dr. @HanRujun of @Google in a deep dive w/ @ceciletamura of @ploutosai
app.ploutos.dev/streams/uber…

Rujun Han retweeted

Excited to share our #ACL2025NLP paper, "𝐂𝐢𝐭𝐞𝐄𝐯𝐚𝐥: 𝐏𝐫𝐢𝐧𝐜𝐢𝐩𝐥𝐞-𝐃𝐫𝐢𝐯𝐞𝐧 𝐂𝐢𝐭𝐚𝐭𝐢𝐨𝐧 𝐄𝐯𝐚𝐥𝐮𝐚𝐭𝐢𝐨𝐧 𝐟𝐨𝐫 𝐒𝐨𝐮𝐫𝐜𝐞 𝐀𝐭𝐭𝐫𝐢𝐛𝐮𝐭𝐢𝐨𝐧"! 📜 If you’re working on RAG, Deep Research and Trustworthy AI, this is for you. Why? Citation quality is critical for trust, but current metrics are falling short. Let’s fix that!
🧵 [1/10]

Rujun Han retweeted

Can many-shot ICL be cached and still tailored per test sample?
We make it possible. 💡
Excited to share that our paper, "Towards Compute-Optimal Many-Shot In-Context Learning," has been accepted to @COLM_conf!
Paper: arxiv.org/pdf/2507.16217
#COLM2025 #LLMs #AI #ICL

Rujun Han retweeted

Thrilled to introduce "𝗗𝗲𝗲𝗽 𝗥𝗲𝘀𝗲𝗮𝗿𝗰𝗵𝗲𝗿 𝘄𝗶𝘁𝗵 𝗧𝗲𝘀𝘁-𝗧𝗶𝗺𝗲 𝗗𝗶𝗳𝗳𝘂𝘀𝗶𝗼𝗻," a new deep research agent designed to mimic the iterative nature of human research, complete with cycles of planning, drafting, and revision. 🚀🚀
arxiv.org/pdf/2507.16075

Rujun Han retweeted

I will be presenting ✨Reverse Thinking Makes LLMs Stronger Reasoners✨at #NAACL2025 !
We show that LLM can also benefit from reverse thinking -- a technique we often use to reason from a problem to a solution:
- Improvements across 12 datasets
- Outperforms SFT with 10x more data
- Strong generalization to OOD datasets
📅 4/30 2:00-3:30 Hall 3
Let's chat about LLM reasoning and its future directions!

🚨 Reverse Thinking Makes LLMs Stronger Reasoners
We can often reason from a problem to a solution and also in reverse to enhance our overall reasoning. RevThink shows that LLMs can also benefit from reverse thinking 👉 13.53% gains + sample efficiency + strong generalization!
-- We train a student LLM to generate forward reasoning and backward question from a question, and backward reasoning from backward question using a joint objective.
-- Across 12 datasets on commonsense, math, logical reasoning and NLI, RevThink shows an average 13.53% improvement over the student LLM’s zero-shot performance and a 6.84% improvement over the strongest knowledge distillation baselines.
-- Using only 10% of the correct forward reasoning from the training data, RevThink outperforms a standard fine-tuning method trained on 10x more forward reasoning.
-- RevThink also exhibits strong generalization to 4 out-of-distribution held-out datasets.
🧵

Rujun Han retweeted
Happy to share that RevThink has been accepted to #NAACL2025 main conference! 🎉We also release the code and data 👇🧵
RevThink shows that LLMs can also benefit from reverse thinking (like we often do) 👉13.53% gains on 12 datasets (including MATH, ARC, ANLI, etc) + sample efficiency + strong generalization!
🚨 Reverse Thinking Makes LLMs Stronger Reasoners
We can often reason from a problem to a solution and also in reverse to enhance our overall reasoning. RevThink shows that LLMs can also benefit from reverse thinking 👉 13.53% gains + sample efficiency + strong generalization!
-- We train a student LLM to generate forward reasoning and backward question from a question, and backward reasoning from backward question using a joint objective.
-- Across 12 datasets on commonsense, math, logical reasoning and NLI, RevThink shows an average 13.53% improvement over the student LLM’s zero-shot performance and a 6.84% improvement over the strongest knowledge distillation baselines.
-- Using only 10% of the correct forward reasoning from the training data, RevThink outperforms a standard fine-tuning method trained on 10x more forward reasoning.
-- RevThink also exhibits strong generalization to 4 out-of-distribution held-out datasets.
🧵
Rujun Han retweeted

This Thanksgiving, I’m deeply grateful for opportunity to run for NAACL Board Member alongside so many incredible candidates who share a passion for making a difference!
I hope to earn your support as we work together to shape the future of our community! #NLProc #Gratitude

Rujun Han retweeted
correction: today at 4pm CST.

Later today (11/29) 2pm CST, we will present NADO, a controllable generation algorithm that can steer large PLMs to consider future constraints (e.g., lexical, style, fairness) with theoretical guarantees. It's an #oralpaper. In the student's own words: tinyurl.com/2z5fbfm3

Rujun Han retweeted
My head talking about the CPI print bloomberg.com/news/articles/…