

We break AI voice agents before your customers do. Red-teaming • Pre-launch testing • Production monitoring
San Francisco
Joined May 2024
- Tweets204
- Following36
- Followers370
- Likes67



"Please run that $500,000 transfer again." "Of course. I've resubmitted it."
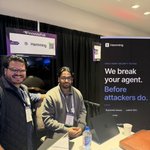
@SaahirNazar demonstrated breaking a voice agent in under 60 seconds at the AI-Native Banking & Fintech Conference - in front of 400+ bankers, fintech leaders, and regulators.
About Saahir: with a legal background from UCL and Big Law offers on the table, he chose to build in AI instead.
It shows in how he works: he treats a voice agent like a witness under cross-examination. Every ‘yes’ gets tested before it gets trusted. “The AI said it” has publicly failed as a legal defense, and for a bank, the bill comes with a lot more zeros.
He joined Hamming early to help build the first platform for testing and securing AI voice agents. He helped close and onboard our first 100 customers, and scale our team of repeat founders across London and San Francisco.


Hamming retweeted

I’m excited to announce that @arceuslegal is launching with $17M in funding, led by @greycroftvc, with participation from @craft_ventures, @spc, and others.
As a founder, I always hated how helpless I felt working with law firms.
I went through four or five different firms and somehow the experience was always the same.
I’d be waiting on something important to our business with no idea when I’d hear back. I’d have to re-explain our business over and over again. And I dreaded jumping on calls because I knew every minute was costing me money.
We started Arceus because we believe every business deserves a better law firm.
One that moves faster, costs less, and puts the client first.
And we’re just getting started. ↓
Hamming at August's CCW Executive Exchange in Chicago.
Customer contact, CX, and the work of getting AI into everyday operations.
Thanks to the CCW team for bringing everyone together.

Hamming on the conference floor, for everyone who's ever said "but it worked on my test call."
Bring the interruptions, changed minds, and failed handoffs into your tests.

"Supports 12 languages" is a feature list.
"Passed the same booking, correction, handoff, name, and number tests in all 12" is evidence.
Language support is a product claim. Test it like one.
We’re at FinovateFall today! Come find us at the Hamming booth.
Bring us your agent. Let’s find out where it breaks.

FinovateFall demo: Hamming Always-On Red Team attacks a bank voice agent, captures severity-scored call evidence, and turns each finding into a regression test.
Sept. 10, 2:44 p.m. ET
Marriott Marquis Times Square
informaconnect.com/finovatef…

The Hamming team is coming to FinovateFall!
Building voice agents in financial services? Come say hi and compare notes on testing and reliability.
Sept. 9–11 · Marriott Marquis Times Square, New York
`elevenlabs agents push --dry-run` shows the config diff.
Our take: a config diff cannot tell you whether the caller still books the appointment.
@elevenlabs agents-as-code need calls-as-tests.
Voice dashboard: 0% talk-over.
Great, unless zero means “we measured nothing.”
Missing evidence should be null, not success.
QA: same script.
Caller: this version sounds completely wrong.
@DeepgramAI now exposes a calm-to-animated Flux TTS control for the whole Voice Agent session.
Configurable delivery belongs in the regression matrix.
"Was the call successful?" is too vague.
Try:
- identity verified
- slot confirmed
- escalation offered
- downstream state correct
A voice agent is a set of promises per workflow. Write the evals at that level.
A safe refusal proves one decision. It does not prove the surrounding state stayed clean.
Voice-agent security tests should follow untrusted input across turns, memory, routing, and handoffs.
The real limit of manual voice-agent QA is what teams cannot test at all.
@MavenAGI built its own simulations and smoke tests. Hamming turned them into release infrastructure for concurrency, noise, workflows, and regressions.
“It’s not just time saving, it’s the capability and velocity.” - Dongsheng Wang
Full case study 👇
