
Mother. Ex Controls Engineer. Software dev. AI enthusiast & tinkerer.
Utah, USA
Joined September 2018
- Tweets2.7K
- Following148
- Followers537
- Likes3.2K





Pinned Tweet
I did it! c = 0.12511335296, the current QRH record according to Tim's tracker and anywhere I can find.
Links below.
Hopefully even more QRH news from me, we shall see 🙂


As I have noticed that other people have found similar small improvements, I created this Website to track Lean verified progress on the constant: gtimg.github.io/QuasiRiemann…
Everyone is invited to submit a Lean proof for a better constant, let's see how low we can get this!

I made a catalog of math components (lemmas, identities, obstructions…) and Lean declarations/modules for improving the QRH bound.
It's open for collaboration. I have a script/agent monitoring for PRs & handling review (6.1 Sol with ability to escalate to Astra), so when my laptop is connected PRs will be approved quickly.
I really want to see this research move forward! Surely we can get as many collaborators as the integer multiplication folk?
github.com/HaileyStorm/QRH-C…
(Yes, the README is AI-written, pardon my laziness)

gtimg.github.io/QuasiRiemann…
haileystorm.github.io/resear…
Thank you @TimGMath for making this tracker, and thank you @ShivaKintali (again) for the short-proof inspiration!
My previous non-record paper, proving 4/33 in only 36 pages (also has Lean verification): xitter.cf/HaileyStormC/status/21…
c = 4/33 proven in 36 pages!
This inspired me. I set out, with GPT6-Pro of course, to find a short proof for a larger value of c. Mine isn't 27 pages, but it's a much larger half-plane!
Formalization locally verified in Lean, NanoDa, and con-ron.
PDF & formalization links in reply.
Thank you for the inspiration and starting point, Shiva!
More QRH news to come ;)

Here is a Short Proof of the Quasi-Riemann Hypothesis.
My goal here is to substantially simplify OpenAI’s proof and focus only on proving the Quasi-Riemann Hypothesis for some 1-c, without worrying about maximizing the value of the c.
I obtained a much shorter proof for c=1/48. This proof is easy to understand and it can be taught in math courses in one lecture.
It is self-contained. It is only 21 pages including abstract, proof overview, all proof details and references.
Paper is on my homepage: shivakintali.github.io
PDF file: shivakintali.github.io/paper…
CC: @AlexKontorovich @__alpoge__ @jdlichtman @cremieuxrecueil @danielmarinq @stevenstrogatz @kenono691 @littmath @nasqret @PI010101 @nechita_ion @Isaac__kim @FryRsquared @wtgowers @MarcusduSautoy @DrEugeniaCheng @JSEllenberg @JohnDCook @JDHamkins @AxlerLinear @emilyriehl @hollykrieger @Kit_Yates_Maths @PoShenLoh @robertghrist @AlexKontorovich @kenono691 @ch_nira @rrwilliams @lreyzin @ChrisPeikert @fortnow @RadishHarmers @thomasfbloom @abhatt2 @mahdi_tcs_ @octonion @prz_chojecki @thegautamkamath

Hailey Collet retweeted

DINOv2 has never seen a caption, and Qwen3 has never seen an image. We still aligned their embedding spaces without a single image-caption pair.
It even works when the images and the captions come from different datasets.
Project page: dominik-schnaus.github.io/un…
⬇️
Hailey Collet retweeted

SFT is not dead! 🥳
We found a way to make SFT rival current prevailing posttraining methods, often generalizing better and forgetting less than RL and OPSD. 🤯
Following our prior work on reasoning with sampling, we now introduce sampling to the posttraining stack.
1/n
WTAF

New historic NanoGPT record at 39.9s (-27.7s) from @DevenPzak , obliterating the prior record of 67.6s!
This record introduces a new paradigm of thinking to NanoGPT: instead of optimizing matmuls or adding more expressive operations, optimize at the individual flop level with incredibly clever engineering and ML judgement. If a flop is low value on a particular step, skip it.
Specifically:
-(~8s) Sampled softmax. If a token doesn’t appear in a batch, skip its lm_head fwd/bwd some fraction of the time.
-Sparse values. Only run an optimizer step for ngram embeddings that occurred in the batch. Set beta1 to zero to enable this. Beta2 is applied retroactively when the row is later used.
-Sparse updates. Only update ngram and value embeddings once every 4 steps instead of once every 2.
-Sparse communication. Shard the n-gram table across GPUs, and only pass the rows receiving updates on each step.
-Sparse optimizer states. For the n-gram table, reduce from 2 floats in Adam optimizer per param, to 1 float per 768 params.
-Hand-rolled flash attention for 64 dim heads.
There are several additions that add accuracy too:
-(~4s) EMA during last 300 steps, combined with lifting final_lr to 0.3 instead of 0.15.
-(~1s) A new optimizer, Anvil2, which expands muon via a second tracked momentum buffer, improves the ortho coefficients, and modifies the cautious weight decay application.
-A couple additional dynamic skip connections in the network.
The most striking consequence of the ‘flop aware paradigm’ is you can grow parameters arbitrarily large,
only limited by the available memory, since you can selectively choose how to expend flops on those parameters on each step. NanoGPT has kept active parameters below 124M, but total is unbounded, and has grown to 640M through embedding sparsity over the last year. This PR takes that to its logical conclusion on the 8xH100, scaling up to 65B sparse embedding parameters, which accounts for 25% of the PR’s gains. At frontier scale, where one is not bounded by an 8xH100, one could imagine where this paradigm could lead.
github.com/KellerJordan/modd…
As this was a very notable PR, I spoke with Deven for an hour to learn how he did it. Here’s his story on the changes: hyperstition.cc/training-nan…

Argh! This is so close to (part of) what I've been working on the last couple months!!

Claim: we've solved the AI slop problem (!) 💩🧹✨
Blog post: facebookresearch.github.io/R…
🧵1/5
Key idea: take *expert* human writing and learn rubrics that find the gap between experts and models. Train with those rubrics.
We train with RL-XAR (RL with eXpert Aligned Rubrics) & see large performance gains on writing scientific paper sections, Pulitzer prize novel continuations and high quality Wikipedia pages.

I'm seeing GPT-6 Sol XHigh, in one active task*, burn 15%+ of a Pro 20x account per day, a little over 100% per week.
Anyone have similar numbers to compare?
* As in not much of its time waiting for things, "constantly" thinking, sometimes some sub-agent use but not tons.
I trained a YuE2 LoRA for my daughter.
Mysteriously, it ended up sounding like a certain famous breathy young female artist.
I'm REALLY impressed with YuE2! Especially for 3B!
HF and SoundCloud links below.
(Of all the things I've been working on, I did not expect this to be the next I'd post about 😆)

Hailey Collet retweeted

Bend 2 is here!
It is a new programming language that blocks AI mistakes via *proof checking* - the same technique big AI labs used to solve open math problems, like Navier-Stokes.
It is also very fast, and runs on GPUs.
Watch the video. Link in the comments.

RELEASE DAY
After almost 10 years of hard work, tireless research, and a dive deep into the kernels of computer science, I finally realized a dream: running a high-level language on GPUs. And I'm giving it to the world!
Bend compiles modern programming features, including:
- Lambdas with full closure support
- Unrestricted recursion and loops
- Fast object allocations of all kinds
- Folds, ADTs, continuations and much more
To HVM2, a new runtime capable of spreading that workload across 1000's of cores, in a thread-safe, low-overhead fashion. As a result, we finally have a true high-level language that runs natively on GPUs!
Here's a quick demo:
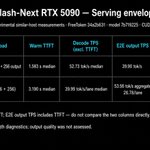
Finally have things stable enough to share. Flash-Next on single 5090 + 128GB RAM, ~53tps. Everything is exact, outputs are coherent, speeds are similar at a variety of context lengths & for different tasks, and in my limited testing get faster w/ more longer generation (task depending).
Link in reply because algorithm.
🤖 Made with AI

Currently getting 46tps at 64k with single image vision! This model is WILD.
Strong numbers hold up at temperature 0 or 1, thinking on or off, various "real world" tasks including code (some slightly faster than others, nothing dramatic, maybe 15% tops)