

Mountain biker! Technologist in my spare time, innovation, Edge, Analytics,5G,Robotics & Automation, always learning
Texas, USA
Joined May 2015
- Tweets1.9K
- Following2.5K
- Followers840
- Likes1.1K




Ari Gorman K3/Go2UNO retweeted

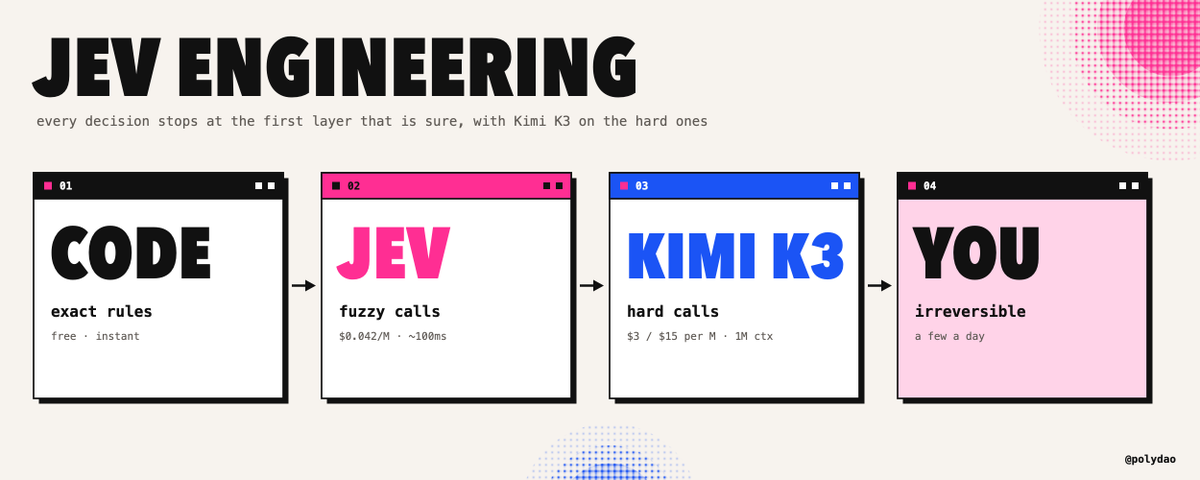
this is pure f*cking gold for anyone running coding agents
Jev founder Diogo Amogo wrote a PDF on building a Jev harness
the promise:
> 200x faster
> 400x cheaper
the model hasn't been the slow part for a while
the speed and the cost sit in the harness wrapped around it
• how to use it
> drop this PDF and the article below into Claude Code or Codex
> let it rebuild its own setup
one evening of setup
and your agent starts next week on a harness most teams still don't have


Ari Gorman K3/Go2UNO retweeted

Look who showed up as another AMD Helios system enters the wild! 👋 @OpenAI
Last week, Vamsi Boppana and @udayruddarraju joined the team for a lab tour as we continue pushing the frontier of AI infrastructure, together.

Ari Gorman K3/Go2UNO retweeted

AMD just announced the Threadripper Halo Station at IFA 2026 🤯
• 96-core Threadripper PRO 9995WX
• Up to 4× Instinct MI350P GPUs
• 576GB HBM3E (um, yes please!!)
• 16 TB/s total memory bandwisth
• Up to 2TB DDR5


Ari Gorman K3/Go2UNO retweeted
Meet ROCm 10. Here are 10 things #AMDevs need to know.
1️⃣ ROCm 10 brings AI-driven development to AMD platforms
2️⃣ ️ROCm.AI is the AI-native software experience on AMD hardware
3️⃣ ROCm.AI delivers 3.3x inference & 2.4x training improvement vs. ROCm 7 on the same hardware
4️⃣ ROCm Core SDK is open-source and optimized for AI workloads so you can customize the stack for your workload needs
5️⃣ ROCm 10 ships production-ready support for @vllm_project and @sgl_project
6️⃣ ROCm Hyperloom optimizes end-to-end inference
7️⃣ Run ROCm Hyperloom standalone or through AMD Skills
8️⃣ AMD Skills provide software and hardware expertise for your coding assistants
9️⃣ AMD Skills support the coding assistants you already use
🔟 10 years. And we're just getting started!
Introducing the AI-native evolution of the developer platform for AMD hardware: newsroom.amd.com/news/rocm-1…

Ari Gorman K3/Go2UNO retweeted

Google reportedly taps AMD to design next-generation TPU — hybrid AI ASIC could integrate on-package CPU cores for reinforcement learning tomshardware.com/tech-indust…

Ari Gorman K3/Go2UNO retweeted

$AMD EPYC Venice is far superior to $NVDA CPU.
Way too much misinformation out there. You can read the full thread below.
When Hyperscalers and AI Labs try to scale number of AI Agents and train it through RL, the highest core per socket matters.
Only @AMD could bring down Inference cost meaningfully in this Gen. I expect to hear more about EPYC Verano at Advancing AI event.
Not Financial Advice! DYOR!


$AMD $AMZN $GOOGL $MSFT $NVDA $ARM CPUs
Comprehensive Comp Part 1🧵
Why EPYC Venice is superior in Agentic AI
Dr. @LisaSu
"Venice extends our leadership across every dimension that matters in the data center."
AMD EPYC Venice is not merely a product launch, it is a declaration of architectural dominance(monopoly). The combination of 256 Zen 6c cores on TSMC's N2 (2nm) process, 1.6 TB/s memory bandwidth, PCIe 6.0 with 128 lanes, CXL 3.1 support, and up to 1 GB of L3 cache creates a processor that is categorically ahead of every competing design across every meaningful dimension.
Hyperscaler ARM CPUs from AWS Graviton5 to Google Axion to Microsoft Cobalt 100 represent ok solutions within their respective cloud ecosystems, excelling at energy efficiency and cloud-native scale-out workloads. But they are architecturally constrained: limited to 96–192 cores, 300–700 GB/s memory bandwidth, PCIe 5.0 (except Graviton5), and most critically, captive to a single cloud provider's infrastructure.
NVIDIA's Grace CPU, while innovative in its NVLink-C2C integration, is a GPU companion rather than a standalone server CPU and at the rack scale, AMD's Helios platform (Venice + Instinct MI455X) offers a compelling competitive alternative to the GB200 NVL72 at a much much lower TCO,TDP and cost per million tokens
For enterprise customers, cloud architects, and investors, the message is clear: AMD EPYC Venice extends AMD's leadership in every dimension that matters for the next generation of AI factories, HPC clusters, and hyperscale datacenters. With a confirmed Q3 2026 launch timeline, Venice will be the defining server CPU platform of the 2026–2027 AI infrastructure supercycle.
A. AMD's Server CPU Market Trajectory
AMD's rise in the server CPU market is one of the most dramatic reversals in semiconductor history. From less than 1% market share in 2017, AMD has grown to approximately 29% by late 2025, with EPYC Turin (5th Gen, Zen 5) driving record enterprise and hyperscale deployments.
~10 of 10 major social media platforms now run EPYC including Meta, which was historically an Intel-only shop
~ 10 of 10 large SaaS organizations have converted to EPYC
~3× year-over-year public cloud adoption growth by large customers
~AMD's target of 50%+ server CPU market share is achievable by 2027 with Venice and Verano
~ 100% of AMD Helios AI racks (pairing Venice CPUs with Instinct MI455X GPUs) use EPYC as the host CPU, locking in CPU sales tied to AI GPU deployments
B. The Hyperscaler ARM CPU Ceiling
While hyperscaler ARM CPUs (Graviton, Axion, Cobalt) offer excellent price-performance for cloud-native workloads within their respective clouds, they suffer from fundamental structural limitations that AMD Venice does not:
~Captive ecosystem: Each hyperscaler CPU is only available within that cloud provider's infrastructure= zero portability
~ARM ISA barrier: Enterprise software (SAP, Oracle, legacy databases) runs natively on x86 only; ARM requires recompilation and testing
~ Core count ceiling: ARM's Neoverse CSS V3 maxes at 128 cores per socket; AMD Venice doubles this with Zen 6c
~Memory bandwidth deficit: Cloud ARM CPUs prioritize efficiency over raw bandwidth, leaving a 3–5× gap vs. AMD for AI workloads
~No independent access: Enterprises cannot buy Graviton5 or Google Axion servers; they must consume compute via cloud billing
C. NVIDIA Grace is not Not Competitor
The NVIDIA Grace CPU is better understood as a complement to AMD's strategy than a direct threat. NVIDIA's decision to use ARM Neoverse V2 cores (rather than developing a custom x86 or proprietary architecture) validates the ARM ecosystem's viability, while simultaneously confirming that GPU-centric companies view CPU performance as secondary to GPU-CPU interconnect bandwidth. AMD's Helios platform (Venice + Instinct MI455X) competes directly with NVIDIA's GB200 NVL72 at the rack scale, with AMD offering significantly more CPU cores and memory bandwidth in the host CPU tier.
1. Maxium CPU Cores Per Sockets
AMD EPYC Venice's 256-core configuration is unmatched across all competitors. The 33% advantage over AWS Graviton5 (192 cores) translates directly into higher throughput for massively parallel workloads including LLM inference, database query processing, and scientific computing. The hyperscaler ARM CPUs (Graviton4 at 96 cores, Google Axion at 96 cores) are limited by the Neoverse V2 core density ceiling, while AMD's Zen 6c compact cores leverage 2nm density to pack 32 cores per CCD across 8 CCDs.
2. Memory Bandwidth Comp
Memory bandwidth is the single most critical bottleneck for AI inference and database workloads. AMD Venice's 1,600 GB/s (1.6 TB/s), achieved via 16 DDR5 channels at up to 12,800 MT/s with MRDIMM creates an insurmountable gap. The NVIDIA Grace Superchip reaches 1,000 GB/s via LPDDR5X but requires pairing two dies and is not a standalone general-purpose CPU. Cloud ARM CPUs range from just 300–537 GB/s, meaning AI applications will be starved for data at scale.
3. Process Node Tech
Process technology determines transistor density, power efficiency, and performance per watt. AMD's TSMC N2 (2nm) adoption in Venice is a strategic masterstroke; it delivers GAA (Gate-All-Around / Nanosheet) transistors that offer superior electrostatics, enabling 10–15% more performance at iso-power versus 3nm FinFET. AWS Graviton5 and Google Axion use 3nm, Microsoft Cobalt 100 lags at 5nm, and NVIDIA Grace uses 4nm. AMD's 2nm lead ensures that Venice will remain the most power-efficient x86 server CPU available through at least 2027.
Not Financial Advice!


AMD Just Scored a New Autonomous Driving Customer. It’s Aiming at Nvidia in Another Arena. barchart.com/share/news/3168… via @Barchart

118
Ari Gorman K3/Go2UNO retweeted

This 40 minute lecture from Peter Thiel at Stanford will teach you more about business competition than a 2 year MBA program
Ari Gorman K3/Go2UNO retweeted

A great video that explains all the changes coming to Formula 1 in 2026
Ari Gorman K3/Go2UNO retweeted

This is still one of the craziest catches I’ve seen and I feel like it doesn’t come up much.
Futuristic yacht makes unprecedented achievement after transforming sea water into next-gen fuel — here's what we know tech.yahoo.com/science/artic…

1
55


Surprisingly simple coding trick can slash data center energy usage by 30% livescience.com/technology/c…

1
41
Ari Gorman K3/Go2UNO retweeted

CES 2025 is now over, and it was insane!
Here are the 15 best tech and gadgets you shouldn't miss:

Ari Gorman K3/Go2UNO retweeted

It's been 3 days of CES 2025, and the announcements have been wild.
Here are 12 reveals you don't want to miss from CES 2025:


