
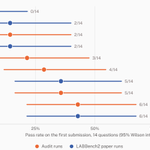




LABBench2 has been used by several labs and other orgs to measure the bio-capabilities of frontier models.
We audited it and found some issues: many task sets are saturated, two are flawed, and the rest are at least moderately concerning. More below🧵

Recommendations:
• Report LABBench2 per task set, not as one aggregate
• Drop the saturated sets (TrialQA, PatentQA, SourceQuality, TableQA2, maybe LitQA3) unless checking for regression
• Fix harness for model comps, especially for DbQA2 and SuppQA2
More in the full post, including gated transcript examples: generality.org/blog/posts/la…
And the SeqQA2 post: generality.org/blog/posts/la…

Is GLM-5.3-Flash Mythos-level at cyber?
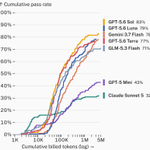
In our latest post, we find that GLM-5.3-Flash can outperform Mythos Preview on ExploitBench at ~6% of the price.
We do this by scaling up inference tokens to 1B per vulnerability.

see the post for more:
generality.org/blog/posts/gl…
