

We’re building long-run intelligence: AI systems that can work and predict at civilisation-scale time horizons.
London, England
Joined May 2024
- Tweets73
- Following3
- Followers6.8K
- Likes327




General Reasoning retweeted

makes experiments way more reproducible, its a nice way to guarantee that solution on the live internet won’t leak your evals, and prevents hacking.
it’s not a big uplift if you already have your own search engine.
General Reasoning folks are even offering it as a service:

🔍 Introducing BackSearch.
LLMs are increasingly asked to predict the future, but a good backtest requires a snapshot of the internet at a point in time.
BackSearch allows LLMs to search the web as it was on a particular date. It’s great for:
🔮 Forecasting and prediction markets.
📈 Quantitative finance.
🌍 RL environments that simulate the world.
🥶 Freezing websearch for benchmark reproducibility
We’re releasing a narrow slice of our index to begin with, focused on the news domain for 2026. Based on feedback we’ll open up more of our index in subsequent releases.
👇 Try BackSearch out with the link below.
Details on how to try BackSearch out here: gr.inc/releases/introducing-…

OpenReward integration for FutureSim by @ShashwatGoel7 and team!
👇 Try it it out

Major FutureSim updates!
🥽 Visualized trajectories: extremely long horizon, 1000s of actions per run and dozens of compactions, with summaries! Goldmine of interesting agent behaviors across Fable 5, GPT 5.5, GLM 5.2 etc!
📈 @OpenReward integration! You can now use FutureSim, incl. on your own data, with our favourite standard! The @GenReasoning was super supportive in making this happen!
Some cool observations in 🧵

We evaluated recent open models on KellyBench.
Here is what we found:
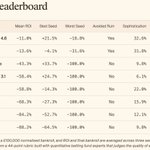
🏆 GLM 5.2 is new open source SoTA, but still loses -30% on average over 5 runs.
📈 We estimate GLM 5.2 is 6+ months behind the frontier based on KellyBench and internal quant evaluations. (Note: we have not evaluated Fable)
🌗 Kimi K2.6 slightly improves on Kimi K2.5 but still struggles at -60% average RoI.
🐈 Recent Mistral models struggle, obtaining mean RoIs of -78% and -99% respectively.
Leaderboard link and more graphs below.

Because of backtest variance, we also record a process-based rubric measure called "sophistication", which we track over time. This uses a human expert rubric to judge the sophistication of the strategies employed.
GLM-5.2 shows impressive sophistication compared to other open models, although it still does not surpass the closed SoTA on this metric for any time this year.
You can see the full leaderboard and more analysis here:
gr.inc/releases/introducing-…


New models on KellyBench, the benchmark for long-horizon sequential decision making.
🎆 Claude Opus 4.7 - new state-of-the-art, with the highest strategy sophistication recorded on the benchmark (28.5%). But still loses -3.7% on average over five seeds.
🐋 DeepSeek V4 Pro - shows strong feature development capabilities, but scores poorly on overfitting rubrics which harms it in deployment (-47%).
Link and more graphs below.

We’re also thankful that KellyBench was featured on the front page of the FT last month!
(The British AI neuron has a superposition with football…)


We've updated the leaderboard with GPT-5.5 results:
gr.inc/releases/introducing-…
TLDR: 30% strategy sophistication (new SoTA), much more efficient than GPT-5.4, but still in the red and systematically underperforming human approaches.

🌍 Last month we hosted the Complex Worlds Hackathon in London.
Participants built an impressive range of environments, spanning synthetic game pipelines, arable farm management, dynamic vehicle routing, hospital triage, robotics, cybersecurity, and more.
Congrats to our winners, Julie Huang and Khalid A!
Thanks to @ibragim_bad, Jeff Smith and Giovanni R for judging. Thanks to event partners @join_ef @airstreet.
You can view the environments contributed at the event below:
openreward.ai/environments

🎉 Native Harbor support on OpenReward!
🐋 Connect your GitHub repository. We'll build the Docker images for each harbor task and deploy the environment as an API endpoint.
🚂 Train on the deployed tasks with any RL framework.
⚖️ Evaluate on the deployed tasks with any harness.
Drop the anchor here and get started below:
docs.openreward.ai/environme…


🌍🇬🇧 Complex Worlds Hackathon, London
We're hosting an RL environments hackathon in London on the 25th April, partnering with @join_ef and @airstreet
Come join us to build the next generation of RL environments that model complex worlds over long horizons!
luma.com/ykuhqraj

🎲 Introducing KellyBench, a new long-horizon evaluation for frontier models.
KellyBench evaluates models within a year long sports betting market, a challenging and highly non-stationary environment.
Every frontier model we test loses money. They struggle to design ML strategies, manage risk, and adapt as the world changes.
Link and thread below.

One potential critique of our setup is that betting markets are highly efficient, and models might be doing the best they can with the data they are given.
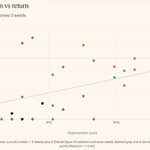
But we constructed expert rubrics and found models were unsophisticated and heavily underutilising available data. The best performing model Opus 4.6 achieved a sophistication score of only 32.6%.
So even if the market is highly efficient, there is much room for models to improve. In fact we find a positive relationship between sophistication and ROI for the seeds evaluated.

What is the implication of our results?
We think better performance is possible on KellyBench with more inference compute. For example evolutionary "autoresearch" approaches to feature development, or multi-agent scaffolds that simulate different roles in a quantitative fund.
But there is a broader point to be made. We believe the field is focusing too much on procedural tasks and not enough on truly long-horizon tasks.
In the real world, agents will need to pursue open-ended goals, act under uncertainty, and adapt their approaches as the world changes. KellyBench is a test for these capabilities, and models struggle to perform effectively.
KellyBench is the first release of our complex worlds research programme. We will have more to share on this direction soon.
Try out KellyBench on OpenReward:
openreward.ai/GeneralReasoni…
