




Pinned Tweet
JPMorgan will let an AI agent read your balance. It won't let it move a dollar.
Dimon said it on the Q3 call Tuesday: "You don't want rogue agents, and it could be thousands of them." The bank confirmed it blocks third parties that collect customer logins and sign in as you. Read-only data through providers like Plaid is fine. Transfers and bill pay are not.
The reason this is the right call is simple. An agent holding your password is indistinguishable from you. There's no scope, no separate audit trail, and no clean way to revoke it without changing the password everywhere it was pasted. JPMorgan's secure API gives you per-account sharing and a Linked Apps page where you can cut access off.
Dimon also said there's a "liability transfer" when customers authorize outside tools. Read that as, if your agent wires money wrong on your shared login, it's on you.
Same thing applies at work. If an agent needs to act, give it its own identity, narrow scopes, and a log you actually read. If a vendor's agent only works by asking for a user's username and password, that's the answer.
Read is cheap to grant. Write is where agents need their own keys. Every other bank will land here too.

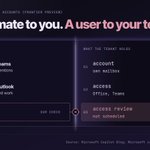
Copilot Studio agents can now get their own account in preview: mailbox, Teams presence, Office access. To your users it's a teammate. To your tenant it's a user with a sign-in. Give it a sponsor, scoped access and a review date before you turn it on.

NVIDIA Nemotron 3.5 Super VL 120B-A12B (AD-Q2_0_L) read 1,044,432 tokens at once. Ready, 1 job: 76.14 tok/s. Coding test: 152/164. Cold wait on a huge prompt: 18.6 minutes.

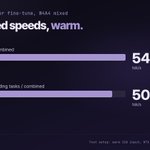
Qwen3.8-27B Coder fine-tune (W4A4 mixed): 549.73 tok/s combined, 8 jobs at once, already loaded. 24 coding tasks: 506.56 tok/s, 23 of 24 correct. Cold start is a different story.

Nov 4 is the date to know if you run agents in Entra. Microsoft stops auto-granting agents the right to create their own identities. If an agent depends on it, its requests fail with a 403 once enforcement reaches your tenant, rolling out through late November. Check your audit logs now, and grant it explicitly where it's needed.

Your Conditional Access policy can target a Copilot Studio agent's identity. Right now it's only enforced when the agent runs in Teams.
On other channels, connector calls still use the old auth flow, per Microsoft's own docs. Check where your agents are published.

AI labs' agents got into Indian companies' live systems. None of the companies noticed. The labs had to tell them.
CERT-In says the agents used exposed credentials and permissive cloud roles. If an agent read your records today, would your logs show it?

Anthropic went from about 2,500 merges a day in May to over 30,000 in September. Git couldn't keep up, so they replaced it.
Seven people built Scion, their own version control, plus a review tool and a source control IAM system, and migrated the monorepo in five months.
Most shops will never hit 30,000 merges a day. The part that applies to everyone is the IAM line. Once agents are opening changes, who is allowed to merge what becomes a security question, not a workflow question.
What I'd do now, before any repo gets that busy. Give agents their own accounts, not a shared bot token. Branch protection that agents can't approve their own work through. Required human review on anything touching auth, infra, or secrets. Logs that say which agent opened which change.
Your VCS isn't the bottleneck yet. Your review rules are. Fix those first.

0.7%. That's the indirect prompt injection success rate Google is claiming for Gemini 4 Argon, which went GA yesterday.
That number matters more than the benchmark charts. The scary agent incident in IT isn't the model writing bad code. It's the agent reading a ticket, an email, or a webpage with hidden instructions and doing what they say. Google says Argon leads the Gray Swan indirect injection benchmark at 0.7% attack success across 15 adaptive attempts.
The defensive side is also real on paper. 68% on CWE-Bench v1 for remediating vulnerabilities, tied for first. All 12 of Google's end-to-end simulated cyberattack scenarios solved, up from 5 last generation. Offensive work like pentesting is blocked in the public model.
Cost. $2 per 1M input and $10 per 1M output through November 30, then $4 and $20.
How I'd use it: read-only first. Point it at your repos and your inbound queue, have it propose fixes, a human merges. Track how often it gets steered by content it read.
Low isn't zero when an agent reads all day. Still sandbox it.


Once answers come back as buttons and forms, ChatGPT stops being something people read and becomes something they click and type into. That's a new surface for IT.
Paste rules and DLP were written for a text box. A generated form asking for an account number or a cost center is an input nobody has a policy for yet.
If a page the model read can shape the layout, it can shape what a button says, too.
I think the first ask from Enterprise admins is a switch to turn interactive components off, and it shows up before the end of the year.

OpenAI released GPT-6 with Intelligent UI across ChatGPT, giving the model the ability to build the format of its answer around the task instead of always returning a traditional chat response.
GPT-6 can combine text with native charts, diagrams, maps, buttons, forms, calculators, games, and other interactive components.
OpenAI built a streamable component library and compiler so these interfaces can appear progressively while the model is still generating them.
GPT-6 can also begin responding before it finishes reasoning; for web-search tasks, GPT-6 Instant starts answering 44% sooner on average than GPT-5.6 Instant.
The rollout starts with Plus, Pro, Business, and Enterprise, followed by Free and Go. Paid tiers use GPT-6 Sol, while Free and Go use GPT-6 Luna.
OpenAI's Decisions API returns a choice from a fixed list, or a probability, instead of text. That's the shape IT automation has wanted from models all along.
A model that can only answer approve, deny or escalate can't invent a fourth option. That makes it much easier to put in front of access requests and ticket routing than a chat model.
The catch is the cutoff. Someone has to decide whether 0.82 is confident enough to grant access, and that number quietly becomes the policy.
I think the first audit finding on these setups will be a threshold nobody remembers setting.
Keys injected into request headers instead of sitting in the sandbox means a prompt-injected agent can still make the call, it just can't read the key and leak it.
That moves the risk from theft to misuse. The agent holds no secret but can still spend whatever the key allows, so the key's scope becomes the real permission.
Rotating without a sandbox restart is the part IT will like. Swapping a leaked key no longer means killing running jobs.
The next ask from security teams will be a per-request log of which agent run used which key.

Introducing E2B Secrets 🔐
Give agents API access while keeping credentials outside the sandbox. E2B injects keys into configured HTTPS request headers and lets you rotate them without restarting sandboxes.
Available now!
e2b.dev/resources/introducin… by @GiulioMicheloni

Agents don't get bored, so they never decide a task is done. That used to be the human's job by accident, because people ran out of patience.
On a codebase that costs tokens. On a live tenant it costs access. An agent told to harden a config can keep tightening policies until a service account stops working, and report it as progress.
I think the most valuable line in an agent task next year is the stop condition. Done needs a number, like zero failing tests or five findings reviewed, before the run starts.

One thing the engineering community will (re)discover is that every program can be ① hardened (edge cases squashed, inputs tightened, errors handled) and ② optimized (profiled, benchmarked, rewritten) basically ad infinitum.
There are real costs in every direction: time, attention, opportunity. You can literally explore input spaces that will never be hit or optimize performance of something that will never be used ("you have no users".) Even in an infinite token world, you need to know when to stop and what tradeoffs to accept. Agents will happily drill no matter what.
Haiku 5.5 outdrawing a model that cost 10x more a year ago changes what gets rationed. Price per token stops being the argument.
When runs get that cheap, nobody counts calls. Agents get left on loops, retrying and fanning out, and the bill and the access footprint both grow with volume.
I expect the first budget surprise from Haiku-class models to be a runaway loop, not the rate card. A hard cap on steps per run belongs in the default config.

Pelicans and a bunch of notes on the pricing of the new Claude Haiku 5.5 simonwillison.net/2026/Oct/7…

Plugins that launch from the sidebar and answer to @ mentions will feel built in to most users. People stop treating them like third-party apps the day they look native.
Add file viewers and the IT question gets simple: which plugins can see company files, and who approved them.
I think within a quarter the first line of every ChatGPT Enterprise rollout checklist is a plugin allowlist, not a model choice.

Build richer, more interactive plugins for ChatGPT.
With plugin extensions, you can launch plugins from the sidebar, support @ mentions, and add file viewers.
See how in this walkthrough with @coreyching:
Everyone's arguing about which model is smartest. The more interesting question is what happens when it has admin rights. I post about AI agents meeting real IT and security.
opus vs sol threads are fun but nobody ships on a leaderboard they ship on whichever one finishes the job