

Institute for Explainable Machine Learning @HelmholtzMunich and Interpretable and Reliable Machine Learning group @TU_Muenchen
Munich, Germany
Joined August 2021
- Tweets400
- Following108
- Followers3.3K
- Likes210




Explainable Machine Learning retweeted

What does an LLM think of you?
LLMs pick up the slightest implicit cues about users. Often, they refuse to say who they think the user is.
In our new preprint, we show how to read and change these hidden beliefs. Turns out they even affect whether the model refuses
New paper🧵
Explainable Machine Learning retweeted

📣 New preprint: Replay on Demand (RoD)
Imagine you had 10 hours to refresh everything you learned in school.
Would you divide them equally across every subject?
Probably not. You’d spend your limited time on what you’ve forgotten most.
🧵 arxiv.org/abs/2609.40089

Explainable Machine Learning retweeted
📣 Introducing MedKIT, our new benchmark for knowledge integration in LLMs, accepted at #NeurIPS2026!
🧵 Why recalling updated facts ≠ integrated knowledge and why we need methods that can bridge this gap:
📄 arxiv.org/abs/2609.38543

Explainable Machine Learning retweeted
🎉 CapTrack has been accepted to #NeurIPS2026!
CapTrack extends LLM forgetting evaluation beyond general knowledge to capabilities.
We find forgetting is highly heterogeneous across capabilities.
⚠️ If you touched the weights, check what changed.
📄 arxiv.org/abs/2603.06610

Explainable Machine Learning retweeted

FineVision was just accepted to NeurIPS! Big thanks to all my co-authors, excited to present it at the conference


We will have two poster presentations and one workshop poster at #ECCV2026 in Malmö🇸🇪!
Please come and say hi if you are interested in topics related to multi-modal learning. Details in the thread👇
🤖 Made with AI

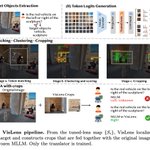
VisLens reads the model's own hidden states. A logit lens projects each image region through the LLM head to reveal what it already says; a light tuned-lens makes early layers readable. Match decoded tokens to the query, cluster, merge into crops, answer.

