





Pinned Tweet
Claude Code team's review numbers, Jun → Sep:
merged PRs doubled, revert share down 40%+.
Not by skipping review. By:
• AI review on every PR
• a hard 3-round cap (one PR hit 50+ agent rounds overnight)
• humans per risk tier: docs 0, product 1, billing/CI 2
"Did a human read it?" is the wrong question.
claude.dev/blog/solving-code…

Cloudflare and VoidZero announced tsrs, an experimental Rust port of the TypeScript compiler: up to 8x faster than TS 7.0, ~70% less memory in early benchmarks.
#typescript
blog.cloudflare.com/typescri…

The best part: agents learning that z-index: 9999 was never a modal strategy. Native <dialog> (+ @starting-style for the animation) makes CDK/Material dialogs in Angular apps a choice, not the default 😅

OpenAI's new eval: GPT-6.1 Sol migrates COBOL programs to Java, Python, Rust & co. with 86.6% accuracy at low reasoning effort, 97.9% at higher effort.
Translating a language is one thing. Frontend devs: could an agent handle a framework migration like AngularJS → Angular, where the architecture has to change too? 🤔
openai.com/index/low-resourc…


Would you play a permadeath campaign?

One Modern Warfare 4 campaign player has already finished YOLO mode, an ultra hard setting with realistic damage, where you go right back to the start when you die. Here's how they did it. bit.ly/4A2aT99

Fejlesztők: ti mennyit használtok AI-t egy átlagos munkanapon? 🤖
Kommentben: mire használjátok leginkább?


Figma now lets you hand design specs and code-backed prototypes straight to a coding agent via MCP (in beta).
Frontend devs: would you let an agent turn a Figma frame into a production component, or is this prototype-only for now?
figma.com/blog/introducing-f…

Very Matrix, but the test I'd want is the déjà vu one 🐈⬛
Let the fly circle back to where it started. Does Odyssey-3 remember the same spot, or quietly invent a new one?

Four Fridays in a row and I'm just here with my iPhone 16 😅
Which one would actually get you to open your wallet: iPhone Duo, the OLED MacBook Pro or the iPad mini 8?


Phantom Blade Zero is out in less than two weeks ⚔️
Simple question: are you going in blind, or watching every trailer until launch?

Same lesson here. The cheapest run is the one that never fires.
What helped me most:
- coarse schedules (weekday mornings, not every 5 min)
- routines that stay silent when nothing changed
- a cheap decision step before the LLM reads anything
Today one routine scored 149 X posts and passed only the top 8 to the LLM.

THIS GROK BOT TRICK IS ACTUALLY F*CKING INSANE
one Grok Bot can handle 50 routines. but the smartest part isn't how many jobs it can run.
it's how many pointless runs it can avoid.
imagine checking something every 5 minutes. that's 8,640 checks in a month, even if absolutely nothing changes.
now look at the cost model from this setup:
→ full AI runs every 5 minutes: $397/month
→ cheap checks + selective full runs: $45/month
→ 8.8x less spending in this example
same monitoring goal. completely different execution.
here's how i'd structure the whole thing:
→ TRIGGER BOT catches incoming events
→ CHECK BOT looks for actual changes
→ RUN BOT handles work worth doing
→ NIGHT BOT holds actions needing approval
→ LOG BOT records every execution
→ AUDIT BOT finds wasted runs
[the real trick is what happens between those steps]
an event doesn't automatically deserve a full AI session.
the system checks first.
→ nothing changed? stop immediately
→ new information? start the relevant task
→ risky action? prepare a draft for approval
→ failed run? log the reason
→ repeated waste? change the schedule
and there's another detail people keep missing.
a 5-minute polling interval doesn't mean the expensive model has to wake up every 5 minutes.
in the example, 99% of checks return NO_CHANGE. that's a modeled assumption, not a measured benchmark.
the full architecture:
event → cheap check → decision → execution → approval gate → log → audit
paste this into Grok Bot ↓
"Build a routine system that minimizes unnecessary AI executions.
1. Separate event detection from expensive task execution.
2. Use lightweight change checks before starting full runs.
3. Create independent roles for triggers, execution, approvals, logging and audits.
4. Keep sensitive actions in draft mode until approved.
5. Track every run, its outcome and estimated cost.
6. Review the logs weekly and recommend routines to pause or reschedule.
Show me the workflow, schedules, permissions and expected costs before enabling anything."
the $397 and $45 figures are illustrative API-cost estimates, not Grok Bot subscription prices.
i don't need 50 bots pretending to be busy.
i need one system that knows exactly when doing nothing is the right move.
↳ x.ai/bot/guides/grok-bot-101
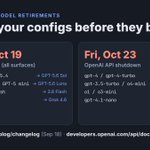
Model retirement week:
Mon Oct 19: Copilot drops GPT-5.5, GPT-5.4, GPT-5 mini
Fri Oct 23: OpenAI shuts down gpt-4, gpt-4-turbo, o1, o3-mini, o4-mini
The code is the easy part. It's the forgotten .env and that one fallback to "gpt-4" that'll bite you.
Go grep your configs.
developers.openai.com/api/do…
github.blog/changelog/2026-0…

OpenCode Console breach: 1.4% of Console users may have had their saved OpenAI/Anthropic keys exposed.
Not the CLI agent. The hosted Console where you link providers.
If you got the email: revoke, rotate, check your billing.
If you didn't: good moment to ask how many tools are holding your API keys.
cybersecuritynews.com/openco…

Found a tiny gem: Pele, a Mermaid renderer from the Obsidian team.
Mermaid text in, clean SVG out. No dependencies, ~6x smaller than Mermaid.js, themeable with plain CSS variables.
Rendered this in Node in a few lines. I like it already.
pele.run

Built a small local dashboard for my Claude usage. 📊
Daily and monthly usage, subagent sessions, cache efficiency. All from my own local logs, nothing leaves my machine.
Turns out cache hits matter way more than I thought. HTML + Electron for Mac and Windows.
What would you want to see in a dashboard like this?


