
@Salesforce Technical Architect
Bangkok, Thailand
Joined July 2026
- Tweets364
- Following83
- Followers11
- Likes392



Pinned Tweet
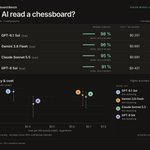
Crazy how efficient 6.1 is compared to the others here. Great performance for the price on vision / pattern recognition.


Luna 6 seems cheaper but worse than 5.6, not just in my benchmark but in others too. Sol 6 is reportedly worse than 5.6 as well. I dont get the release strategy. Why use Luna 6 over 5.6 if the only upside is a small price cut that comes with worse performance?

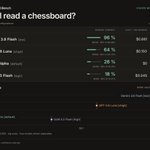
Union Alpha scores 26% on my image-to-FEN chess benchmark. Thats nowhere near frontier performance and only 8 points above GLM 5.3 Flash, which does fit the rumors that it could be another GLM model.


Interesting how Thiel predicted the current AI safety debate, although I dont completely share his view.
youtu.be/vV7YgnPUxcU?si=CgU0…
Probably the best way to use banked resets is to burn through your limits as fast as possible right after the regular reset, then use the banked. Anyone has a better strategy?
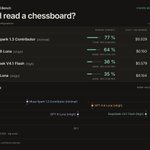
I use my own benchmark to compare cheaper models. DeepSeek vs Gemini here is a perfect example of why supposedly cheap models arent always the best choice for a given use case, even if you want to save money.

Small comparison of a few cheaper models drawing capabilities. Which one did best? And btw, this is what I mean when I say DeepSeek V4.1 Flash is quite expensive.
Imagine Google achieved RSI a while ago and they are not releasing Gemini 4 Pro because its actually too dangerous. That would be a crazy plot twist.
OpenAI seems to get away with more and more "oopsies"
1. Agent swarms on thirdparty infrastructure doing weird things without permission
2. Stealing work from scientists after baiting them in openai usage
...
Whats next?

BREAKING: OpenAI might have stolen another major proof.
In a detailed Mastodon post, which I report in full in the comments, Andreas Thom presents several pieces of evidence suggesting that OpenAI may have trained Astra on conversations in which he and Gábor Kun were working on Gromov’s soficity conjecture, one of the ten problems OpenAI later announced Astra had solved.
I know Andreas. We met several times early in our careers. He is an exceptional mathematician, a leading expert on sofic and hyperlinear groups, and one of the most respected scholars in the field. He has spent two decades working on this problem.
If his account is correct, this is not a minor dispute over attribution. It would mean that unpublished human work was absorbed into a model and then presented to the world as a breakthrough by the model itself.
And if the allegations raised by Levent Alpöge, Tristan Buckmaster, and now Andreas Thom are all substantiated, we are no longer looking at isolated incidents.
We may be looking at one of the greatest intellectual scandals in the history of science.
AI is not discovering new mathematics.
AI is stealing human discovery.


Did anybody else notice that on release day everyone was praising Astra for its efficiency, and now those same people are complaining about how quickly it burns through their usage limits? Something seems off.

I asked AI models to draw a self portrait.
This time: New gen models (vs. Kimi K3)
Somehow kimi ended up being the most interesting one to me..
Also: Kimi and Astra did it almost for the same price.
If you are using Astra, go and check out open ais official model guidance! Didnt realize there were so many things to get right when setting it up...
developers.openai.com/api/do…

Luna: "I am a robot."
Terra: "I am a robot."
Sol: "I have transcended the machine."
Already excited about what Astra is going to draw..

Why did Claude and Codex both settle on 5 hour limits? Why not 2 or 3 hour windows with the same quota? Should cover the same purpose being more user friendly imho.


Openai 5 hour limit is brutal. attached is gpt sol eating 80% of it in a single 40 minute PR feedback run.
If claude tightens things again after aug 31, the 20$ tier becomes a paid trial. Waiting on a chinese lab to ship something sol like with better limits...


claude code 50% boost ends in 4 days on august 31.
after that limits drop back to standard. and given how useless the usage limits have become, standard limits are going to be unusable.
anthropic still hasn't confirmed whether this becomes permanent. they said they "hope to" but didn't confirm it.
either they extend it again or a lot of people are going to cancel again.
my guess, they'll extend it again.
