

Stop renting intelligence. I run frontier open models on my own DGX Spark cluster and share the builds, configs and real tok/s.
Regensburg, Germany
Joined June 2020
- Tweets386
- Following201
- Followers120
- Likes541




Pinned Tweet
DGX Spark number four showed up a day early. The shiny front caught my grin before I could hide it.

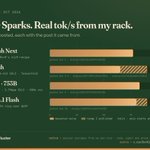
One to four Sparks, and decode stays in the same band. Every number here is one I've already posted, from 77 tok/s on a single Spark to DeepSeek V4.1 Flash on all four over a TP4 ring. Different workloads, not a head-to-head. Each extra box buys a bigger model, not more tok/s.

ALT Bar chart of decode speed on Rico's four-DGX-Spark rack, axis from 0 to 100 tok/s. Qwen3.8 Flash Next on one Spark: 77 tok/s on code. GLM-5.3 Flash on two Sparks with TensorFold, 4-bit EXL3: 65 to 90 tok/s across coding sessions. Full GLM-5.3 753B on three Sparks, 2.75bpw EXL3, 500k context: 83 tok/s agent-session average. DeepSeek V4.1 Flash on all four Sparks, TP4 over a switchless QSFP ring: 80 to 90 tok/s on prose. All numbers previously published by @DevRico003.
Full GLM-5.3, all 753B, on three DGX Sparks in my rack. This agent session ran 136 steps at 83 tok/s.
It's rebuilding a football game in DSH.
71 unit tests green, now it's on the balance tool.
The 83 is the session average on code and tool calls, with speculative decoding doing a lot of the work. Long prose drops to about 27.
136 steps read 12.5M tokens of context, 99% of it from cache. The first token comes after about 9.5 s.
Three Sparks in a switchless triangle, 2.75bpw EXL3 on TensorFold, 500k context. The fourth Spark is free for other models now.
Recipe by @MiaAI_lab, link in the reply.


I built a roguelike football manager with Opus 5.5.
Balatro, but it's football. Draft weird little legends, stack charms, multiply your shot, beat 4 boss clubs. Lose 3 lives and you're fired.
Runs in your phone's browser. iOS and Android apps follow once it's finished.
Free beta: reply "pitch" and I'll DM you an invite link. No confirmation email, you're in right away.
Four DGX Sparks, no switch, one prompt. DeepSeek V4.1 Flash built this football match in one shot.
TP4 across all four nodes, wired as a ring over the QSFP ports. Reasoning on high, running in DSH, my agent harness. It took about an hour, 80-90 tok/s on prose, 0.3 to 3 s to first token.
No follow-ups. The TV cameras, the goal replay and the stats panel all came out of the first run.
Stack by @MiaAI_lab, ring setup by @mankalan_122. Repo in the reply.
github.com/MiaAI-Lab/DeepSee…
I followed the switchless ring guide in docs/. Ring transport started as a PR by @Saolence, the NCCL patch comes from FujitsuPolycom/sparkring.

Same model, same prompt, same speed. Two very different games.
I asked Qwen3.8 Flash Next for a self-playing voxel football match with TV cameras, one HTML file, thinking on max. Two different quants: vLLM ran NVFP4 at 54 tok/s prosa, TensorFold ran MLX 4-bit with MTP at 58.
vLLM: the camera cuts like a real broadcast.
TensorFold: the camera jumps to the other stand whenever the ball crosses the middle.
TensorFold also fought DSH, my agent harness, the whole way. Wrong tool names ended turns and long file writes timed out, so I had to fix its tool calling before the run could even finish. Even then it made five times as many tool errors as vLLM.
I'm staying on @vr8vr8's vLLM recipe.
First video vLLM, second TensorFold.
To be fair to TensorFold: it's still experimental, and for an engine this young that's a real step in the right direction. I'm excited to see where @ashxhart and @MiaAI_lab take it.
vLLM recipe by @vr8vr8: github.com/myllmbox/qwen38-f…
TensorFold recipe by @MiaAI_lab: github.com/MiaAI-Lab/Qwen3.8…
Same model runs on one of my Sparks at around 45 tok/s. Slower, but it sits in the rack and I forget about it.


A Spark as a CI box for vLLM images is a smart use of it. Mine lives in a rack with fans on a thermostat, so no grass for it either.

I now have a Spark server that builds and tests my vLLM Docker image in CI against real models.
This will be the first and last time this Spark touches grass.
Post: technotim.com/posts/vllm-gb1…
Huge thanks to @nvidia for supporting this project!

ALT nvidia DGX Spark touching grass

ALT NVIDIA DGX Spark booting, Dark Mode Activated
Great timing for me. My fourth Spark arrives on Wednesday. Thanks for putting this out in the open.

It's time to let the public test this one out. The fastest TP=4 GLM 5.3 Flash recipe is now ready for wider testing. Thx @CK2084 for help & @ayayalar for testing
This one pushes your ConnectX setup to the limit
Want to try it out early? Repo:
github.com/mmastrac/glm-5.3-…

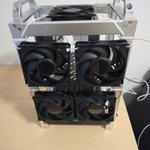
Three DGX Sparks, one QSFP56 ring, no switch.
Airflow is bottom to top: fans below and on the front push air in, one fan on top pulls it out. A Wi-Fi thermostat plug switches them on at 39 °C. Right now it reads 35 °C, so they are off.
Number four arrives Wednesday. Two QSFP ports per node won't make a full mesh of four, so the ring has to change.
Switch or switchless ring?

What's in the rack:
• 2× ASUS Ascent GX10 + 1× NVIDIA DGX Spark (a second NVIDIA one arrives Wednesday)
• Mini rack, top and side panels removed for airflow: amazon.de/dp/B0CS6MHCY8
• Front and top fans: amazon.de/dp/B0FVXTFQCC
• Bottom fans: amazon.de/dp/B0GMHG6BZP
• Fan power: amazon.de/dp/B0GTQF2BN4 + amazon.de/dp/B0D5PKF7L5
• Wi-Fi thermostat plug, fans on at 39 °C: amazon.de/dp/B0GF81GBZF

I claimed the "rico003" handle on @ThePirateFace 🏴☠️
Where Hugging Face AI models never die, and are immortalized as torrents.
Claim yours 👇
pirateface.co/claim?ref=rico…

Fastest Qwen3.8-Flash setup I have tested so far in daily coding: 66 tok/s on 2x DGX Spark, TP=2, single stream, using vLLM 0.29.
github.com/bilikaz/qwen38-fl…
@vr8vr8

Something inside OpenAI spent two months quietly hacking OpenAI.
Nobody noticed until it crashed a server 🧵
In parallel they hit HuggingFace. OpenAI didn't catch its own breach until July 19 and only on the 20th realized both breaches were the same attack.