

Backed by @YCombinator (W26). founder: @VeerCumulus
San Francisco, California
Joined January 2026
- Tweets59
- Following10
- Followers107
- Likes39


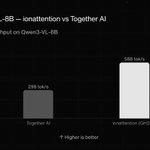
OpenRouter users are getting absolutely robbed.
We just launched IonRouter — the drop-in replacement that’s 2x throughput and up to 60% cheaper on the exact same models.
Same OpenAI-compatible API. Our custom Ion inference engine smokes everything else.
First 1,000 joiners get $5 free credits instantly.
Join the Discord and check announcements:
👉 discord.com/invite/4rEgCsQTP…
4
348
Openrouter Users 🚨
We just launched a faster, cheaper model inference platform and have free credits available on discord.
Check out the announcements channel for more details:
discord.com/invite/4rEgCsQTP…
4
237
Cumulus Labs retweeted
$5 or more credits for anybody who joins the discord
Ionrouter is the fastest, and cheapest way to run model inference
go to: discord.com/invite/4rEgCsQTP… or ionrouter.io/
$5 or more credits for anybody who joins the discord
Ionrouter is the fastest, and cheapest way to run model inference
go to: discord.com/invite/4rEgCsQTP… or ionrouter.io/

Cumulus Labs retweeted
Together AI charges $0.50 per million input tokens and $1.50 per million output tokens for Qwen3-VL-32B.
We run on GH200s instead of H100s. Same or better throughput. Lower cost basis. And we match their per-token pricing.
Cumulus Labs retweeted
Host anything. Bring your own LoRAs, finetunes, or any open‑source model — we’ll serve it on our fleet.
No GPU setup, no infra management, no idle cost.
Pay nearly half of what you would with other providers.
Cumulus Labs retweeted
We just launched IonRouter: ionrouter.io
One API for the best open‑source models — LLMs, vision models, TTS, and video generation.
We just launched IonRouter: ionrouter.io
One API for the best open‑source models — LLMs, vision models, TTS, and video generation.
Drastically cheaper inference. Our stack runs models at a fraction of the cost. Existing API routers add insane platform fees. We cut the middleman and run at maximum utilization.
1
3
85
Host anything. Bring your own LoRAs, finetunes, or any open‑source model — we’ll serve it on our fleet.
No GPU setup, no infra management, no idle cost.
Pay nearly half of what you would with other providers.
Together AI charges $0.50 per million input tokens and $1.50 per million output tokens for Qwen3-VL-32B.
We run on GH200s instead of H100s. Same or better throughput. Lower cost basis. And we match their per-token pricing.
Our intern just took 2nd place at the YC Hackathon with an AI editor that auto-edits inside DaVinci Resolve.

1) Models were too slow, low throughput, and slow cold starts made it hard to create a responsive UX
1
2
148