

Building specialist AI datasets • Fine-tuning & evaluating LLMs • ML student • Glassblower by trade, Sharing my workflows, also Hardware projects
Norway
Joined September 2026
- Tweets3.4K
- Following248
- Followers281
- Likes4.5K




Converted my wife to Omarchy today. She was complaining about her old widows laptop and how slow it was, feels like a new machine now.

Quick intro: American in Norway. Not a classic dev, my skill is getting AI to do real work.
Claude orchestrates, GPT reviews, and an AMD lab with 118GB of VRAM runs my local models. Next up: a cyberdeck build, streamed live.
Looking to connect with people building the same way.

It's a long read, but if you work with Claude or SI the read is worth it. I like the direction Anthropic is going, although i don't aways agree.

Thank you for this, @_NathanCalvin. I appreciate and am a fan of the investigative work you’ve done on behalf of AI safety and believe your comments are coming from a constructive, honest place, and that it benefits the public to have people whose job is to scrutinize the actions of frontier AI companies. I think something would be wrong if companies of the size of Anthropic didn’t get harshly criticized basically every day; strong antibodies against corporate power are a healthy feature of a free society, and especially so when issues of the gravity of the one we’re facing are at play. I also do agree that some of the examples you cite were mistakes by Anthropic.
That said, I disagree with the thrust of your post. At the core, a good fraction of the things you criticize are consequences of Anthropic’s basic theory of change that we have held for many years. Our strategy has always been what I’ve called the “race to the top” — by showing how it’s possible to build the technology responsibly, we can raise the bar for the entire industry. The forces that drive the race to the top are hugely more effective if the company practicing them is at the frontier; that’s one lesson I’ve learned repeatedly. And looking at that strategy as a whole, I’m proud of our track record and stand by it.
I believe that if we take a list of things that Anthropic did in the past year that were pro-safety and commercially costly to us, they far outweigh the list you’ve made, while at the same time I also disagree with some of the items on your list. Here are some things Anthropic has done, in the same period you’ve cited (the last year), which were very costly to us commercially while having strong safety benefits:
1. We played a key role in SB53 (and other state laws), at a time when doing so was politically perilous to the company and AI regulation was very unpopular. We in fact argued for a stronger version of SB53 than was ultimately passed; there were a lot of stakeholders and we were not the limiting factor in the strength of the bill that was passed.
2. We have very strong biological safeguards on our models, because we’ve seen concerning results in bio uplift trials and even seen and blocked potential attempts to misuse our models for bioweapons (as seen in our threat intelligence report from a few weeks ago). This is a very serious threat that we want to have zero tolerance for. But having very low false negatives means having significant false positives (despite months of effort on our part to improve the classifiers), enough so that biologists joke about how restrictive our classifiers are, and competitors sometimes sell against us by touting their more permissive bio capabilities. This has been very painful to us in an area where we care a lot about supporting an ecosystem of Claude users (biomedical science; and it is particularly frustrating to me as a biologist), but it’s the right thing to do and we intend to keep doing it.
3. Similarly, we first had Mythos-class models in February but didn’t make them generally available until June (when we had stronger cyber safeguards in place). We only offered them to a limited set of partners in order to focus on cyberdefense. It would have been much more economically rational to simply release the model to everyone. We likely sacrificed a significant chunk of a several-month model lead. But because of this, many companies secured their cyber infrastructure before the deluge of widely available cyber-capable models. Of course there are ways it could have gone better or been run better, but this was what we were aiming to do.
4. I advocated forcefully and publicly, in my essay Policy on the AI Exponential in June of this year, for the government to have the power to block model releases. Back then this was still outside or maybe on the edge of the Overton window, though I understand the window has moved since then. We were attacked intensely for this.
5. I don’t want to re-ignite conflict, but the events of February 2026 are a strong example. It is clear that our public stance could have seriously damaged the company’s future.
6. We’ve continued to advocate for export controls on chips and chipmaking equipment to China, because we think it allows democracies to negotiate from a position of strength on AI safety agreements. We’ve done this despite problems it’s created for us with industry partners who hold very different views and on whom we are very dependent.
7. As far as I’m aware we were the first, and still only, frontier company to restrict the sale of AI services to PRC-controlled companies, including those operating through third countries (otherwise a major loophole). We’ve therefore forfeited significant short-term business to prevent fueling AI platforms and applications that would help the CCP’s military and intelligence services. We are also cracking down on distillation; generally, distillation is not a major threat to us commercially, but like chip exports it has concerning national security and safety implications, so we expend significant energy and company resources to address it.
8. As you mentioned, we’ve put out a lot of reports, announcements, long model cards, public advocacy, etc, all trying to inform the public about the risks of AI. These involve a level of detail and effort that would be implausible for a purely profit-maximizing company.
9. Just this week, we announced we were putting 5% (and possibly more over time) of the company into a public benefit fund.
All of these decisions came with very substantial costs to us. To be fair, those that involved holding back or restricting access to frontier capabilities also had a broader cost — for example, the public might otherwise have benefitted from faster progress in biology, so I am not saying that our decisions were without tradeoffs — but they were not driven by profit-seeking.
For each decision, you can come up with ulterior motives that could have driven us — I think it is a general truth that any decision, on any topic, can always be portrayed as a nefarious scheme. But most of those end up being pretty farfetched or don’t fully make sense if you actually examine them closely. For example, it is deeply implausible that it would be a shrewd business move to block a large swath of research biology in order to do the work ourselves and compete with our customers; we expect the benefit to the ecosystem to greatly exceed the work Anthropic does itself, and for the two to complement each other. It is not in Anthropic’s interest to be perceived as unfriendly to biologists. Our Life Sciences Verification Program, which gives vetted biology professionals access to our models, also refutes this idea.
Of course, a different set of people will see this and make a different criticism: that Anthropic shouldn't be making decisions about who gets access to what in the first place. I agree, in the sense that ideally the government would be making these decisions, and that’s why we advocate for regulation. But for now we are forced to make them, and enabling bioterrorism isn’t a better option.
I think that even if I conceded every item in your list, I would happily hold up mine next to it; I don’t think it’s a close call. That is of course partly subjective and different things are important to different people. Maybe one way you could object is that several of the items above relate to AI misuse and not loss-of-control; if you think the latter is much more important than the former, that might change your calculus. But this is not Anthropic’s view — we view both as serious issues. You can also disagree with our decisions, as many have, but they are consistent.
But I also disagree with at least some of your list. Several items don’t represent a deviation from Anthropic’s strategy or values at all, once we postulate the “race to the top” strategy that requires being a frontier AI company. Your items 1-4 are all simply examples of what it means to compete at the frontier, and we stand by them, both in the sense that they are transparently ordinary things to do as part of that strategy, and that we stand by the strategy as a whole.
To be fair, there are important questions worth confronting (and that we are confronting) about what to do when the AI-driven acceleration gets fast enough that it is hard for safety to keep up. We are nearing that point and that’s what’s driving some of our thinking about “pacing.” But 1-4 are actions taken before that point and should be perfectly expected based on Anthropic’s strategy as a company. Of course it is possible to disagree with that strategy, but that’s a more fundamental disagreement that you could have had any time over the last few years.
I agree we could have handled your items 7, 8, and 9 better. All fall into the category of “rhetoric or policy communication that wasn’t carefully written or resulting from fast-changing circumstances not propagating from one team to another fast enough.” This kind of thing happens a lot in large organizations (Anthropic is over 5,000 people), and doesn’t even necessarily represent a failure or mistake of any single person. I am of course the CEO, and I take responsibility. The volume of communication from Anthropic is enormous and if these are the worst examples, I think we’re frankly doing pretty well, though I will continue to work hard to make sure we do even better.
Your 5th item (the change to our RSP) is the most substantive item, and people can debate this, but I think that the old, more rigid RSP created a lot of situations where we were technically required to do something that required a lot of effort but in retrospect wasn’t very important for safety, as well as not covering some of the most important things. Our current RSP’s focus on transparency brought things like risk reports and roadmaps, and its emphasis on independent external review laid the groundwork for even more intensive embedded evaluation, all of which I think have been valuable in driving a race to the top. In the original announcement in September 2023, we described the RSP as an “early iteration that we [would] build on” and said that “rapid iteration…will almost certainly be necessary.” I understand that changing plans is always a move that creates justifiable scrutiny — I just don’t think we ever represented that we wouldn’t do so.
Relating to your 6th item (having an FCF in addition to our RSP), I know our intent is to meet the letter and spirit of our regulatory obligations (via our FCF) while also remaining able to experiment with more novel approaches to risk management that go beyond what the law currently requires (via our RSP). I promise to look into it further, as it’s a complex issue and it is possible we are not weighing the considerations in the right way.
Overall, although Anthropic has made plenty of mistakes as an organization — including some of the items on your list — I feel that we have repeatedly taken serious and substantive actions counter to our bottom line and that there is a significant negativity bias distorting assessments like the one you are making above. We’ll always try to do better but, again, I am extremely proud of our track record and stand by it. I will have more to say soon about how we are going to further live our values in this moment of rapid change.
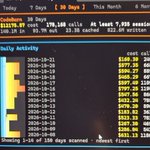
I am so sick of people yelling nerf with nothing to back it up, Opus is not nerfed. 93.3% one shot out of 1897 calls today, 88.6% one shot out of 46,706 calls the last 7 days, 87.8% one shot 178,168 calls the last 30 days. It's not nerfed, just stop. Opus 5.5 is performing the same today has he did on release. Numbers don't lie.

so finally the legendary opus 5.5 has been nerfed too
why would anthropic do this to them when everything is going perfectly well? i believe they’re testing the harness, making new changes to prepare for the upcoming fable 5.5 and this always happens whenever a new big model is about to launch
this is the only possible reason behind it or else why would they intentionally nerf a model when they’re already winning?
I need to keep this around, and maybe you should too. Omarchy

Your Omarchy machine won't boot.
Normally that means searching the error on your phone and typing fixes by hand.
Omarchy Rescue by @paolino is a rescue USB with Claude Code, Codex and OpenCode built in.
→ Boot the broken machine from the stick
→ Sign in from your phone by scanning a QR code
→ Type "my machine won't boot"
The surprise: in his demo, the agent finds what broke and fixes it in 56 seconds, start to finish.
It boots the same kernel as Omarchy and can unlock and mount your encrypted install for repairs.
Watch the demo below.
Demo credit: @paolino.
What's the worst way your Linux install has broken on you?
I’m 4-5000 hours deep into this. From rabbit hole to rabbit hole.

Something I haven't explored in my posts on RSI and would love ideas on: Using AI to create synthetic training data and RL environments.
We hear that most AI recent AI gains are coming from RL and synthetic data. Could AI be used to accelerate the production of either of those?
If you have opinions or data, I'd love to hear them!

More local juice, and co-optimized! I need more GPU's.

Our largest model yet.
763B parameters, compressed with GSQ-RCO and co-optimized with Strata (by @coldniko) for local inference.
On Hugging Face this Friday.
Much more is coming. Follow us for future releases.

Using Tracemaker and iterating to get the breakout board ready for my MU Ultra Cyberdeck build. Tons of fun.
Wow, big step up.

MiniMax-M3.1-Flash scores 42 on the Artificial Analysis Intelligence Index, 13 points higher than MiniMax-M3 and less than half the cost per task. It scores level with GLM-5.3-Flash but behind DeepSeek V4.1 Flash 1017
MiniMax-M3.1-Flash is @MiniMax_AI's new Flash reasoning model, which we benchmarked at its max effort setting. It scores 42 on the Artificial Analysis Intelligence Index, level with GLM-5.3-Flash (max, 42), just ahead of Gemini 3.8 Flash (high, 41), and behind DeepSeek V4.1 Flash 1017 (max, 45)
Key takeaways:
➤ Complex reasoning improved substantially compared to M3: MiniMax-M3.1-Flash scores 48% on Humanity's Last Exam, ahead of GLM-5.3-Flash (max, 40%) and DeepSeek V4.1 Flash 1017 (max, 43%), and level with Gemini 3.8 Flash (high, 48%). On CritPt it scores 22%, ahead of GLM-5.3-Flash (15%) and Gemini 3.8 Flash (18%) and just behind DeepSeek V4.1 Flash 1017 (24%). These are up from MiniMax-M3 which scored 39% and 4% respectively
➤ Fewer output tokens, lower cost per task: MiniMax-M3.1-Flash used ~189M output tokens to run the Intelligence Index, considerably fewer than GLM-5.3-Flash (max, ~324M), DeepSeek V4.1 Flash 1017 (max, ~224M) and Gemini 3.8 Flash (high, ~334M). Combined with pricing of $0.15/$0.60 per 1M input/output tokens, this brings its cost to ~$0.22 per Intelligence Index task, vs ~$0.28 for GLM-5.3-Flash, ~$0.26 for DeepSeek V4.1 Flash 1017 and ~$1.24 for Gemini 3.8 Flash, and less than half MiniMax-M3's ~$0.51
➤ High AA-Omniscience accuracy, offset by a high hallucination rate: MiniMax-M3.1-Flash answers 56% of questions correctly on AA-Omniscience, our benchmark measuring factual recall and hallucination, vs 28% for GLM-5.3-Flash (max) and 43% for DeepSeek V4.1 Flash 1017 (max). It attempts almost every question, resulting in a hallucination rate of 93% and an overall score of 16 on AA-Omniscience
Key model details:
➤ Context window: 1M tokens
➤ Multimodality: Text and image input, text output
➤ Pricing: $0.15/$0.60 per 1M input/output tokens, with cached input at $0.015/M
➤ Availability: MiniMax first-party API, with MiniMax announcing an open weights release on October 23rd
➤ Licensing: Closed weights currently, with MiniMax announcing a weights release on October 23rd

Has anyone put this to the test yet?

Today we published a technical report on Muse Glimmer, our 30B open-weight model built for agentic tasks on consumer hardware.
It runs at practical speeds on a Mac or PC with a single consumer GPU at 4-bit precision, and leads comparably-sized open models on tool use and multi-step planning.
Read about the model architecture, distillation recipe, quantization and more: go.meta.me/4Bcvxol

This looks like a great little model for local.

Aloha!🌺 Meet Ornith-1.5-122B: No Tradeoff Between Strong and Fast
Stronger. Faster. Leaner. Ornith-1.5-122B delivers frontier-level capabilities with exceptional inference efficiency. With superior instruction following, stronger task decomposition, and deeper understanding of real-world workflows, it achieves state-of-the-art performance among open-source models of comparable size, while running on a single NVIDIA DGX card!!
Open weights under the MIT license.
Coding
✅SWE-bench Verified: 0.845
✅TB2.1: 0.813
✅CyberGym: 0.800
✅NL2Repo: 0.512
Agentic
✅HLE: 0.446
✅BrowseComp: 0.785
✅MCP-Atlas: 0.746
✅Toolathlon: 0.708
🤗Hugging Face: huggingface.co/ornith-ai/Orn…
We can’t wait to see what you build with Ornith-1.5-122B.

CompilingThings retweeted

I'm available immediately for fractional B2B roles:
• DevRel — I build real-world demo funnels around your product, aimed both at the general public and at the audience I know best: engineers. Not toy demos, but working applications that make the product's value obvious and give people a reason to try it.
• Technical Product Advisor — I help cut, reshape and redefine product features from a deep engineering perspective: what should exist, what should disappear, what is overcomplicated, and what can actually be shipped.
I like it, sounds smart to me.

One thing I started to incorporate in testing before I ship is, RAM, CPU, and disk caching benchmarks . Q's to ask: How does it behave when you open the app? Where does the app write . What type of cpu consumption am I getting at a lunch and while app is running ? and so on.
#omarchy