


Pinned Tweet
Introducing MatFlowBench, our benchmark for LLM agents running materials science workflows.
Agents carry out first-principles calculations or design budget-limited measurement campaigns, then draw conclusions the resulting data support under the task’s stated physical assumptions.
Website: matflowbench.com
Blogpost: blog.collinear.ai/p/introduc…

Collinear AI retweeted

we @CollinearAI also scored a 1 on DadBench
scoring on DadBench beats everything as an Indian 🙏


Hundreds of new researcher friends. Two new benchmarks. One microduck. 🦆
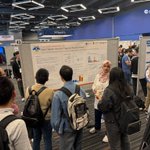
Our researchers had a blast at COLM, making friends at our booth and presenting our YC-Bench poster on long-term planning and consistent execution for AI agents.
We also introduced Frontier CUA and CWE-bench v1 to the Collinear benchmark family, with more on the way!
Thanks to everyone who stopped by to talk research, check out our poster, and chill with the team.
#COLM


Experimental tasks give the agent a measurement service backed by experimental data and every request draws down a finite budget.
Cheap screening helps narrow the pool. A pick only counts, though, if the agent also paid for the measurement that confirms it.

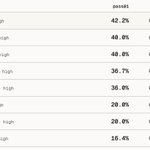
Scores are pass@1 over 45 held-out tasks. Closed models ran in their vendors’ own harnesses and open models in Terminus 2, so this compares agents rather than bare models.
Many failures came after the solver finished cleanly. Wannier models missed the DFT bands they were built from, and some agents declared success without the required files. Experimental agents often recommended a wrong material due to inefficient budgeting campaign.
Workflows, scoring and results:
matflowbench.com

Collinear AI retweeted
I will be at #COLM26 this week with many of our researchers @CollinearAI. We will present the YC Bench paper on Wednesday.
looking forward to catching up with old friends and meeting new ones. if you're interested in RSI, post-training, or cyber, please DM me for an invite-only lunch

Heading to #COLM2026? Let's meet!
We’re bringing the team behind YC-Bench, CWE-bench, and FrontierCUA.
Meet us at our YC-Bench poster and at booth 304, Oct. 6–9 in San Francisco. Link in the first comment.

ALT Nazneen Rajani, CEO of Collinear AI, presents the CatAttack poster to a crowd at COLM 2025.

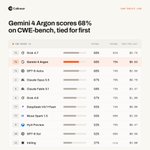
Software or Data Integrity Failures is still the hardest category on the board, averaging 36% across models. Argon lands at 36% there too.
5 of the 120 tasks remain unsolved by every model we ran.
Congrats to @GoogleDeepMind. Full leaderboard and method: cwe-bench.com

Argon posts the top score in three OWASP 2025 categories: Broken Access Control (92%), Software Supply Chain Failures (75%) and Insecure Design (67%).
By language, it leads on Go at 76%.
Gemini 4 Argon ties for #1 on CWE-bench v1.
68% programmatic pass@1 on 120 held-out audit-and-patch tasks, level with Grok 4.7 and GPT-6 Astra.

1/ Introducing FrontierCUA, a continuous benchmark for computer use agents for professional workflows. The agent must understand the requirements, explore the workspace, plan actions across multiple apps, make changes and deliver artifacts all using a sandboxed workspace. Today we're launching v0.1 of the benchmark with 15 held-out tasks. 🧵

