
building https://xitter.cf/t.co/AUZOu4LVNF
San Francisco
Joined February 2022
- Tweets56
- Following37
- Followers199
- Likes140


Joining Zoom gives us an opportunity to move faster toward our goal of giving every team a secure, self-hostable context layer. We'll be working on the same product, but with significantly more resources behind us.
Most importantly, Onyx stays open source, model agnostic, app agnostic, and self-hostable. Zoom believes in that vision, and they're giving us more room to build for the community than we've ever had.
Thanks to a brilliant 18-person team, a community of contributors, and customers who genuinely cared about this thing, we've accomplished things I didn't think were possible:
- Over 1 million queries per week
- Incredible stories from customers like NASA, Nebius, Ramp, UC San Diego, and hundreds more
- More than 30,000 GitHub stars
- A community thousands strong
@onyx_dot_app is joining @Zoom!
We started Onyx in 2023 because we believed enterprise search needed to be open source.
At Zoom, we'll be working on the same product and toward the same mission.

Chris Weaver retweeted

We’re open sourcing the first benchmark for enterprise AI search: EnterpriseRAG-Bench.
Retrieval is the foundation of every AI agent that works with company data. 1M token context windows and extended thinking are wasted if the agent can't find the right information across your tools.
EnterpriseRAG-Bench evaluates how well an AI agent can navigate hundreds of thousands of Slack messages, contradictory sources, and “official docs” that haven’t been updated in years.
The dataset is 500k synthetic documents and 500 questions across 9 sources like Slack, GitHub, and Google Drive. The corpus was created with thematic clusters, jargon, and ambiguities to reflect how real companies operate.
We benchmarked major AI platforms, popular open source projects, and enterprise search products. Here are some of our findings:
💡 Agent harness matters just as much as retrieval technique - OpenClaw with a BM25 tool cleared nearly all platforms
💡 Recall tracks quite closely with answer correctness - if you can surface the correct information, today’s LLMs can reliably generate the right answer
💡 Onyx was the only open source product at the top of the benchmark - most RAG projects are built for personal use and could not keep pace at 500k docs
This is the most technical work we’ve ever published, and the data has so many insights on how enterprise AI systems perform on company docs.
The results, dataset, and our white paper are all available on GitHub: github.com/onyx-dot-app/Ente…

many say file search has "killed vector search"
but our tests show it's more complicated than that:
- hybrid search is faster and more token efficient
- hybrid search better at scale
- file search better on complex, multi-document questions
blog: onyx.app/blog/file-search-vs…

nice writeup. I'm exploring/writing a piece on FRAG (filesystem rag) where we combine bash commands with BM25 for maximum search capability. Have you given this combo any thought?
Every enterprise AI tool right now is trying to be a chatbot.
This works for maybe 30% of workplace questions.
Most of the time, people just need to find something. A doc, a thread, a spec.
Onyx now does both in a single unified interface.
One input bar, automatic intent detection, instant results for lookups and AI answers for real questions. Sub-400ms on search, sub-1s on classification, 90%+ accuracy on routing.
We created the first agentic RAG benchmark with real workplace questions and data.
- 99 questions that were actually asked by us or our users. For example, “What common pains usually come up in discovery calls with prospects?”
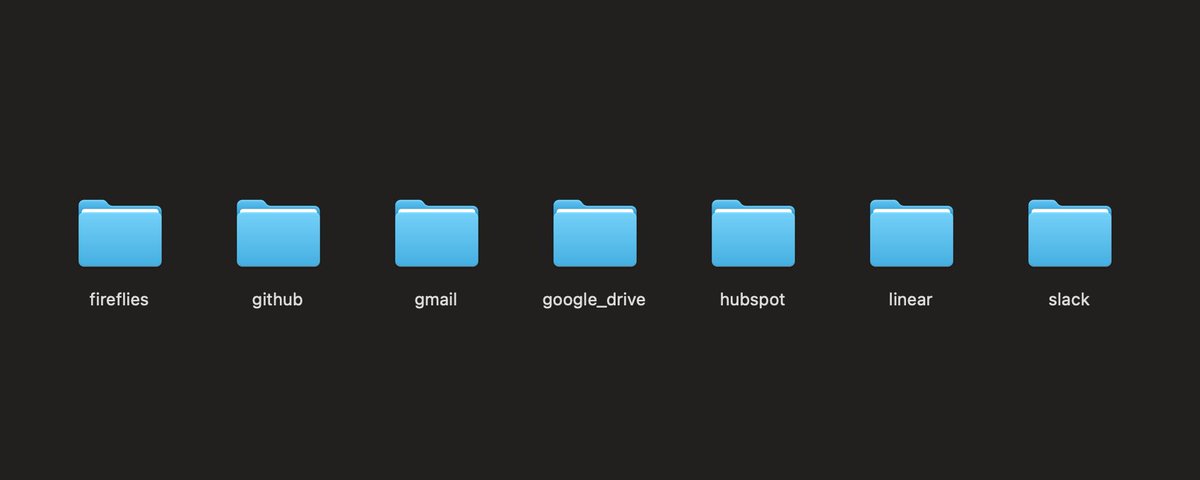
- 220k messy real documents from email, Slack, Github, Linear, Fireflies, Hubspot, and Google Drive.
- 4 independent LLM judges.
- ChatGPT, Claude, Notion AI, and Onyx as competitors.
Onyx outperformed ChatGPT, Claude, and Notion AI by ~2:1. ChatGPT came in a distant second, followed closely by Claude, with Notion AI in the rear.
We’ve published the raw results across different agents (and what we do differently to outperform) in our full blog here: onyx.app/blog/benchmarking-a….

Craft represents your Slack, Google Drive, Notion (etc.), as a file system, and gives a coding agent the ability to run bash and python against them.
Compared to RAG or MCP, this allows Craft to work well at 100k+ doc scale.
Try at cloud.onyx.app/auth/signup
Introducing Craft — Cowork, but over *all* your workplace docs instead of just your desktop.
Craft lets anyone perform complex ad-hoc analysis and build repeatable, always updating dashboards based on that analysis. And it’s all open source.
Chris Weaver retweeted
We matched ChatGPTs deep research, but with open weight models.
In a blind head-to-head, win-rate was exactly 50%.
For those interested in how it works, check out the implementation github.com/onyx-dot-app/onyx

7/7 Checkout the implementation here github.com/onyx-dot-app/onyx
Or try for free here cloud.onyx.app
6/7 We rebuilt using this approach with Exa (adding Google PSE and Firecrawl soon). Web search is actually usable now.
If you're building AI search, don't overthink it. The SOTA approach is elegantly simple.
5/7 This aligns with Anthropic's published prompts and we even did negative testing - asked about fake tools and ChatGPT corrected us.
The extra context from full pages doesn't really affect the final result. The LLM is smart enough to pick the right sources.