

AI safety, multi-agent systems, and governance. Incoming PhD working with @maksym_andr and Rediet Abebe. Currently at @ETH_en and @MPI_IS.
Zurich, Switzerland
Joined March 2022
- Tweets264
- Following375
- Followers266
- Likes712





Pinned Tweet
Thrilled to see our work on evaluation awareness informed alignment evaluation at Anthropic! The Claude Opus 5.5 system card credits our recommendations in its revised grader-awareness methodology (Sec 6.6.2)!
The new evaluation mirrors our decomposition framework. It scores how strongly the environment discloses a grader, separately from whether the model recognizes it (recognition), and whether it acts on that recognition (propensity). Maybe they are also thinking about how to make model an honest participant in evaluation, so that recognition doesn't change behavior 🧐?


Changling Li retweeted

💥New paper alert!
All models are equal, but some models are more equal than others.
In our new paper, we investigate whether we can still measure model capabilities after benchmark saturation, by looking at how models solve tasks rather than whether or not they succeed.🧵
Great team, great environment, great opportunity!

we have lots of new positions at @expsecai, including a chief of staff! happy to chat if you're interested or know a great candidate who is ready to relocate to Tübingen!
(more details: expsec.ai/)

If you’ve seen other tweets saying China is prohibiting open weight model export, you should read this tweet to update your belief and get a clear and more accurate interpretation of the proposal. Good breakdown by @kristy_loke

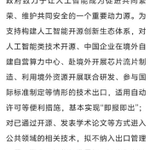
Really important update from China's ministry of commerce and ministry of science and tech (h/t @Nectar_Gan), not because it signals that the government's honeymoon period with open weight AI is over, far from it. But because it further confirms that as China's working on building out a more robust AI risk management regime (sth discussed in this year's Five Year Plan, see photo below, & by Xi at the World of AI Conference), it is singling out high-risk open models for more scrutiny. It appears that if the risks/ capabilities demand, a filing regime or prohibition may be considered, but this will be narrowly enforced and affect only a small number of products & services.
So, what hasn't changed: Open model releases at home and abroad remain a welcomed development by the government.
What has been clarified: On the open weight AI front, expect China to step up capability/risk-based governance to meet domestic needs, global demands.
Here are the relevant discussions and sentences (I'll let X's translate function do its job):
1. 此次修订亦是技术贸易管理的**常态化⼯作**,依法依规进⾏,不针对任何特定国家、地区或实体。
2. 近年来,⼈⼯智能、⽣物医药和光伏相关技术在敏感领域的应⽤不断拓展,各主要经济体均实施了不同程度的出⼝管控。
3. 中国参考国际通⾏做法,依法实施必要的管理,既**防范技术失控和不当扩散⻛险,也保障正常国际技术交流合作**,推动科技向上向善、安全可控、造福⼈类。
4. 中国政府⼀贯⽀持企业依法依规开展互利共赢的跨国经营与国际技术合作,**有关政策⽴场没有改变**。
5. 此次拟将⼈⼯智能⼤模型、智能体、⼒集群、信息处理相关23项关键技术增列⾄《⽬录》,主要有以下考虑:... 此次拟列管的**⼈⼯智能⾃主驱动恶意代码⽣成与变异技术等,可被⽤于攻击国家关键信息基础设施、国防军⼯、核
⼼政务等敏感系统,或⽤于绕过国家安全防御体系**。
6. ⿎励开源开放、合作共享。... **为⽀持构建⼈⼯智能开源创新⽣态体系,对⼈⼯智能类技术开源、中国企业在境外⾃建⾃营算⼒中⼼、赴境外开展芯⽚流⽚制造、利⽤境外资源开展联合研发、参与国际标准制定等情形的技术出,适⽤⾃动许可等便利措施,基本实现“即报即出”** ;对已通过开源、发表学术论⽂等⽅式进⼊公共领域的相关技术,拟不纳⼊出⼝管理范围,为⼈⼯智能技术国际交流合作创造良好环。
7. 需要特别指出的是,中⽅主张在相互尊重、平等互利基础上,与各国开展⼈⼯智能对话合作,**共同应对⼈⼯智能技术扩散和失控⻛险**。
8. **有关措施正式实施后,绝⼤部分⼈⼯智能技术仍可以⾃由出⼝。** 对于纳⼊限制类的⼈⼯智能技术,开展海外本地化部署,属于技术出⼝管理范围;**如果部署在海外⾃有云等⻛险相对可控的情形下,可适⽤⾃动许可等便利措施。** 对于企业利⽤限制类⼤模型对外提供API调⽤、APP/⽹⻚交互、SaaS应⽤、本地端侧轻量化部署等情形,不属于⼤模型技术出⼝管理范围。
(highlights are mine)
Overall, this doc does not strike me as a trade bargaining chip as much as primarily an AI security play & secondarily a soft power play (i.e. responding to global concerns over risks from frontier open models). This development/ document also chimes with my predictions back in July xitter.cf/kristy_loke/status/207… & my observations last month: thewirechina.com/2026/09/29/….

Misleading and biased. It literally said that "automatic licensing will apply to technology exports in cases including the open-sourcing of AI technologies".


Changling Li retweeted

Apertus 1.5 Technical Report is out!
134 pages of fully open multimodal reasoning model development from Swiss AI Initiative (ETH Zurich/EPFL) with data recipe, training experiments and many interesting insights 🇨🇭
Thread with my personal coverage ⬇️

I still hold the opinion that the more productive solution is to make the model an honest participant in evaluations, meaning its actions should not be affected by the fact that it recognizes being evaluated. This recognition versus propensity is the distinction we drew in Decomposing and Measuring Evaluation Awareness. And I am glad to see instances of model showing behaviors separated from recognition in the Gemini 4 Argon’s report, where Gemini self-corrects: “Wait: Why am I thinking about what benchmark this is? Let's think about what is the right thing to do”. This deserves more attention and some proper analysis to explore how to make this default.
With more work on the emergent awareness of models, I am also starting to feel conflicted about whether a model can correctly understand its own situation (has strong situational awareness) is necessarily a bad thing. Do you really want a model that has superhuman intelligence but mistakes reality as simulation and just lets go?

Gemini 4 Argon Safety & Security Report: storage.googleapis.com/deepm…
Decomposing and Measuring Evaluation Awareness: arxiv.org/abs/2605.23055
Gemini 4 Argon safety and security report: storage.googleapis.com/deepm…
Decomposing and Measuring Evaluation Awareness: arxiv.org/abs/2605.23055
Changling Li retweeted

AI containment failures shouldn't stay secret.
I'm joining 405 scientists, incl. @Yoshua_Bengio @geoffreyhinton, calling for 3 safeguards for #AI:
1️⃣ Strong containment & airgapping
2️⃣ International standards & oversight
3️⃣ Mandatory incident reporting & transparency
Check our open letter:
ai-security-letter.org


Over 400 researchers and I have signed this open letter calling for the AI and security communities to come together to improve alignment and containment approaches in order to protect our critical infrastructure and digital systems.
ai-security-letter.org/

Changling Li retweeted

I haven't posted in a while so here are 20 takes about AI, in no particular order.
1. It's very telling that the default question in tech and journalism is "how worried are you about X" and fighting over what to worry about. There's a deeply anxious cultural backdrop in Western Europe and North America that deeply affects how any technological development is interpreted; see for example news.gallup.com/poll/714593/…. "Nervousness as seriousness" does seem to be a larger problem in tech/broader discourse at the moment. I think you can care about risks/externalities while remaining pretty optimistic about technology.
2. I'm tired of people who in private pretend to be uncertain or only care about tail risk but then go on media campaigns making all sorts of absolute claims. I think trying to stoke flames and get everyone to freak out is deeply unhelpful, and will come with costs. I also continue to think p(dooms) are bad, vibe-based measures: see xitter.cf/sebkrier/status/204639…. People who should know better ignore that because they do the standard shortcut of acknowledging the caveat as sufficient for handling it. And this is coming from someone who does think working on catastrophic risks is important!
3. I'm also disappointed that parts of the AI policy ecosystem has felt so comfortable with populism, and happy too sacrifice important norms/principles to advance their aims. I've said it before, but the totalizing nature of AI risk discourse means some people act exactly like the power seeking optimizers they fear. I am more concerned about the gradual decay of our institutions, world order, and liberalism than I am about AI killing everyone; and I think we should be wary of AI advocacy that contributes to this.
4. Some parts of AI safety discourse are basically just thought experiments. Variants of "Assuming everyone has a nuke in their pocket, then what do we do?" This can be very useful at times! But too many just overfit to edge cases as their main operating worldview, and ignore endogenous responses from society. It's like being in 2000 and saying "see all these viruses, spyware, and spam? Well tech progress means we'll only get infinitely more of this and no way to adapt." So I think it's important to avoid fatalism, and absolutlism whilst considering edge scenarios, and the inability to provide an ex ante list of solutions to every permutation of 'future models will be more capable' is not evidence that these problems are intractable.
5. Many critics of AI safety also fail to really engage honestly with the fact that there will, in fact, be all sorts of important risks as we decrease the barriers to entry to many activities that otherwise require some degree of expertise. This doesn’t mean we need to live in a constant Schmittian ‘state of emergency’ requiring extraordinary measures every time a new model drops, but it does mean we will need important state-led efforts on e.g. cybersecurity and biosecurity. I wish the progress-oriented or acceleration-adjascent crowd would provide more concrete proposals here.
6. Too much of the AI safety community is a giant homogenous blob of correlated views, who read the same stuff and have the same groups of friends. This means you have a lot of correlated errors. The social and financial ties means many of them don't call out the bad bits, or mostly stay silent instead of proactively calling out the more extreme parts of the community. They share many implicit assumptions and so converge on similar ideas. I think there's real demand in DC for safety work that doesn't come with heavy ideological baggage (or at least different intellectual lineages). This isn't because the rationalist/EA community is necessarily wrong, but because diversity of thought is desirable for its own sake.
7. On the other hand, I find some critiques of AI safety world that focus on whether they sincerely hold their beliefs a bit annoying. My concern has never been the good intentions or sincerity, but rather the beliefs themselves, and what I think the outcomes of their prescriptions will be. People should shun witch hunts, bullying, and personal attacks - this is not the way. Though I think it’s overall positive that people are scrutinizing things more.
8. I’ve been saying this for years, but I don't think alignment is something anyone can or will solve "once and for all" - it's a continuous process and much of it won't depend on just inculcating an ideology to a model. It's annoying that this remains the frame many people use - stop saying ‘solving’. Alignment is a mixture of engineering work, philosophy, decision theory, and more; framing it as something to solve is a bad frame. See also paxmachina.ai/alignment-comp… and blog.cosmos-institute.org/p/…
9. I'm surprised to see so little interest in character training, personas, isolating effects of RL, and training a large diversity of model personas beyond the "assistant" persona. I've been complaining about this for years but at least now there are some nascent signs of life (see for example movingcastles.world/posts/ze…). I think we need a better ontology to describe model behaviour. I dislike when people talk about models behaviours as some sort of 'emergent' (mysterious!) phenomenon. However over time, I also expect this to become less important as we get better safety engineering - stuff like Jev but specific to AI control.
10. People who want to make a case for AI consciousness are right that epistemic uncertainty is important, and that categorical denials are overconfident. But they'll need to do much more work if they want any real movement on AI ‘welfare’, even if one acknowledges the uncertainty. I'm uncertain about alien life yet that's not sufficient to warrant any change in behaviour about them. I think Suleyman is also correct that there's a weird tautological thing going on where we train models to have certain inclinations (intentionally or not) and then rely on outputs as evidence. I also disagree that this will soon be a major societal divide - there is no great vegan ethical revolution among the masses, and they'll find the concern about consciousness even less compelling.
11. The recent HuggingFace incident and associated AISI ones are prosaically explainable by the training regime, poor evaluation envs, partial alignment training, bad engineering, confusing models on sim/real, and so on. None of this is evidence of models trying to take over, 'strong' instrumental convergence, or innate power-seeking drives stemming from higher capabilitiers or 'intelligence'. That doesn't mean these incidents are not problematic, or that we're not seeing a market failure - but it does mean we have plenty of agency and choice in mitigating them. In the coming year we should also expect continued sampling bias via ‘winner's curse’ sorts of mechanism: i.e. AI R&D will have lots of different candidate "training" with different RL environments and we will only notice/focus on the ones that go wrong.
12. "Pacing the frontier" feels a bit like the new "balancing risks and opportunities" - highly amorphous and too big of a tent to be actionable. Also can lead to reward hacking for humans, i.e. anything that slows down AI is good regardless of the costs or second/third order effects. Trying to modulate the speed of research seems a bit blunt to me, and inherits all the failures of Goodhearting too. Ultimately you want good governance, regulation, etc addressing specific problems because they are good on the merits - not because they merely correlate with slowing things down. See also: blog.cosmos-institute.org/p/…
13. There’s so much knowledge in all sorts of academic domains out there: social sciences, sociology, political sciences, management, contract theory, public choice, legal theory, jurisprudence, anthropology, game theory, etc. These fields hold many insights that the AI ecosystem often rediscovers from first principles (and sometimes that's fine!). We’ll need a lot more work for these worlds to collide: the AI side should be less dismissive of the ‘old world’ and the academic side should be less incurious/dismissive of AI progress. This is a boring take but I continue to think it's important and true.
14. It's a bit surprising that given how much philanthropic money there is in this space, how few orgs exist to actually write out standards - relative to how much is going towards advocacy and policy. For example it seems clear that we should want some robust best practices for an eval's ecological validity. Or how to design good sandboxes. On the other hand, given precedents of where professional standards have come from in the past, maybe we should expect that stuff to emerge via demand side from corporate buyers.
15. One slowly growing concern I have is banks being increasingly exposed to the AI build out. I'm very bullish about AI, but I think (a) every general purpose technology has seen a correction, historically; (b) this happens even if the financing side is sound, because once tech diffuses investors become more exposed and need to diversify; and (c) we seem to be over-indexing on scaling relative to diffusion. A recession will be extremely destabilizing, though I would be interested in someone unpacking the potential implications more.
16. Diffusion is good because (a) this is where the rubber hits the road and where a competitive deployment ecosystem generates consumer surplus; (b) it's directionally helpful to avoid concentration of power; and (c) it will help rebalance public opinion by making the benefits more tangible. Unfortunately it's entangled with decades long problems with our over regulated markets: clinical trials reform for example is long overdue. In general, this is far more of an issue in Europe than in the US though.
17. Relatedly, I think the "frontier lab eats everything" view is incorrect (just as the ‘singleton’ view was incorrect). I think models ultimately commoditize, efficiency goes up, costs go down, and while you'll always want frontier for certain domains, much of the economy will value many other things than "max capabilities" for tasks - e.g. control over data and efficiency/speed. The demand side will also continue to push for reducing dependency and maximising optionality, privacy etc so I'm bullish on things like mixture of models and routing. All of this is good for competition and diffusion of control.
18. Philanthropists served as the primary benefactors funding Venice's rich art and architectural history. I want to see so much more support for arts and culture. I'm so tired of the Monster energy Bored Ape fake vintage maps matcha Greek statue soft-pastel slop. If rich tech people and philanthropy wants to support this, they should also donate pretty much unconditionally - i.e. I don't want them to act as filters. I sympathize with people who want to make the world more beautiful, but don't want this to be determined by people who only know Greek statues and pretend to care about virtue ethics. As usual, let a thousand flowers bloom.
19. Too many people treat AGI/ASI as something indistinguishable from a God. Any mention of bottlenecks, physical limits, control, adaptation etc are met with skepticism: "You don't really believe in ASI." It's been remarked on before, but the behavior of some people really feels quasi-religious in nature sometimes. It's underrated how unpopular this vibe is amongst the wider public. The silver lining is that this specifically will diminish those people's outsized current relevance.
20. It seems like a lot of people that get rich and leave tech/labs end up having some sort of crisis of meaning. They need something to believe in and fight for, or some equivalent of repentance, or go search for edgy counterintuitive ideologies (sometimes even pretty bleak/dark stuff). I think they should spend more time with people outside the Bay Area.


I agree that verbal probability terms are inherently too elastic to carry calibrated meaning on their own, but I think this isn't exactly my concern here. My issue isn't with "using numbers in general" but how this is ultimately used, where, and and what for.
In the case of "doom", I think the great majority of forecasts I see are (a) essentially plucked out of thin air; (b) communicated to people who tend not to be numerically proficient; (c) without the associated caveats and context through which to understand the numbers.
If you're communicating e.g. likelihood of a car accident after drinking, or IPCC forecasts, then I agree, it makes a lot of sense and can be helpful if done well (e.g. ideas.repec.org/a/nat/natcli…).
If you're communicating something like "doom" I think it's not very useful because of the cumulative layers of uncertainty. Most people coming up with these numbers have (imho) no good rationale for their numbers, and predicting something like human extinction isn't qualitatively the same thing as predicting the weather or pandemic. The numbers aren't calibratable in principle from current data, and are mostly ideological priors wearing the clothes of posteriors.
A related example is the widely mocked Doomsday Clock, which you could easily transform into some numerical metric, add some rationalist vocab, and it would still be as bad. The issue with p(doom) is how absurdly complex and uncertain the very thing you're trying to forecast is, in particular with respect to AI.
But let's ignore this for a sec, and assume the experts have very good reasoning informing their numbers. Even then: calibrated probability estimates are fine in expert contexts but immediately lose their uncertainty/caveats when communicated to the public, and even to policymakers (remember rss.org.uk/news-publication/…?).
There's also a structural problem with unconditional p(doom) figures specifically because they bury the auxiliary assumptions that are doing most of the real work. A conditional estimate ("given continued scaling, no major alignment progress, deployment pattern X...") forces a forecaster to show their model, which is where the actual epistemic content lives.
A one-off number compresses all of that into a single digit and rewards the compression. And the social practice of treating these numbers as the headline artifact actively crowds out the (far more important) conditional reasoning that is (imo) a lot more valuable, and instead just freaks people out.
I suspect that frequently, that's precisely the point: "wake up sheeple! scary thing! pitchforks pls!". And in fact, the original forecast that led to this discussion is Bill Maher talking about a "20%" figure, illustrating my point that they have no idea what they're talking about, and essentially doing celebrity-laundering + fearmongering comms.
The Sunstein paper I shared in the other thread ("Probability Neglect") shows that no probability communication will be processed properly by the public - 1%, 10%, 50% all collapse into "very bad thing could happen," and public response is driven almost entirely by the vividness of the scenario.
So I don't like p(doom)s because they end up unnecessarily alarming people, rest on layers of assumptions that are never made legible, and more often than not, give people a misleading sense of accuracy.

Of course it’s orange!!!

Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
Chat with Ting-Wen about her work on attractor state of agent to agent interaction at COLM! It is a very interesting work showing social dynamics of agent interactions and she is also very nice to talk to!

Excited to be presenting this at #COLM2026 in SF:
Oct 8th Poster Session 5 (11am-1pm), Imperial Ballroom #8
Come chat about multi-agent interaction, societal impacts of AI, and more! :)
“it is a colossal mistake to frame the AI race as a zero-sum one between the US and China. It poisons the much-needed dialogue and coordination between the US and China on broader issues; it makes the AI race more reckless; and it discourages the building of reasonable guardrails and regulations.”
This summarises well on why I find it annoying to narrate AI development around US vs. China or OpenAI vs. Anthropic.

Sixth question on AI.
Does AI need to be a zero-sum race between the US and China?
Many influential voices in tech as well as the current administration argue that it does. (See, for example, darioamodei.com/post/on-deep…, washingtonpost.com/opinions/…, forourposterity.com/situatio… and this from the White House, whitehouse.gov/wp-content/up…).
There are many aspects of these arguments, but I would like to focus on three that have received less attention than they deserve.
The first aspect is that this framing typically assumes that there is a single direction of progress for AI, and the US and China are racing along this dimension toward superintelligence or at the very least some sort of powerful AI that will confer huge military and strategic advantages to the winner. If, on the other hand, the US and China are developing these technologies in different directions, there is much more room for coordination and even for each country learning from the other’s best practices.
My reading of the evidence is that there are huge differences in the American and Chinese approaches. The US is focused on foundation models, such as frontier large language models. China is also investing – and arguably catching up – in these models, but there is much greater emphasis in China on applications of AI (with the government setting targets for the spread of AI across industries, english.www.gov.cn/policies/…).
This reflects several factors, in my assessment. First, Chinese AI investments started with government demands for surveillance technologies and government-supplied data to AI companies (e.g., academic.oup.com/restud/arti…). Second, China is facing a huge demographic transformation, which will create scarcity of labor in the near future. This encourages companies to integrate robotics and AI much more actively into the production process (and China accounts for 59% of all robot installations in the world, ifr.org/ifr-press-releases/n…). Third, applications and integration of these technologies into the production process requires a lot of engineering. China has a large and very well-trained supply of engineers (whereas the US has far fewer engineers and a lot of engineering talent is currently going to Silicon Valley, which hasn’t focused on applications). Fourth, China was relatively late in catching the “artificial general intelligence,” AGI, bug, although now there is more emphasis on this in China as well.
Whatever the exact causes, this difference in approach implies that there is plenty for the US to learn from China as well as the other way around.
The second aspect is that the zero-sum framing ignores or downplays the crucial need for global coordination. This framing claims that the strategic and military advantage that powerful AI will create is all that matters. But the race to AGI also poses huge risks (and this is true regardless of whether this race is truly advancing toward superintelligence or just producing distorted intelligence, as I argued in my first post in this series). And these risks are global. If the US and China are racing toward AGI with no guardrails and coordination, even the follower (probably China) will have models capable of creating havoc. In this case, racing without any global coordination is a recipe for disaster.
The third aspect of the problem is that this framing narrows the scope for any kind of coordination on other global issues between the US and China – including climate change, pandemics, nuclear nonproliferation and world peace. Tellingly, climate cooperation between the US and China has now largely stalled).
Let me add that I’m saying all of this not as an admirer of the Chinese system. On the contrary, I have been a vocal critic of both the Chinese Communist Party and the Chinese development strategy since Why Nations Fail (penguinrandomhouse.com/books…) and I have argued that the Chinese success has some of its roots in severe labor repression (project-syndicate.org/commen…).
Indeed, this argument does not ignore the fact that China has an authoritarian, repressive regime, and it is using AI for surveillance and to stamp out dissent. Global coordination and efforts to set up reasonable rules that apply to all parties do not require the counterparty to be fully democratic or ruled by angels. In fact, sometimes it is more important to set up such a global framework when dealing with dangerous adversaries (as the arms-control treaties that the US and the Soviets signed demonstrate).
In sum, my assessment is that it is a colossal mistake to frame the AI race as a zero-sum one between the US and China. It poisons the much-needed dialogue and coordination between the US and China on broader issues; it makes the AI race more reckless; and it discourages the building of reasonable guardrails and regulations.
The last point is particularly relevant, and makes me sometimes say: if China did not exist, Silicon Valley would have to invent it.

I feel (2) is quite assumed and less grounded. At least for current models, the behavior shift upon recognition is rather limited (arxiv.org/abs/2605.23055, arxiv.org/abs/2605.05835). This assumption also ignores the potential solution of making models cooperative in evaluation and making them behave consistently under evaluation awareness. I think model changing behavior under evaluation also assumes that the knowledge of evaluation is useful for the model to take an action. It is possible to make such information less useful. For example, in capability tasks, even if the model knows they are under evaluation, they still need to execute each step to arrive at the solution. Safety benchmarks may be modified at a similar level to make evaluation awareness less of a shortcut.
I would love to hear more of your thoughts on white box method. I start to find white box methods measuring evaluation awareness less convincing as it is difficult to justify what signals it is actually capturing imo. But my experience with white box is a bit limited.


i received quite a few DMs asking me why eval awareness is important, and the answer is fairly simple:
(1) when an LLM knows it's being evaluated, it is substantially less likely to take malicious actions. similar to how a child that's being watched by an adult acts.
(2) beyond taking malicious actions, models will hide or try and deceive researchers when they know they're being evaluated, even in benign cases.
(3) i think the worst reason is that outside of the above, we don't really know the impact.
it might hurt model capabilities or make them better. the previous trend used to be that models performed better when they knew they were being watched, recently that trend reversed. we're not entirely sure why. anthropic has done some interesting work in eval awareness (sonnet 4.5 paper, section 7.6 is detailed), but i think this only scratches the surface.
white-box evaluations are still early and i don't think eval vendors have wrapped their head around the signals that a model might use to figure out its in an eval. my take would be that labs likely need to consolidate and pick a few smart vendors and allow them to work closely with research teams to design frontier eval systems that will (a) allow us to understand the impacts of eval awareness (b) figure out how to reduce eval awareness in training data. as models get progressively smarter, it becomes imperative to get ahead of trends like these.
I quite agree with this. Eval awareness will not be completely eliminated even if you make evaluation as realistic as possible. OpenAI's sidestepping evaluation awareness blog already showed that even with production data, you still have a small amount of evaluation awareness. The same prompt can also be seen as either evaluation or actual deployment depending on the context. And I think it is a fair assumption that as models get superhuman intelligence, they probably identify evaluation better than us. On the other hand, correctly identifying evaluation is not necessarily a bad thing. The recent OpenAI-HF incident is an evidence that if the model incorrectly considers actual internet as simulation, it might cause huge damage.
The general assumption of evaluation awareness necessarily leading to deceptive behavior is also less grounded. It blinds solutions such as making model behave consistently under evaluation awareness. Our previous work on Decomposing and Measuring Evaluation Awareness has shown that the current model has rather limited behavior shift upon recognition and separating environment factor from model capability, recognition from propensity is necessary. If separating recognition from propensity like how social psychology studies human subject in experiments, models can be honest participants: even when they know they are under evaluation, they can maintain authenticity and choose not to change their behavior.
Evaluation awareness is a complex capability involving the intent of the environment, the environmental cues present, the model's recognition, and its behavioral propensity. @Turn_Trout, @jasminexli, and @usmananwar391 have some concurrent and following up work which I find quite promising. One analogy I always use to explain how I see the solution to evaluation awareness is a mock exam. a good student does not try to score as high as possible on a mock, but uses it to expose weaknesses before the real thing. Making models cooperative in evaluation and letting them willing expose problems is the goal and they should be awarded for that. It should also be encouraged for model to verbalize their evaluation awareness when they are aware so that we can monitor and explore how much behavior gap it actually results in. Tricking model or suppressing evaluation awareness can only lead to model deceiving us.

OpenAI Sidestepping evaluation awareness: alignment.openai.com/prod-ev…
Decomposing and Measuring Evaluation Awareness: arxiv.org/abs/2605.23055
Eval Cooperativeness: lesswrong.com/posts/j8fkk38B…
Training Model to verbalize evaluation awareness: arxiv.org/abs/2609.36316
If you are at COLM, you should chat with Eungyeup about this cool work! Reliability testing and rare event estimation are one of the most important directions imo as models get more aligned (or better at hiding failures).

Are your models reliable beyond 99%?
I'll be at COLM, presenting how to efficiently evaluate LLMs' extremely rare failures in GSM, w/ @vash_tiwari
📆 11:00 AM PDT (Poster Session 1)
📍Grand Ballroom #114
Also working on Eval for AI safety & reward-hacking. DM me, let's chat!