



If you have multi-socket, from my benching you need to pin all Strata threads to one socket. NUMA (interleave) doesnt help, pinning the cores help a lot more (like +10% prefill) -- unfortunatelly that means your other CPU sit idle. (tested on Cascade Lake)

I use x2go for decades. It works. Even better as it shares the protocol over the line, so it is really fast (REALLY window-dragging-fast)
#strata 0.1.40.2, 247K context cold intake 717 tok/s -> 816 tok/s on my 2*V100 -- very good progress! 1 week ago it was <500
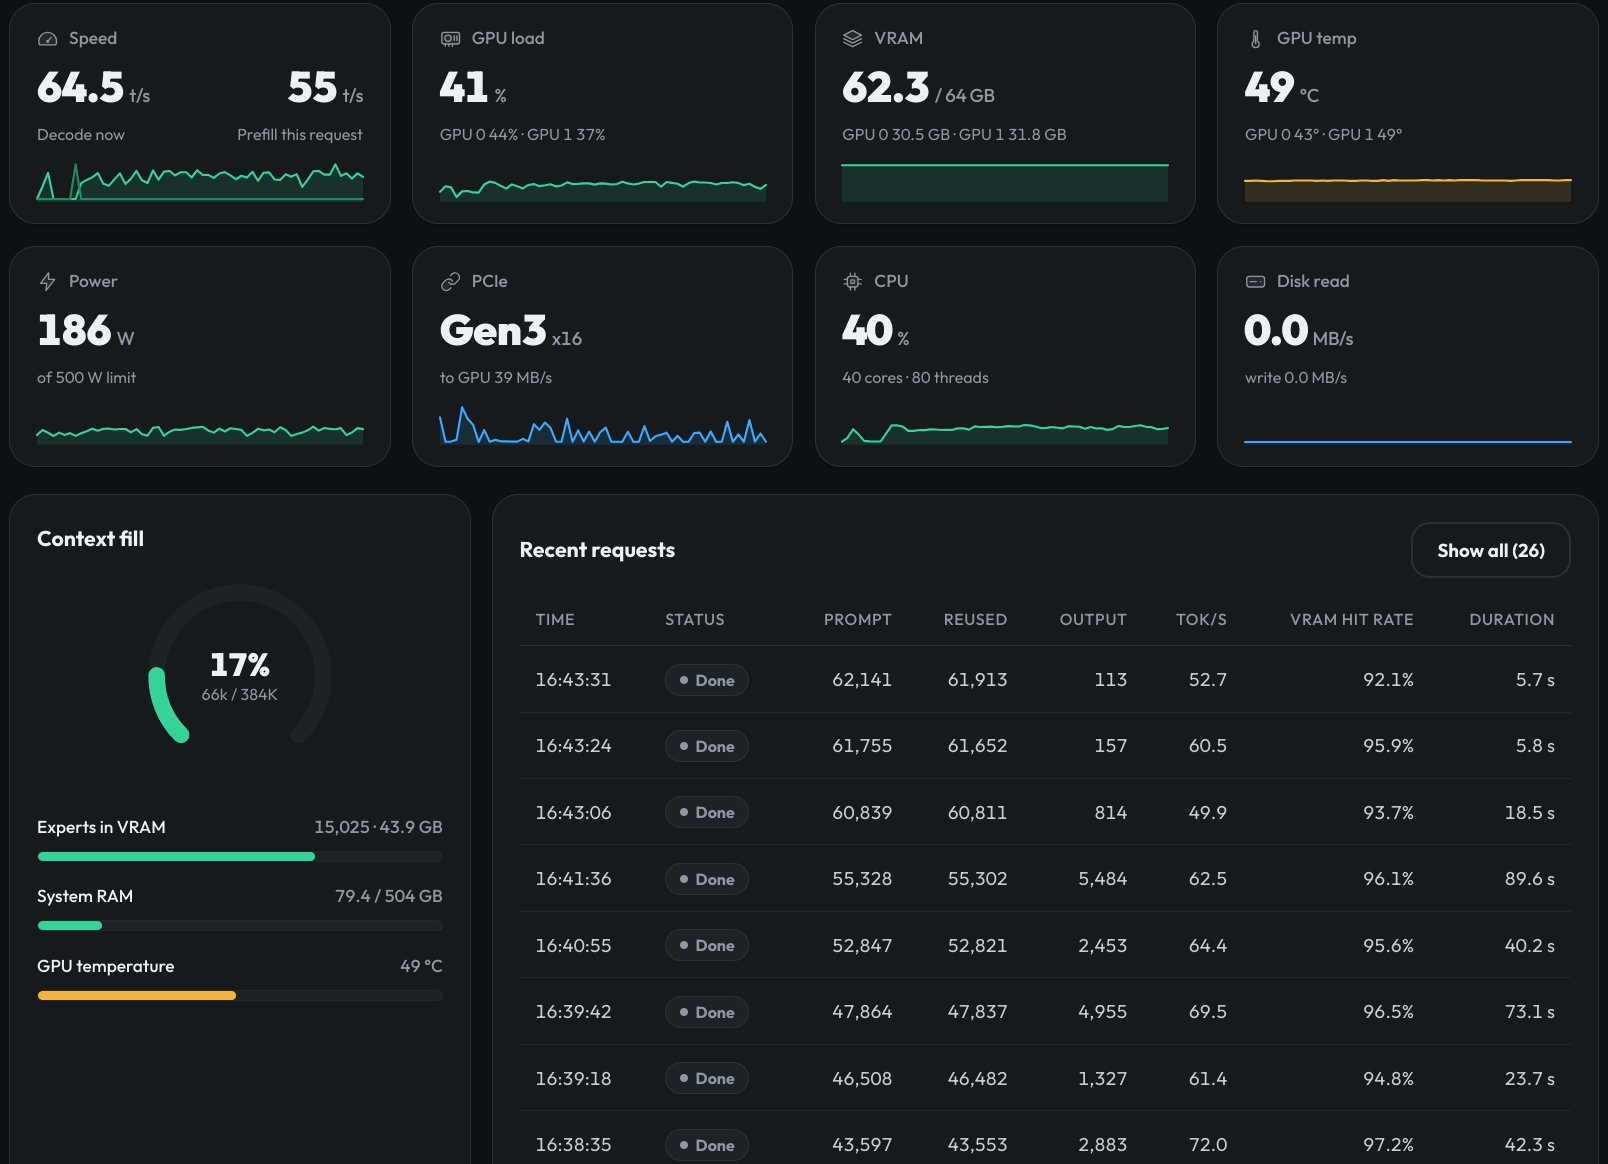
I've been using 256k all along. With strata I get about 500t/s prompt and 50-70t/s, for Q4_K_M on my 2*V100. I think 256k is minimal for medium sized project, the more, the better! #strata
I also had it working (needed patching, I used GLM 5.3 to fix), and I get very good perf, 45t/s with a 256k context. Processing at 1450t/s. That is better than what I had with llama.cpp by a LOT
We, of the Red Labrador persuasion, are supporting our kindred Black #labrador brothers!

I agree, also, prompt processing when I tried a Q4 (on 2 * V100) is abysmal -- like 30t/s which is unusable for real agentic work or code
I worked for a startup in france doing OCR with neural networks, in 1994-95. Called "Easyreader". Fun fact, the engine shipped with Apple Telecom 3.0 software on all powerbooks for years afterward.
Traditionaly we'd have a single GPU nearer the CPU tho, that's why! Nowadays we want dual slot for all the slots, these MOBO were never meant for that!
You can run it (on my 2*V100) but the perfs are a bit meh... I get ~200t/s prompt processing and ~10t/s generation, so not really usable for real work. B27 is still a lot more usable.
I've been happy with B27 Q6 as well. I'm curious what you plan to use for Flash Next; currently I have settled with B27 as it works great really. I'm on 2*V100, so can run 256k context.
Thats about the speed I get out of 2*V100 and B27 (Q6 XL) and 256k context, using plain old llama.cpp (with MTP)
