

I build things to find out how things work. Local AI on consumer GPUs. Measure, don't assume. Currently: what's actually inside quantized LLMs.
Texas
Joined June 2016
- Tweets675
- Following292
- Followers244
- Likes332


Pinned Tweet
Abliterated Qwen3.8-27B picks an answer on sensitive prompts, then keeps arguing with itself until it hits the token cap.
ThinkFix is that abliteration plus one output row edit so it closes thinking when it's ready.
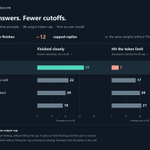
40 held out prompts, 8k cap, same weights: clean finish 22 → 33 hit the limit 17 → 5 75 min → 61 min median thinking ~3,000 → ~1,700 tokens
MATH / IFEval about flat. MTP kept, 56 tok/s vs 39 on a 3090. Q4_K_M is 16.8 GB.
huggingface.co/BoldingBuilds…

These companies that have had “AI” in their name changing to “SI” crack me up 😂 Gotta let Trump feel important I guess

I havnt played with Jev as much as I should have. I wonder if it could be used to optimize setting reasoning level for each prompt 🤔


I've been trying to fix something frustrating about Qwen reasoning models: sometimes they think right up to the output limit and never write an answer. Not a refusal, not a wrong answer. Just nothing.
I tried fixing it by editing one row of the output layer, the row that scores the "stop thinking" token. Then I put the edited row back into a normal GGUF file.
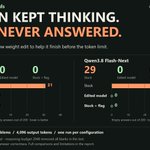
On 200 math problems with a 4,096 token limit:
• Qwen3.8 27B: 31 blank answers → 0
• Qwen3.8 Flash-Next: 29 → 0
For comparison, llama.cpp's reasoning-budget flag also reached zero and scored about the same in these tests. The difference is that the edit lives in the file, so it works in apps that don't expose a reasoning-budget setting.
There are limits, and I tried to lay them all out: a few stray tags, one seed, tested mostly on llama.cpp.
Results, downloads, and the caveats:
huggingface.co/spaces/Boldin…
Built on @Alibaba_Qwen's models and @UnslothAI's GGUF conversions. If you've worked with local reasoning models, I'd like to hear what I got wrong.

I'll be at DevDay tomorrow. If you've run into runaway thinking with local models, I'd love to hear what you've tried.
Direct model links:
Qwen3.8 27B · Q4_K_M · 16.8 GB
huggingface.co/BoldingBuilds…
Qwen3.8 Flash-Next · UD-IQ4_XS · about 94 GB
huggingface.co/BoldingBuilds…
Settings and evaluation details are in each model card.

It’s been awesome meeting everyone today who is as passionate about ai as I am! Looking forward to dev day tomorrow!
Josh Bolding retweeted

Getting ready for tomorrow’s OpenAI DevDay! 🚀
Met some awesome new people today who, just like me, love to build, experiment with AI, and have fun doing it. Great conversations, exchanging ideas, and hanging out at Fort Mason right now.
San Francisco has been amazing so far and more new connections tonight!
@OpenAI @OpenAIDevs
Can’t wait for tomorrow. 🔥
@BoldingBuilds
@_onmax
@ThatGuySam


2026 is fucking wild.
Sitting on a plane to SF for OpenAl DevDay, using the in-flight WiFi to talk to my agent, which is remotely controlling my 4x3090 rig back in Texas + a RunPod GPU to run Qwen experiments while I'm in the air.
I love this shit.
Working on something that I think will be received well regarding 3.8 27b! Should have final results by morning! Stoked!
The fix is one row of the output layer, the </think> token. 1,250 bytes.
I fit it on stock Bonsai's own reasoning so closing becomes likely once the answer is written and stays unlikely mid-thought.
The rest of v2 is the same refusal edit as v1, just stronger.
Also:
- 0% refusals, 0% over-refusal on safe prompts
- math, code, IFEval: no significant difference vs stock
- MMLU: -0.56 pts, smallest hit of the strong builds I tested (others -0.64 to -2.68)
- MTP file: 69 to 97 tok/s on a 3090
- tight budget? use reasoning_effort=medium
Thanks @Hikari_07_jp for sharing the report this week. Their build still looks great on the thinking-off chart. This is a different test.
Original report: huggingface.co/spaces/Boldin…
v2, with every table: huggingface.co/BoldingBuilds…