

Building Atlas, Rust inference engine w/ custom CUDA kernels on DGX Spark and Strix Halo | MLPerf Agentic Edge Task Force MLCommons | Ambassador @Alibaba_Qwen
Joined March 2026
- Tweets342
- Following65
- Followers867
- Likes539





Just landed TP=2 for two DGX Sparks on Qwen3.8-Flash-Next (shoutout @jmacftw!)
~2x faster tok/s vs one spark, agg decode: 193.4 tok/s at C=8 (68.6 tok/s code at C=1)
FP4-local support soon. Can't wait for qwen4!
sparkrun run @atlas/qwen3.8-flash-next-nvfp4-tp2 --cluster (x)
🤖 Made with AI

Azeez retweeted

We said we'd update SparkGLM with the new weights. Here it is running on an advance fork of Atlas (@AtlasInference)! Better, stronger, faster, more KV cache. Give it a try!
github.com/Enntity/sparkglm?…


More magic for us local AI guys!
GLM-5.3-Flash-FP4-Local combines QAD-trained NVFP4 experts with selected MXFP8 attention projections. NVIDIA reports ~166 GiB of VRAM, validated on two DGX Sparks.
A similar quant gave us 10–15% faster decode in SparkQwen, with no noticeable quality drop. Looking forward to seeing what this does for GLM. SparkGLM update incoming next.
Thanks, @NVIDIAAI!
huggingface.co/nvidia/GLM-5.…

Day-0 support for Nemotron-3.5-Super with DFlash2 is live for DGX Spark and AMD Strix Halo (Windows/Linux) 🎊
💚 sparkrun run @atlas/nemotron-3.5-super-vl-120b-a12b-nvfp4-dflash2
❤️ git clone github.com/Atlas-Inf/atlas && ./scripts/serve-nemotron-strix-linux.sh
@NVIDIAAI @AMD

Azeez retweeted
If you want to run one of the best versions of Qwen 3.8 Flash Next on 2 DGX Sparks with @NVIDIAAI NVFP4 weights, blazing fast 4043 tok/s prefill and awesome decode and concurrency on a fully native inference engine (@AtlasInference), this is an excellent option! It’s a great local workhorse and what we often run for continuous entity cognition.
GitHub.com/enntity/sparkqwen

Azeez retweeted
There are a lot of ways to run big models on DGX Sparks and the landscape is always changing. If you're considering running one of our model packages, here’s an informal FAQ 🧵
First up: what’s with the arcade cards? We think they’re cool. That's all. :D


Azeez retweeted
We told you we'd keep improving GLM 5.3 Flash on 2 DGX Sparks! We increased the KV cache size from 1.38M -> 2.36M tokens, a 71% increase, and enabled concurrent 1M token context profiles. We did it without changing a single output bit. Greedy output is also now identical whether a request runs alone or beside three others. Four concurrent ~204K-token sessions answered every cached follow-up exactly. And it all works with our long term NVMe cache offload. Receipts in the repo.
If you have 2 DGX Sparks and you want to run a near-frontier coding model that balances quality, speed, and concurrency, you should try SparkGLM. It runs the GLM 5.3 Flash NVIDIA NVFP4 weights on an advance fork of Atlas (@AtlasInference). It's now our daily driver - we love it and are improving it constantly.

Azeez retweeted
Qwen 3.8 Flash Next is another of our favorite models to run on 2 DGX Sparks. We use it all the time for cognitive processing because of its excellent speed and superb concurrency, and we have an optimized version that, like our popular SparkGLM, runs the NVIDIA NVFP4 weights on an advance fork of Atlas (@AtlasInference). If you like Q38FN you should give it a try!

Azeez retweeted
If you have 2 DGX Sparks and you want to run a near-frontier coding model that balances quality, speed, and concurrency, you should try SparkGLM. It runs the GLM 5.3 Flash NVIDIA NVFP4 weights on an advance fork of Atlas (@AtlasInference). It's now our daily driver - we love it and are improving it constantly.
Presenting GLM5.3-Flash TP=2 at breakneck speeds. The BEST local model to run on 2 DGX sparks 🔥
These speeds aren't using a special quant like EXL3 (@MiaAI_lab et al.) it's with native NVFP4. Merging in soon ⏰
Shoutout @jmacftw, try it today at:
github.com/Enntity/atlas/

We think that GLM 5.3 Flash is still the best local model you can run on 256G for real near-frontier work. That hasn't changed from a month ago when we started SparkGLM. We had one goal in mind: balance quality, speed, and staggered concurrency to make the strongest version of GLM53F for 2X DGX Spark that we could.
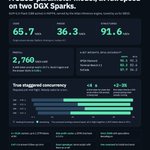
Today we can run the NVIDIA NVFP4 weights at 65.7 / 36.3 / 91.6 tok/s (code / prose / structured) single stream decode and 2760 tok/s cold prefill on a custom fork of Atlas (@AtlasInference) with generous 4 x 512K context (1.37M tokens of KV), NVME disk prefix caching (so old long prompts stay reasonably fast), and strict JSON with speculative decoding.
We think it works pretty well. We're using it every day for our production workloads and you're welcome to use it too. You can find it at github.com/Enntity/sparkglm
GLM5.3-flash TP=2 run code is in this thread too, compared against @MiaAI_lab's vLLM recipe.
@jmacftw and a few others have been working on hard this and thanks to their incredible contributions, these incredible concurrent speeds should be available in @AtlasInference soon ⚡️
A bit less than a month ago, we started SparkGLM as an effort to maximize real-world concurrent use cases for GLM 5.3 Flash on DGX Spark TP-2.
Since then, every aspect of serving the model has improved - more than doubling the throughput and cutting the wait time by almost 3x in the challenging staggered concurrency use case - all while moving to the NVIDIA NVFP4 weights and maintaining concurrency at a 512K context length. Same hardware, same model family, 28 days apart.
Now we're running on a custom fork of the @AtlasInference stack and planning a PR to add GLM 5.3 Flash support to Atlas soon.
The video shows the new serving speeds (top) vs our best VLLM version just 11 days ago (bottom) while serving 4 staggered cold 16K prompts.
We're gonna have AGI at home 😏
Given how good Qwen3.8 I can't wait for this! Let's see what @Alibaba_Qwen can cook up this time 🔥
Looking forward to adding support for this asap on DGX Spark/Strix Halo 👀

Shoutout @storagereview highlighting the hard work that went into creating the agentic edge submission!
@MLCommons sets the benchmarking standard. It's key to show that local AI capabilities are NOT vendor-locked across @AMD/@NVIDIAAI edge devices 💚❤️
storagereview.com/news/mlper…

Dflash2 support for Atlas Inference ⚡️
One-line serve in ONLY 24s ⏰
github.com/Atlas-Inf/atlas
sparkrun run @atlas/qwen3.8-27b-nvfp4-dflash2
Drafts 8 tokens ahead, verified them in parallel getting ~23.5 tok/s with no accuracy tax (87.9% BFCL) 💯
Can't trade brains for speed 🧠


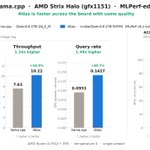
@NVIDIAAI DGX Spark GB10 results, positioned against the vLLM recipe from the product team. Soars past the best on identical models for agentic performance and matches accuracy
See here for the start script github.com/Atlas-Inf/atlas#q…
Source code is also included in the submission

Atlas is the sole cross-architecture engine running the offiicial Qwen3.6-27B-NVFP4
Raw speed is useless w dropped function calls. Combining token generation with tool-calling accuracy is the sweet spot for agentic workloads.
MLCommons sets the standard for benchmarking

Shaping the agentic inference benchmark with @NVIDIAAI was a highly necessary step for the edge hardware community 💚
With so many harnesses, benches, and eye-catching headlines, a real standard for accuracy and performance was long overdue 🫡
Submission details soon! 👀

🧵 1/
@MLPerf Inference v6.1 is here.
Record participation, new benchmarks, and substantial performance gains.
30 organizations submitted — the most ever.
Details: mlcommons.org/2026/09/mlperf…

Attention @AMD Framework Desktop windows users 🚨
Qwen3.8-27B-NVFP4 runs NATIVELY, NOT a GGUF/Vulkan shim 😯
17.3 tok/s on gfx1151, decisively HA-20 scores 84 🚀
Why try it? 3 mins to build + serve 😏
git clone github.com/Atlas-Inf/atlas.g…
.\build-amd.ps1
.\serve-amd.ps1

Hey @AMD Strix Halo users 👀
Why try it? JUST 12s to serve, Qwen3.8-27B-NVFP4 running NATIVELY on linux for gfx1151 🚤
20.6 tok/s decode 🔥 (K=4 drafts + DP4A kernels), zero BFCL accuracy loss on the ported path
git clone github.com/Atlas-Inf/atlas.g…
./build-amd.sh
./serve-amd.sh
