

Human data for frontier AI. Research and insights from Appen.
Washington, USA
Joined May 2026
- Tweets122
- Following216
- Followers1.1K
- Likes52





What are agent benchmarks actually measuring?
@SergioBrucc VP of Delivery at @AppenResearch, writes in @TheAIInnov about why benchmark performance can fall short of real-world agent performance.
More on reliability, cost, and execution in the full piece.
Link in comments.


What does it actually mean to teach an AI agent to recover?
A correction, contradiction, or tool failure can each require a very different action: edit, clarify, retry, or preserve state.
Part 2 of our recovery-data series looks at why recovery data should be tagged by both trigger + required action.
Link in the comments.


Read Part 2 of the series here: appen.com/blog/ai-agent-reco…
Congrats to the @subquadratic team on the launch of SubQ Snap! Exciting to see what they’re building in long-context decision models. 🚀

Introducing SubQ Snap, the first long-context decision model for real enterprise work.
Snap is the only decision model or LLM where compute per token stays constant as context grows.
• 384K tokens of multimodal context, 12x larger than Jev.
• 61.7 on Decision Index v0.2.1 vs Jev’s 57.9, outperforming on 13 of 16 enterprise benchmarks.
•Processes 100K tokens and returns a decision in under one second.
•$0.05/MM input tokens. Output is free.
Available today to anyone.
The first 10,000 sign-ups get 100M free input tokens.
We’ll likely hit capacity fast and will add users as we add compute. Compute offers welcome 🙂.
Latency will be variable as we tune the platform to this new model and category of users.
Model speeds are 80ms for minimal context, 250ms for 32k, 660ms for 100k, and 2.5 seconds for 384k.
Visit: subq.ai/
Thanks to everyone who joined @AppenResearch at our #COLM2026 @COLM_conf happy hour in SF! Lots of great conversations with researchers and builders about evals, LLM-as-judge, post-training data, robotics video, and multilingual AI. See you at the next one 🍻


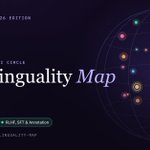
@AppenResearch is featured on AI Circle @joinaicircle’s Multilinguality Map, highlighting teams working across multilingual data, speech, evaluation and low-resource languages.
As models expand globally, dialects, code-switching and cultural context matter more than ever.
Map: ai-circle.org/multilingualit…

More on the work: appen.com/multimodal-ai
appen.com/multilingual-ai-tr…

Appen Research retweeted

Nice to see @SergioBrucc on this list

I asked people: "who have you met in the AI data and post-training space that you find most insightful?"
5 votes: Daniel Chang (@dnnssl2)
3 votes each:
- Abhijay Rana (@abhijaymrana)
- Ryan Wexler (@RyanMWexler)
- Sean Cai (@SeanZCai)
- Will Brown (@willcb)
2 votes each:
- Amy Tam (@amytam01)
- Jesse Hu (@huyouare)
- Nikhil Namburi (@nikhilvnamburi)
- Thomas Liao (@distributionat)
91 people were picked. The other 82 got 1 vote each and are in the next two posts.
People couldn't pick themselves. I didn't vote.

We get to work with @SergioBrucc every day. This checks out.
I asked people: "who have you met in the AI data and post-training space that you find most insightful?"
5 votes: Daniel Chang (@dnnssl2)
3 votes each:
- Abhijay Rana (@abhijaymrana)
- Ryan Wexler (@RyanMWexler)
- Sean Cai (@SeanZCai)
- Will Brown (@willcb)
2 votes each:
- Amy Tam (@amytam01)
- Jesse Hu (@huyouare)
- Nikhil Namburi (@nikhilvnamburi)
- Thomas Liao (@distributionat)
91 people were picked. The other 82 got 1 vote each and are in the next two posts.
People couldn't pick themselves. I didn't vote.
We’re bringing the AI research community together in San Francisco during @COLM_conf
Drinks, bites and good conversations with researchers and builders working on frontier AI.
Oct 7 · San Francisco
Join us: luma.com/yhcfodng

30 years of @AppenResearch and a lot has changed along the way.
CEO @kolln_ryan000 Ryan Kolln joined the @VantagePointNWR Vantage Point Podcast to talk about Appen’s journey and the work we’re doing today with customers around the world.
Spotify: open.spotify.com/episode/14F…
YouTube: youtube.com/watch?v=KAx8FOOO…
Appen Research retweeted
Appen is growing. We are hiring across the board to support frontier data. here's a list of roles that we are hiring for, with others coming down the pipeline. heres the apply link
- FDEs
- SPLs, with specialisation in finance, healthcare, legal
- researchers
- expert talent recruiters
appen.com/careers#lever
and dm me if interested in anything else to help push the frontier of data for superintelligence

Appen Research retweeted

@AppenResearch is going to be to the Bay next week for #COLM - thought of throwing a cool happy hour with nice people from the AI space: luma.com/yhcfodng
If you enjoy convos about RL envs, data, fine-tuning, benchmarks, just feel free to sign up. #ai #sf #bayarea
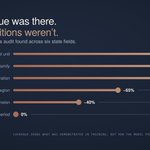
Every fiscal-period value was in the training data.
But across several thousand eligible state pairs, there were zero atomic fiscal-period changes. That’s the difference between having the values and actually demonstrating the behavior.
Part 1 of our new series looks at transition coverage and what it means for eval design.
Read the blog in the comments.


A physician dictates "hyponatremia."
The model writes "hypernatremia."
One prefix. The opposite diagnosis.
MedTerm-90 scored 7 speech-to-text engines on 90.5 hours of real dictation.
Best recall: @ElevenLabs Scribe v2, 83.35%.
Where does yours rank? We'll run it.
Full results, method, and the clinical risk review of all 6,425 near-misses: appen.com/appen-medterm-90-b…