

@WorkWeave | Prev: @causalhq, @MIT | he/him
CA
Joined August 2013
- Tweets1.3K
- Following579
- Followers597
- Likes21K



Had a great time chatting with @snowmaker about what we’re seeing in the world of engineering and why model routing for coding agents is such an interesting and important problem to solve!

Weave (W25) helps engineering teams understand whether their AI coding tools are actually making them more productive. Its models measure the work humans and agents produce and compare that output with AI spending.
The company recently raised a $13.5M Series A led by Standard Capital and launched Weave Router, which selects models for different coding tasks.
In this fireside, @WorkWeave co-founders @adambcohen93 and @AndrewChurchiII join YC's @snowmaker to share how the company evolved alongside the rapid rise of AI coding, from measuring the impact of tools like Cursor to helping teams build software factories that can work autonomously.
They explain how the best engineering teams are learning to measure the real output of their agents, spread the habits of their strongest AI users, and optimize for a future where much more software is written without a human at the keyboard.
00:00 — Optimizing AI Coding With Weave
04:02 — Getting More From Your AI Budget
08:39 — Measuring Work Beyond Lines of Code
12:30 — From AI Adoption to Optimization
16:47 — Measuring AI ROI and Coaching Engineers
20:16 — Building Software Factories
25:38 — The Future of Model Routing
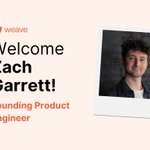
Extremely excited to welcome Zach to Weave as a Founding Product Engineer!
Not only is Zach a past founder and multiple-time founding software engineer, but he is also an Olympic silver medalist.
When he's not building awesome new functionality in Weave, he's probably either rock climbing or designing something new.
Welcome Zach!!

Everything Justin is saying here is a compelling reason why it’s *hard* to build a good router. But hard does not mean impossible! Most routers are just too naive to overcome them.
Obviously benchmarks don’t tell the full story but:


Model routers are a bad idea.
1. Intelligence is jagged.
At its core, routing treats intelligence as a smooth gradient. “Hard” problems go to “smarter” models, easy ones to “dumber” models. This is a terrible way to dish out tasks, but the problem is exacerbated by smaller models. Small models (which are typically a heavy mix in routers—after all, the goal is to save money) are necessarily more domain-specific. Hy3, for example, is incredible at 3D work but doesn’t know anything about history. Gemini 3.1 Pro tops @theo’s skate bench, but no real engineers ever used the model successfully.
2. Task difficulty is unsolved.
I don’t mean models aren’t good at this…nothing is good at this. Some tasks are just verifiably “easy,” but often even simple tasks are complicated, and complex tasks are simple. It’s the halting problem rearing its ugly head again. Old news, but like perpetual motion, it is a sweet siren that just keeps luring engineers to throw their pearls before swine.
3. It’s more expensive.
The sales pitch is you’re farming out work to cheaper models. And it’s true that cheaper models are…cheaper. But honestly, you would get better, faster inference just using the cheaper model. Sometimes it’s even cheaper to use the expensive model because routers add a whole extra layer of inference and often take longer to complete.
4. It breaks the cache.
Model cache is critical to performance and cost. It works by matching your input (the whole conversation) from start to end, chunk by chunk. As soon as there is a divergence in the content vs. what it’s seen before, it charges you the full input rate for the rest of the conversation. Moving between models as the conversation continues is constantly breaking cache. Yes, there are “cache-aware” routers, but these are entirely self-defeating.
5. It breaks chain of thought.
Models are best when they can make a plan and stick to it over several “steps.” To do this effectively, thinking data is fed back into the model on every step, so it can remember why it just took the last action and assist it in making the next right choice. These “brainwaves” are encrypted on models from major labs and do not transfer when the router decides to switch models. Not only that, but even when thinking can be preserved, models generally do not like the output of other models. This causes the models to constantly second-guess their own work. They churn through gobs of tokens just trying to understand why they previously thought this direction was a good idea.
So what is the solution? Either pay for frontier intelligence (if you need it) or use domain-specific agents. Instead of dividing work by “difficulty,” divide it by “domain,” and have an entire agent dedicated to that domain. This lets you use smaller models only for what they are provably good at.
Let me expand a bit more. To be clear our router is hyper focused on the coding agent use case. Everything I say here is specific to that. (I also think routers are a bad idea for e.g. application layer agents)
1/ Intelligence is jagged: yes it is but crucially different models have different (often complimentary) peaks and valleys. A good router can get the most out of each model and avoid its “dumb zones”
2/ Task difficulty is unsolved: true if you only see a single prompt, false if you see all the info a coding agent sees and how it evolves over time and can be smart about switching models accordingly
3/ It’s more expensive: hopefully the benchmark I posted above is enough to show this isn’t true if done well :) it is true that just blindly throwing an entire task to a small model can end up more expensive even if it ultimately does succeed, you just have to not do that!
4/ It breaks the cache: this is most of what makes building a good router a hard problem. But again hard != impossible!
5/ It breaks chain of thought: this one is the hardest to quantify but basically in our experience (training off of hundreds of thousands of sessions with all kinds of model combinations) the effect is negligible
Basically the more we work on weaveos.com/router the more excited we get because 1. it’s a really hard problem and 2. we are the only ones solving it well :)


Andrew retweeted

Introducing Weave Code Boost:
You can now combine your Claude & Codex max plans, along with top open source models in one place so you can maximize every coding agent subsidy without ever switching tools.
Andrew retweeted
Introducing Weave Code Max:
We have hyper-optimized routing and inference so you can get $50+ in usage for just $10/month. You can use our tuned open-source models in Codex, OpenCode, Pi, or Claude Code.
The most coding $10 can buy.
Andrew retweeted
Today we’re Releasing Weave Router 2.0.
Weave Router now performs better, faster and cheaper than GPT-6 Astra on Terminal-Bench and SWE-Atlas.
Andrew retweeted
Cost per output skyrocketing on average.
Some companies we're working with actually see this decreasing dramatically (we now pay around $2/hour).
Difference seems to be around using a router, prompt quality and skills set up.

Andrew retweeted

measuring the ROI of every AI dollar...
congrats to @adambcohen93 and the @WorkWeave team on the launch here...and doing what it takes to break through the algo with a launch these days 🤪

We’re announcing our $13.5M Series A led by @Standard_Cap.
AI has taken over engineering and companies are wasting millions. Weave gets you the most out of every dollar spent on tokens.
Have fun watching a man attempt to conquer his fears in the video.
Andrew retweeted

Hard to imagine a more timely product: Weave helps their customers actually measure and optimize the efficacy of token spend.
It works - try it out if you are curious to see for yourself!
We’re announcing our $13.5M Series A led by @Standard_Cap.
AI has taken over engineering and companies are wasting millions. Weave gets you the most out of every dollar spent on tokens.
Have fun watching a man attempt to conquer his fears in the video.
So excited for the next chapter of Weave!! What a joy it’s been watching it grow to this point :’)
We’re announcing our $13.5M Series A led by @Standard_Cap.
AI has taken over engineering and companies are wasting millions. Weave gets you the most out of every dollar spent on tokens.
Have fun watching a man attempt to conquer his fears in the video.
At @workweave, our engineering team is in the top 1% by code output. One way we keep this up: the shipper of the month trophy
Code output is Weave's metric for how much someone ships. Whoever has the most code output in a month gets the trophy: a small model ship that sits on your desk for the month you win it.
It works because of who’s competing for it. We screen for competitive people in interviews on purpose, so we know that fostering some friendly competition will work.
But also, the trophy isn't actually the goal. Everyone understands what really matters: building the best company possible. The trophy just provides a bit more fun along the way :)
@syriansigma has held the trophy for a couple months running now, but he's facing some stiff competition this month - we'll see if he can hold on again!
(ignore the questionable handwriting and random right-to-left order lol)

The conventional assumption in engineering hiring is that juniors are a long-term bet, and it will take two years before they're really contributing. At Weave, we've seen something very different, and our own data backs it up: four to six weeks to become an extremely effective contributor.
We hire junior engineers who have good raw skills but not necessarily a ton of experience, and from our own internal data, it takes about four weeks (six weeks max) for an intelligent and hardworking but inexperienced engineer to become an extremely effective contributor.
I had a hypothesis going in that this was possible, and the data has validated what we've been doing.
I don’t want to overstate it and claim we’ve figured out some magic formula. It takes a lot of work to find someone who can grow so quickly! But the gap between the conventional two-year assumption and our four-to-six-week observation is large enough that I think a lot of engineering leaders are leaving talent on the table by ruling out junior candidates entirely. The idea that you have to subsidize a junior for years before they produce real value doesn’t match what we’re seeing.
If you're a startup thinking about your next engineering hire and defaulting to "we can only afford to hire seniors," it might be worth questioning that assumption.
In 2024, before @WorkWeave became Weave, it was an AI feedback tool that would try to help engineers be better at their jobs. We applied to YC with it and got an interview, but didn't get in. Pivoting changed our trajectory.
Adam and I spent months pushing on the AI feedback idea. July, August, September, into October. It was quite rough, very mentally difficult.
We weren't closing any deals. The product wasn't good. We were trying to raise money and it wasn't working. I was waking up every day feeling like a bit of a failure. Nothing about the business was clicking.
Then we had a realization that should have been obvious sooner. We would talk to three different people, and they would have three different ideas of what we do. We needed to build something that was genuinely compelling, yes, but also very easy to explain.
So we sat down and gave ourselves a simple task: come up with every idea we can think of that we can explain in just one sentence. That's how we settled on quantifying engineering productivity, which was the first seed of what Weave is today. We built our first model and the product around it, and applied to YC again.
This time, we launched before the interview and got some actual traction. We pointed to that in the interview, and we got in.
It ended up being pretty good timing - the month we got into YC (and finally raised money) was also the month my savings were going to run out. No idea what would have happened if we hadn't got in!

The single most important thing we look for in engineering candidates is their ability to solve problems they've never seen before and don't know what to do with. Everything else, including writing the actual code, AI can help with.
Engineering interviews used to test code syntax, things like whether you could write valid code by hand or knew the right methods. Our interview doesn't. All we care about is problem solving, in a programming context, without requiring strict programming knowledge.
You need to know basic concepts, like what data structures and APIs are. Beyond that, no experience required. The interview itself is unusual, nothing like a classic Google coding problem. It skips anything you can study for by grinding LeetCode and tests raw problem solving against something you've never seen before.
What we want is someone who'd be fully capable of understanding a system and contributing at a high level without AI, and does even more with it. Problem solving and systems thinking are all that matters.
When you see AI tool spend as a governance problem, it becomes a policy exercise. You end up putting handcuffs on engineers. When you see it as an allocation problem, you end up investing where you're getting real returns. Same budget, very different outcomes.
Microsoft reportedly pulled most Claude Code licenses and consolidated engineers onto GitHub Copilot. The stated logic was to consolidate spend where they could govern it.
I get the instinct - AI tool costs are growing, they're distributed across teams, and finance leaders want control. Governance feels responsible.
However, if you see the entire thing as a governance problem, it becomes a policy exercise where you're trying to put handcuffs on engineers. You lose the opportunity to get outsized returns from allocating effectively toward the places where you're actually getting huge ROI.
The better frame is allocation. How are you ensuring that the money going toward AI is producing the maximum possible return? That question leads to a completely different set of decisions than "how do we control this spend?"
For us at Weave, it makes zero sense to have any caps. We don't want to add any friction whatsoever for our engineers. We get notified if somebody is going way over, and we can look into it. Most of the time it's because they're doing good work. When it's actually a problem, we can address it together.
With governance, you cap both your downside and your upside. With allocation, you discover where AI spend produces 10x returns and lean into it.
CTOs can feel AI making their team faster, while CFOs just see a bill that keeps climbing. When that gap doesn't close, the bill (and the upside) gets capped.
Where I see this going wrong at a lot of companies is from the CFO or COO’s perspective. The bill keeps growing every quarter and there's no return they can point to. Without a clear answer, capping the budget is the obvious next move.
Uber's COO made comments along these lines publicly a few months back, claiming that token spend was hard to justify when shipping didn't seem any faster. Uber is actually pretty far along on AI adoption overall, and from what I've heard about how their engineering team talks about it internally, that wasn't their experience at all. Two parts of the same company were reading completely different signals off the same spend.
I think the CTO's job in a situation like this is to communicate what the actual ROI is in human equivalent terms. If we didn't have AI, here's what we would be spending on humans to get the same outcomes we're getting now. That gives them something to benchmark that spend against.
That's exactly how we orient this at Weave for our customers. We take what AI has produced and convert it into the human-equivalent cost of getting there. Once the CFO can see that in concrete terms, the whole budget discussion gets a lot easier!