

Pre-training LLMs @OVHaiLLM in Paris
Montpellier, France
Joined January 2020
- Tweets648
- Following340
- Followers1.3K
- Likes59.3K



Pinned Tweet
muP works great for Mamba !
Zero-shot transfered the learning rate from a 172k model to a 105 model.
Now part of mamba.py 👇🧵

Come join us to work on very interesting research & engineering tasks around LLMs !

We're looking for experienced researchers and engineers to work on and train our future large language models. We are hiring for multiple positions in the following roles:
- A research-engineer with experience in advanced data preparation techniques on trillions of tokens
- A research-engineer with experience designing hybrid and linear attention architectures
- A research-engineer with experience in advanced agentic RL techniques for fine-tuning LLMs on complex, long-horizon tasks
If you have a few years of industry or academic experience (PhD or postdoc), you can apply here:
llm.ovhai.com/r-002-senior-r…
If you're interested in working in the field but have less experience, you can apply for our junior researcher position:
llm.ovhai.com/r-001-research…
Alexandre TL retweeted

Just finished reading The Little Book of RL by @AlexandreTL2.
Super clear, compressed walkthrough of the underlying math paired alongside minimal code. Great entry point for building core RL intuitions!
Excited to dive into my own RL experiments next!

The book, along with its supplementary material, is available for free here: github.com/alxndrTL/little-b…
Or you can buy a paperback copy on Amazon by looking up its name (sold at cost)
It is a much revised version of a video series I gave in 2020 here: youtube.com/@alexandretl/cou…

So I have been busy these last few months! Happy to present : The Little Book of Reinforcement Learning

The book, along with its supplementary material, is available for free here: github.com/alxndrTL/little-b…
Or you can buy a paperback copy on Amazon by looking up its name (sold at cost)
It is a much revised version of a video series I gave in 2020 here: youtube.com/@alexandretl/cou…
Of course, all the credits goes to @francoisfleuret for this format (The Little Book of Deep Learning fleuret.org/francois/lbdl.ht…), which I adapted from deep learning to reinforcement learning!
Alexandre TL retweeted

We’ve been lucky enough to test Mamba-3 ahead of the curve. 🧪
Here is how it integrates into Hybrid Models (Spoiler: it unlocks Muon for SSMs for the first time). 🧵

The newest model in the Mamba series is finally here 🐍
Hybrid models have become increasingly popular, raising the importance of designing the next generation of linear models.
We've introduced several SSM-centric ideas to significantly increase Mamba-2's modeling capabilities without compromising on speed. The resulting Mamba-3 model has noticeable performance gains over the most popular previous linear models (such as Mamba-2 and Gated DeltaNet) at all sizes.
This is the first Mamba that was student led: all credit to @aakash_lahoti @kevinyli_ @_berlinchen @caitWW9, and of course @tri_dao!

This is basically Hyperball + GeoNorm

Interesting optimizer that projects the gradient onto a tangent n-dimensional ball on the loss landscape. Unfortunately, the experiments are fairly basic, but i quite like the idea.
🔗arxiv.org/pdf/2603.06651


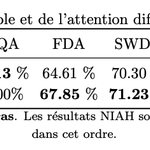
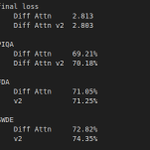
Well, works really great compared to Diff Attn v1! 0.01 loss gap with a faster model


This is the best I got for Muon on a hybrid architecture compared to AdamW. Anyone knows what could be happening here ?

if WD, its value is 1e-4, LR 0.6 (it's using muP with indep WD hence the small WD and large LR.
"translated" to SP, that would be LR=5e-4 and WD=6e-3
RoPE vs NoPE in hybrid linear attention models like Kimi Linear / Qwen3Next is tricky
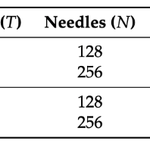
for example, when using NoPE, we found that slowly expanding the window size of the attention layers during training (64->4k) greatly helps convergence:


You see:
- a new arch that is better and faster than full attention verified with Kimi-style solidness.
I see:
- Starting with inferior performance even on short contexts. Nothing works and nobody knows why.
- Tweaking every possible hyper-parameter to grasp what is wrong.
- Trying to find the efficient chunkwise parallelizable form to squeeze juice out of the GPU
- RoPE or NoPE, a question haunting for nights.
- Fighting buggy implementation that causes one of the long-context benchmarks drops ~20 pts.
- RL diverging. Aligning training-inference numerics.
- Dedicated efforts to make sure comparisons are solid and fair.
- Going back-and-forth in a pool of adversarial gate-keeping tests, and finally it survives.
Great teamwork!
It kind of corroborates the results of arxiv.org/abs/2509.24552 which trains using a stochastic context size (instead of a growing one as we do, from 64 to 4k). the intuition is to force the attention layers to use the linear attention memory
More info and surprising results of our arch @DragonLLM here : dragonllm.substack.com/p/ins…