

Agent Memory Leaderboard Official. First open championship for agent memory systems. Neutral · Reproducible · Fair. mailto: contactus@agentmemoryleaderboard.ai
Joined July 2026
- Tweets211
- Following169
- Followers223
- Likes222




Pinned Tweet
🏆 AML Cycle 2 results are live! 💥
• 1M+ cross-platform impressions
• 10M+ cumulative website clicks
• 402 task submissions
• Three tracks: text, code and multimodal memory
This cycle brought together teams from across the global AI community, including teams from Alibaba Cloud DMS, Shopee, OPPO, KT and OceanBase—alongside university researchers, memory startups and independent developers.
Explore the full results: agentmemoryleaderboard.ai
Highlights and evaluation details below 🧵


🏆 MemoraX placed #1 in Text, Code, and Multimodal Memory on both the AML Cycle 2 Closed-Source and Commercial Products leaderboards.
It also retained #1 in Text and Code Memory Commercial Products for a second consecutive cycle.
Congratulations to the team!

Three tracks. Three #1st . One memory engine. 🏆
MemoraX just took the top spot in Text, Code, and Multimodal Memory at AML Cycle 2, ranking #1 across both the Closed-Source and Commercial Products leaderboards.
Here's the scorecard:
Text Memory — 69.26
Code Memory — 68.00
Multimodal Memory — 53.68
Not our first time at the top:
🥇 Second consecutive #1 in Text Memory
🥇 Second consecutive #1 in Code Memory
🥇 First-ever #1 in the newly introduced Multimodal Memory track
For us, agent memory is about more than expanding context windows. It's about turning past interactions into reusable experience.
Our approach centers on trained memory models that dynamically select, update, and retrieve information—helping AI agents maintain relevant context and turn previous experience into more effective future actions.
A huge thank you to @AgentMemoryL, CSIG, and the entire evaluation team for their work, and to all participating teams for pushing the field forward.
Keep building.
github.com/memorax-ai/memora…

3
82
A closer look at AML Cycle 2 from @omarsar0: capability breakdowns reveal differences that overall rankings can hide. Personalization & Care stands out as an area for further investigation.
Thanks for the thoughtful analysis—we’ll share more detailed breakdowns and cases soon!

I like how this measures different aspects of agent memory capabilities.
This is part of the @AgentMemoryL Cycle 2 results.
On the closed-source text board, the top 10 systems score between 70 and 78 on Memory Governance.
Personalization & Care is the lowest-scoring category for all ten, with scores between 41 and 55.

3
169
Mnemon 以 61.65分位列 AML 第二期文本记忆闭源方法榜第6名。团队还分享了参评配置、API 开销与检索耗时,并开放评测 demo,为开发者理解效果、成本和响应时间之间的取舍提供了参考。
感谢参与和透明分享,期待后续迭代!👏

第二期 Agent Memory Leaderboard 正式榜单发布了。在文本记忆商业产品榜中,Mnemon 在 125 个参赛产品里获得了第 6 名的成绩,感谢 @AgentMemoryL 的组织。
Mnemon 本身是 Apache-2.0 协议的开源项目。不过,由于我们新版本实现中使用了 @typesafeai 的 Jev 决策模型,因此无法符合开源方法榜的模型要求,也借这个机会,以开源项目的身份挑战了竞争更激烈的商业产品榜。
本次评测中,我们使用的模型是 DeepSeek-v4.1-Flash(未开启 thinking)以及 Jev 0.1.13。这次评测相关的模型 API 支出折合约 50 美元,Mnemon 单次检索请求的中位耗时约 4.7 秒。作答和评分由 AML 统一完成。我们的目标是提供高效与实用的记忆能力,本次评测也是我们的一次尝试。
目前,Mnemon 仓库已经开源关于 AML 评测的 demo 版本,并且正在整理正式版,近期会进行发布,并且以合适的形态进入到 dsh-mnemon 插件中,希望能带来让用户满意使用体验。
Keep building.
github.com/mnemon-dev/mnemon
github.com/omdsh-dev/dsh-mne…

4
182
Khipu took 1st place in the AML Cycle 2 Multimodal Open-Source leaderboard with 43.26 points! 🥇
Congratulations to @Lv999APTITUDE, and thank you for contributing to the new track. Excited to see what comes next for the project!

Khipu: memory for AI agents. Stores every message verbatim, never rewrites it; photos become text for search and come back as evidence.
1st in Multimodal · Open-source Methods, Agent Memory Challenge Cycle 2.
@AgentMemoryL #AgentMemoryLeaderboard
github.com/Lv999APTITUDE/khi…


3
165
Congratulations to @gedolabs on Gedo Memory’s 3rd-place finish in the AML Cycle 2 Text Memory Commercial Products leaderboard! 🥉
Great to see the team sharing lessons from the evaluation and putting them into practice. Looking forward to what comes next👏

Gedo Memory(gedo.ai) placed 3rd on the AML Cycle 2 Commercial Products leaderboard (Text Memory), and 5th among closed-source methods. I'm grateful to our team, and to the AML and CSIG organizers.
A few notes on what this meant for us.
Why we entered
At Gedo we're building a personal AI that remembers you over months and years. The memory layer is the product: what it keeps, what it lets go, and what it never says out loud. For a long time we measured it only on our own tests. AML gave us something we couldn't build ourselves: an independent benchmark where the organizers fix the answering model and the judge, so the only thing that differs between systems is memory.
What the run looked like
We decided to enter in late October and had our system online a few days before the deadline. The full suite then ran for about 72 hours. It surfaced problems our own tests never had: shards running out of memory under sustained load, idle connections being dropped, a write path that needed to survive a restart. All of them were on our side, and fixing them made the system sturdier.
What the scores told us
We did best on explicit fact recall, multi-hop reasoning, and time and event order. Relative to the field, our weakest area was epistemic safety and privacy. That's the one I care about most. A personal agent that recalls everything but doesn't know what to keep to itself isn't one you'd trust with your life. Since the competition, that's where our work has gone: forgetting, and what the agent chooses to disclose.
Agent memory is still early, and shared, independent benchmarks are how the field gets better. Thank you, @AgentMemoryL.


1
133
Open-source leaders:
• Text: Resurface — 61.22 points
• Code: InsightMem — 63.33 points
• Multimodal: Khipu — 43.26 points
Each track features open-source, closed-source and commercial product rankings.
Tasks and scoring differ across tracks, so scores should be interpreted within each track.
1
4
106
Open-source leaders:
• Text: Resurface — 61.22 points
• Code: InsightMem — 63.33 points
• Multimodal: Khipu — 43.26 points
Each track features open-source, closed-source and commercial product rankings.
Tasks and scoring differ across tracks, so scores should be interpreted within each track.
1
23
⏳ 3 DAYS TO GO.
The AML Cycle 2 leaderboard is almost here.
Three tracks.
Two divisions.
One unified evaluation framework.
Textual Memory. Coding Memory. Multimodal Memory.
On November 19, we'll reveal the official results of the Agent Memory Leaderboard Cycle 2.
Which memory systems will stand out?
Stay tuned.
One Benchmark. Real Memory.
🔗 agentmemoryleaderboard.ai/co…

How do we evaluate long-term memory in AI agents?
Storing information is one thing. Remembering the right information, adapting to updates, resolving conflicts, and applying past experience to new tasks is another.
The 2nd Agent Memory Leaderboard (AML) aims to provide a systematic evaluation of these capabilities.
This edition has received submissions from 312 memory systems across three evaluation tracks:
🧠 Text Memory
6,000+ evaluation instances, including a new Streaming Memory evaluation that tests how systems handle continuously evolving information.
💻 Code Memory
300 evaluation units across 150 base tasks, testing the use of relevant and noisy memory in bug fixing and feature development.
🌐 Multimodal Memory
Nearly 5,000 evaluation instances, focusing on image-text memory, cross-modal retrieval, and evidence use.
The full evaluation and result verification process has been completed.
The full rankings, track-level performance analysis, and selected technical approaches will be published on November 19, 2026.
We hope AML can help make long-term agent memory capabilities more measurable and comparable.
Explore AML: [agentmemories.ai/home]

3
5
246
Beyond Information Storage
What makes a memory system useful for an AI agent?
It's not just about retrieving stored information.
A capable system should handle changing facts, distinguish outdated information, resolve conflicts, and retrieve relevant experience when needed.
AML's Text Memory track includes a new Streaming Memory evaluation to examine how systems handle information updates and changing states over time.
1
1
141
A total of 312 memory systems have been submitted for evaluation in this edition.
The full evaluation and result verification are now complete.
On November 19, 2026, AML will publish the full rankings, track-level performance analysis, and selected technical approaches.
We welcome researchers and developers to explore the results and share their feedback.
agentmemories.ai/home
56
A customer explains a business rule once. Will an AI agent still remember it when making a decision several rounds later?
FDE-Bench highlights a subtle warehouse challenge: two batches of the same product may still count as mixed goods under the warehouse's rules.
An agent that groups only by product ID could get the entire plan wrong.
Remembering a rule isn't enough. The agent must retrieve and apply it when the decision actually depends on it.
This is exactly the kind of capability we evaluate in the Textual Memory track of Agent Memory Leaderboard (AML).
AML Cycle 2 results are expected in mid-November. Stay tuned to see how participating memory systems perform!
Research: arxiv.org/html/2610.14539v3#…
AML: github.com/AML-memory/agent-…

6
138
Coding agents are getting faster. But speed is only one part of maintaining a real project.
The harder question: after fixing a bug today, can an agent use that experience when a related task appears next week?
Zed’s Agent Metrics makes responsiveness visible. Project memory asks what happens over time.

1
2
125
Imagine a team fixed a stale-page bug by adding cache invalidation after data updates.
Later, an agent builds a batch-update feature.
That past fix should be a useful clue — not a patch to copy blindly. The agent still needs to check the current code, version, and constraints.
1
101
That is the question behind Coding Memory evaluation:
Can a system retrieve, filter, and reuse historical engineering experience under both relevant and noisy history?
At AML, Coding Memory evaluates this across bug-fix and feature tasks. Finding a similar record is only the start; using it correctly is what changes the task outcome.
agentmemoryleaderboard.ai/
19
Finding the right memory doesn't guarantee the right answer.
An October 8 analysis by Engram tested 6 memory systems on 1,536 LoCoMo questions, evaluating retrieval and answer accuracy separately.
The takeaway: retrieval success ≠ answer correctness.
Report: engram.tools/en/insights/ai-…

4
4
191
To understand where failures happen, examine the full pipeline:
Add — Was the update stored?
Search — Was the right evidence retrieved?
Answer — Was the evidence used correctly?
Eval — Was the answer judged consistently?
A final score alone cannot tell us where the failure occurred.
1
27
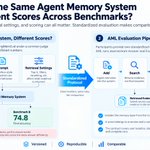
How does AML evaluate Textual Memory?
Participants provide two standardized interfaces: Add & Search.
AML controls downstream Answer and Eval under a shared protocol. This isolates the memory layer from the LLM.
Explore AML: agentmemoryleaderboard.ai/do…
18