
Working on learning @thinkymachines | prev: @cognition @MIT_CSAIL
Joined September 2022
- Tweets83
- Following639
- Followers2.7K
- Likes1.9K


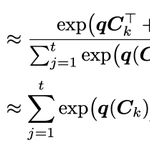


Pinned Tweet
We introduce a new approach for fast and high-quality context compaction in latent space.
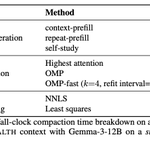
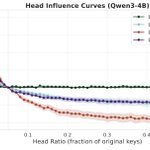
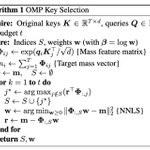
Attention Matching (AM) achieves 50× compaction in seconds with little performance loss, substantially outperforming summarization and other baselines.

Adam Zweiger retweeted

Releasing weights indiscriminately isn't safe. Neither is keeping capable models inside a few labs.
We think there's a path between them. We haven't mapped all of it. Our new post covers the part we can see: how we assessed Inkling, and why access should widen in stages.
thinkingmachines.ai/blog/a-s…

Adam Zweiger retweeted
Today, we are releasing Inkling-Small.
Inkling-Small achieves comparable performance to Inkling at a quarter of its size. It features 276B total parameters, 12B active. We are making the full weights available.
thinkingmachines.ai/news/ink…
Fine-tune it on Tinker today, or chat with it in text, image, and audio on Tinker Playground.

Excited to share that I recently joined @thinkymachines after graduating from @MIT. I have an inkling this will be the next great frontier lab, and a different kind of one. Proud to be working alongside such a fun and talented team.

We're building AI that people and organizations can shape and make their own. AI should extend our will and judgment instead of neglecting it; enabling that is the technical challenge we are working to solve.
thinkingmachines.ai/blog/the…

Adam Zweiger retweeted

LLM training is built on fast MatMuls. But many surrounding ops still run as memory-bound kernels.
CODA reparameterizes them to hide in the matmul’s shadow, fused into its epilogue before results leave the chip.
Bonus: LLMs can write fast CODA kernels too (approaching SoLs).


The biggest reduction in KV cache memory comes not from quantization or MLA, but from latent compaction, along the sequence dimension.
More strong results coming soon with Attention Matching.

New coding model from @cognition! I helped train it during my internship there. The team is very strong and this is just the beginning!

We are sharing an early preview of our ongoing SWE-1.6 training run.
It significantly improves upon SWE-1.5 while being post-trained on the same pre-trained model - and it runs equally as fast at 950 tok/s. On SWE-Bench Pro it exceeds top open-source models.
The preview model still exhibits some undesirable behaviors like overthinking and excessive self-verification, which we aim to improve. We are rolling out early access to a small subset of users in Windsurf.

Fun fact: Back in 2014, Demis had a red line condition for any potential acquisition of DeepMind: "no technology coming out of DeepMind will be used for military or intelligence purposes."
Google accepting this more eagerly was part of why Demis chose them over Facebook. This red line is even broader than Dario's (no mass surveillance or fully autonomous weapons), though it was quietly removed by Google 1 year ago.


Future Work:
- Integrating latent compaction into inference engines (e.g. RadixAttention, varlen storage, disaggregated compaction)
- Online compaction — compacting mid-trajectory repeatedly to support arbitrarily long sequences. We show initial results but more work remains.
This was joint work with amazing collaborators: @shinfxh @HanGuo97 @yoonrkim
Paper: arxiv.org/abs/2602.16284
Code: github.com/adamzweiger/compa…
Nice work on GAN-style training with a generator and discriminator, both trained with RL. This might be the path to improvement in domains without good verifiers like creative writing.

