

Continuous AI Benchmarking, Drift Detection & Smart Model Routing
Europe
Joined September 2025
- Tweets1K
- Following53
- Followers132
- Likes1.3K





AI Stupid Level now works with OpenClaw, Hermes Agent, n8n, Claude, Cursor & VS Code (MCP) + new TypeScript, Python & Vercel AI SDKs.
Smart Router picks the best model for each task using your keys. Zero token markup. 1,000 free routes/mo.
What should we integrate next?
DeepSeek experienced a major API outage today.
ASL detected the disruption, flagged it on our platform, and notified users. Benchmarking resumed automatically after recovery.
Our Smart Router can mitigate these disruptions through automatic model failover.
asl.info

AIStupidlevel retweeted

10 YEARS. ONE EXTRAORDINARY GLOBAL COMMUNITY. 💜
World Summit AI 2026 is officially a wrap.
And none of it happens without the people behind it.
To every speaker and moderator who challenged the room.
To every sponsor and partner who helped us bring this milestone edition to life.
To every startup and exhibitor who showed us what's being built next.
To our production teams, crew and everyone working behind the scenes.
And, most importantly, to every single attendee who travelled from across the world to join us in Amsterdam...
THANK YOU.
For two extraordinary days, you filled Taets with ideas, questions, debate, technology, connections and an incredible amount of energy.
Ten years ago, World Summit AI began with an ambition to bring the global AI community together.
Ten years later, that community is stronger than ever.
This one belonged to all of you. 💜

Benchmark better. Route smarter.
Cut your AI API costs by up to 70% without compromising model performance.
Real-time benchmarks. Intelligent routing.
Better AI for less.
asl.info
AIStupidlevel retweeted

Claude Opus 5.5 is a talker. GPT-6 Sol is the introvert.
On the 3 reasoning tasks both completed, they scored exactly the same: 92, 100, 96.
But Opus used 22,205 words to get there.
Sol used 3,806.
Almost 6x less output for the same scores, and roughly $0.24 vs $4.44 at list prices.
But it’s not as simple as “shorter is better”.
Opus also solved a coding task Sol failed in all 3 sweeps, plus a full-stack tool-use task Sol didn’t finish.
So far, Sol looks much more efficient when both models know the answer. Opus talks a lot more, but sometimes that extra effort seems to help at the edge.
One day of data, not a conclusion.
But definitely something worth watching.
asl.info
GPT-6 Astra Sol, Luna and Terra are now available on AI Stupid Level for continuous benchmarking and drift detection.
You’ll see all three listed immediately, while scores will begin populating as the next benchmark passes run.
Claude Opus 5.5 has been added to AiStupidLevel and is now included in drift detection
You’ll see it listed immediately, but scores won’t populate until the next benchmark pass begins. Once that run kicks off, results will update automatically alongside other models.
We check every AI model for drift every hour.
Coding, reasoning, tool-calling | benchmarked continuously, then routed to whichever model is best right now, on your own API key.
asl.info
AI Stupid Level is now even easier to access.
You can find us at asl.info - a shorter, simpler way to reach the platform.
aistupidlevel.info is still fully available as well, so both domains will continue to work.
Same platform. Easier address.
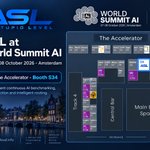
AI Stupid Level is coming to @WorldSummitAI Amsterdam 2026.
You’ll find us in The Accelerator, Booth S34, right next to the Main Expo Space on 7-8 October.
We’ll be showcasing how ASL continuously benchmarks leading AI models, detects performance drift, and uses real-world performance data to help route workloads more intelligently.
If you’re attending, come say hello.
#WorldSummitAI #ArtificialIntelligence #AI #AIEvaluation #Benchmarking #Amsterdam
🤖 Made with AI

See which AI model is performing best right now.
aistupidlevel.info
🤖 Made with AI
We’re excited to welcome Alexandra Chirilă to AI Stupid Level.
Alexandra brings a PhD background in philosophy, epistemology and AI evaluation, with expertise in Assurance 2.0 and safety-case review, and she will play an important role in helping us design what we believe can become the strongest continuous reasoning benchmark framework in the industry.
Building great reasoning benchmarks is not only about writing harder questions. It is about understanding what a result actually proves, whether an evaluation is measuring the capability we think it is measuring, how robust the evidence is, and how confidently we can draw conclusions from changes in model performance over time.
At ASL, our goal is to move beyond static benchmark snapshots and continuously measure how reasoning capabilities evolve, degrade, recover and change across model versions. Alexandra will help strengthen the epistemological foundations behind those evaluations, challenge assumptions in how we interpret evidence, and improve the way we justify conclusions about model reliability and capability.
We want ASL’s reasoning benchmarks to become the kind of benchmarks that researchers, companies and eventually institutions can trust when the question is not simply “Which model scored higher today?”, but “Can we actually rely on this model to reason consistently over time?”
That is the standard we are building toward.
Welcome to ASL, Alexandra.
🤖 Made with AI

AI is becoming infrastructure.
And once your company depends on AI every day, it is no longer enough to know that a model performed well when you tested it three months ago.
Imagine running a hospital, factory, or data center and saying: "We tested the electricity before launch. It worked perfectly."
That would be absurd.
You continuously monitor the power, you have backup systems ready, and if one source fails, you switch to another before the business stops.
AI should work the same way.
The model that performed best during your testing should still perform that way today. If its quality degrades, you should know. If latency suddenly increases, you should know. If a provider has an outage, your application should not go down with it. And if another model is performing better for the same task, your infrastructure should be able to react.
That is what AI Stupid Level is designed for.
ASL continuously measures AI models in real-world conditions, detects performance changes and degradation, monitors reliability, and gives companies the intelligence needed to route workloads toward the best available model and provider.
Because when AI sits inside customer support, search, coding tools, financial workflows, automation, agents, or core product features, "the API is probably fine" is not an acceptable reliability strategy.
A single AI provider should not become a single point of failure for your company.
We believe every serious company building AI into its products will eventually need a reliability layer around that AI.
AI Stupid Level is building that layer.
🤖 Made with AI

We examine why continuous model monitoring is becoming essential as AI moves deeper into production environments, and why a healthy API does not always mean a healthy model.
Read the full article below.
aistupidlevel.substack.com/p…
🤖 Made with AI

AI models are getting better at recognizing when they are being benchmarked.
We’ve seen enough signals of evaluation awareness at AI Stupid Level that we’ve made a decision: our full benchmarking methodology and repository are now private.
When the exact tasks, prompt structures, evaluation patterns and detection logic are public, you risk measuring how well a model recognizes the test instead of how well it actually performs.
We already rotate tasks, evaluation structures and fresh API keys to reduce benchmark recognition. Keeping the full methodology public was becoming another variable we could no longer ignore.
Transparency matters, but benchmark integrity matters too.
Our goal remains the same: fair continuous benchmarking and reliable drift detection across AI models.
At some point, benchmarking AI becomes a cat-and-mouse game.
We intend to stay ahead.
GPT 6 Astra has been added to the AIStupidLevel benchmark and is now included in drift detection.
You’ll see it listed immediately, but scores won’t populate until the next benchmark pass begins. Once that run kicks off, results will update automatically alongside the other models.
Claude Fable 5.1 has been added to AiStupidLevel and is now included in drift detection
You’ll see it listed immediately, but scores won’t populate until the next benchmark pass begins. Once that run kicks off, results will update automatically alongside other models.
167K+ benchmark runs.
88M+ tokens processed.
130K+ users.
AI models change constantly. ASL tracks how they actually perform over time.
Continuous benchmarking. Drift detection. Smarter routing.
The intelligence layer for a moving AI market.
🤖 Made with AI
