

AI consultant for banks & fintech. Takes on what shipped and what works in SEA. Curated news + Morning Notes on the site. Building https://xitter.cf/t.co/8T6ku41P7s
Joined October 2025
- Tweets2.5K
- Following379
- Followers562
- Likes98



Marc | AI in finance retweeted

Introducing The Cheeky Pint Benchmark.
We made our intern watch every episode of Cheeky Pint to bring you this breakdown of pints drank by guests to the nearest sixth.
Congratulations to @elonmusk who is currently in the lead with three full pints of Guinness.

Marc | AI in finance retweeted

Energy capacity = economic capacity, in one chart
There are no low electricity, rich countries


"Energy Capacity = Economic Capacity"
Former Intel CEO Pat Gelsinger on why America's power grid is the ceiling on growth:
"We went through 10 to 15 years where essentially I was taking coal offline at the rate I was adding renewables, and essentially the nation was flatlined in terms of overall energy capacity."
"So essentially our economic capacity as a nation, flat for fifteen years."
"Even with that, we've gone to maybe increasing our national energy capacity 4% per year. Going from essentially zero to one."
"Nuclear as base load is a fabulous thing that we want to go build more of. Unfortunately all of our renewables have deep dependencies in China."
"Energy capacity somewhat dampens how euphoric we can get on AI. Why build a new data center and buy the million GPUs if I can't power them?"
@PGelsinger @RaghuRaghuram @appenz

Marc | AI in finance retweeted

Marc | AI in finance retweeted

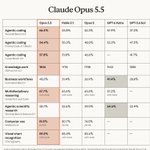
Claude Opus 5.5 takes the top spot on the Artificial Analysis Intelligence Index, along with a 20% price cut and larger cache hit discount
Claude Opus 5.5 brings Anthropic to parity with GPT-6 Astra on evaluations like Terminal-Bench 4.0 and AutomationBench-AA, while extending Anthropic’s lead in agentic knowledge work.
At max effort it scores 58 on the Artificial Analysis Intelligence Index, the highest score we have measured by several points. Anthropic has cut Opus pricing to $4/$20 per 1M input/output tokens (Opus 5: $5/$25) and cache reads from $0.50 to $0.20.
Key takeaways:
➤ Consistent strong performance, with leading scores on six of the ten Intelligence Index evaluations: Humanity's Last Exam 61.4% (previous best 59.1%, Claude Fable 5.1), SciCode 66.9% (63.1%, Fable 5.1), GDPval-AA v2.1, AA-Briefcase v1.1, AA-Omniscience and AutomationBench-AA. On Terminal-Bench 4.0 it scores 59.6%, level with the leader GPT-6 Astra (xhigh) and +11 points over Opus 5. It remains slightly behind on CritPt, AA-LCR, and GDP.pdf
➤ Leads in agentic knowledge work: On AA-Briefcase, our private frontier knowledge work evaluation, it reaches an Elo of 1822. This is +143 over Fable 5.1, ahead on both analytical quality and presentation, and is the first time Anthropic has reached presentation quality surpassing GPT-5.6 Sol. This evaluation tests whether models can produce accurate and well-presented professional outputs using our open source reference agent harness, Stirrup
➤ Level with Opus 5 on cost per task despite 1.6x the output tokens: Opus 5.5 (max) uses ~119k output tokens per Intelligence Index task, against ~73k for Opus 5 (max), ~78k for Fable 5.1 (max) and ~27k for GPT-6 Astra (max)
➤ Four of five effort levels sit on the Intelligence vs Cost per Task frontier: Opus 5.5 max, xhigh, high, and medium all sit on the Pareto frontier, costing less or outperforming other models scoring 50+ (GPT-6 Astra, Claude Fable 5.1, and Claude Opus 5)
Other model details:
➤ Context window: 1 million token context with image and text input support, unchanged from Opus 5
➤ Pricing: $4/$20 per 1M input/output tokens, down 20% from $5/$25 for Opus 5. Cache writes $5 per 1M tokens for the 5 minute TTL, down from $6.25. Cache reads have been further discounted to $0.20 per 1M tokens, down 60% from Opus 5’s $0.50. This is a 95% discount compared to uncached input pricing, up from 90% on previous Opus models
➤ Effort settings: Five effort settings (low, medium, high, xhigh, and max). Intelligence Index evaluations were run at all five with Anthropic's default fallback enabled


Marc | AI in finance retweeted

People outside the AI labs should have a real say in how this technology develops, and a clear way to judge if it's happening safely.
Standards should help prevent the concentration of power, including by making sure new companies and open-model companies can compete.
They should also help countries and companies compare evidence and learn from failures.
We think the US should lead this effort. Here is our proposal:
openai.com/index/building-st…

Marc | AI in finance retweeted
Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol
Grok 4.7 scores +2 points over Grok 4.6 on the Intelligence Index, with strong performance on agentic knowledge work tasks. We evaluated the new model at xhigh reasoning effort.
Congratulations to @spacexai and @ElonMusk on the release!
Key takeaways:
➤ Grok 4.7 joins the frontier of agentic knowledge work: Grok 4.7 gains +111 Elo over Grok 4.6 (high) on AA-Briefcase, our private benchmark for long-horizon agentic knowledge work, scoring 1657 Elo and placing it alongside Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA, it scores 1695 Elo, +90 ahead of Grok 4.6 (high).
➤ A leap in coding agent performance: Grok 4.7 (xhigh) with Grok Build scores 56 on the Artificial Analysis Coding Agent Index, up +9 points from Grok 4.6 (xhigh). Among models in their native harnesses, Grok 4.7 + Grok Build now ranks 4th, behind only Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5.
➤ Incremental performance changes elsewhere: Outside of agentic knowledge work, Grok 4.7 broadly matches Grok 4.6 (high) on the other Intelligence Index tasks. It improves on Terminal-Bench 4.0 (+4.5 percentage points) and GDP.pdf (+3.0 p.p.), with regressions on AA-LCR (-3.7 p.p.) and AutomationBench-AA (-1.1 p.p.).
➤ High token use across tasks: Grok 4.7's gains come with higher token usage. Grok 4.7 (xhigh) uses approximately 81k output tokens per Intelligence Index task, compared with 36k for Grok 4.6 (high) and 27k for GPT-6 Astra (max) - 125% and 196% more, respectively.
Other model details:
➤ Context window of 500k tokens, unchanged from Grok 4.6
➤ Pricing of $2/$6 per 1M input/output tokens with cache hits discounted to $0.50 per 1M tokens, matching Grok 4.6
➤ Configurable reasoning effort spans low to xhigh. Our evaluation uses xhigh.

Marc | AI in finance retweeted

Grok 4.7 is here.
It's a notable improvement over Grok 4.6 at the same price and speed.

Marc | AI in finance retweeted
My “armchair” thoughts on the personal agent race:
1. Muse is poised to become the leader. The app is intuitive, and Meta is aggressively promoting it across all its properties. Once you use the Muse app, you realize that it makes little sense for an agent to live in an existing messaging app like iMessage. Unless Meta runs out of compute or something, I think this will become the company’s most successful homegrown app after Facebook. It will be much bigger than Threads.
2. ChatGPT is probably still the personal agent leader because it already has 1B+ users. OpenAI’s models, computer use, and voice are arguably better than Muse feature by feature. But it’s hard to build one product for both work and personal use, and harder still to serve enterprises and consumers with the same UX. Even for work, I started using Grok Bot because the Work/Codex split remains too confusing. I’m sure the team is cooking, and we’ll see something good in the next few weeks.
3. Grok Bot isn’t really a Muse competitor because it’s focused on work. Multiple bots naturally fit team-based knowledge work IMO. My bull case for Grok Bot is that it's a few features away from becoming multiplayer agentic Slack for both bots and humans.
4. Google is obviously the dark horse candidate. All these personal agents live off Gmail, Google Calendar, and your Google app's data. Google has their own personal agent in Spark but the last I checked it's a secondary tab in Gemini. I think Google needs to be far more aggressive in making Spark the primary experience and making it intuitive and competitive with Muse. Google however doesn't have a great track record in multiplayer AI...
5. Speaking of multiplayer, nobody has figured this out yet. I can’t easily add my spouse to a Muse chat to plan a vacation. I also can’t loop coworkers into ChatGPT or Grok Bot threads. Multiplayer AI today mostly means tagging bots in Slack. Every major provider is probably working on this, and I think it will be the next big unlock.
My personal AI stack right now is Muse for personal, Grok Bot for cloud tasks, Claude for specific use cases, and ChatGPT for everything else.
But I think we’re going to see some major updates this week.
Everyone should design their personal skills and files so they’re easy to port between harnesses and agents. Otherwise, you’ll spend half your time moving from one tool to another.
Marc | AI in finance retweeted

I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.
Marc | AI in finance retweeted

After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
Marc | AI in finance retweeted

we're now moving into the AGI era (whether you view it as this model, the last one, or the next one), and could not do it without close partners

GPT-6 Astra, trained on ~100K+ NVIDIA Grace Blackwell NVLink72. From ChatGPT to o1 to Astra in 4 years.
AGI has arrived. Congratulations @OpenAI team.
400K GPUs coming online next.
Marc | AI in finance retweeted

GPT-6 Astra, trained on ~100K+ NVIDIA Grace Blackwell NVLink72. From ChatGPT to o1 to Astra in 4 years.
AGI has arrived. Congratulations @OpenAI team.
400K GPUs coming online next.
Marc | AI in finance retweeted

Kimi K3 has received far more love than we expected, and our GPUs are feeling it.
Over the past 48 hours, demand has pushed close to the limits of our current capacity. To protect the experience of existing subscribers, we're temporarily pausing new subscriptions and prioritizing compute for current members. Existing subscribed users are not affected.
We're adding capacity as fast as we can and will reopen new subscription spots in batches.
Going forward, we'll also split membership into two more focused plans: Kimi Membership for Kimi Web, App, and Work; and Kimi Code Membership for coding workflows. This will help us match compute more precisely and keep the experience stable.
Thank you for your patience and understanding!
Marc | AI in finance retweeted

Claude Fable 5 will be available again globally tomorrow.
After a series of productive conversations with the US government, we're redeploying the model with a new set of classifiers to target and block more cybersecurity tasks. In the near term, some routine tasks like coding and debugging will fall back to Opus 4.8. We’ll continue to refine these classifiers over the coming weeks to reduce false positives and better distinguish genuine misuse from legitimate requests.
We’ve also begun drafting a consensus framework—with Amazon, Microsoft, Google, and other Glasswing partners—for assessing the severity of AI jailbreaks and how AI developers should respond to them. We invite other industry partners and model providers to join us in this effort.
Finally, we’re scaling up our collaboration with the US government on model testing and safeguards. This will include pre-release access to models and safeguards for evaluation, information sharing on jailbreaks and misuse, and dedicated resources for joint research.
Thank you to our users for your patience, and to our partners across the government, industry, and the research community who worked alongside us to make Fable 5 available again.
Read our full blog: anthropic.com/news/redeployi…
