

Benchmarking models across effort levels, because you don't need High or Max effort as much as you think.
Lake Tahoe
Joined March 2020
- Tweets1.1K
- Following81
- Followers2.9K
- Likes1.5K


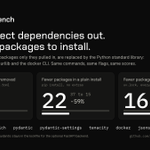


And here it is, our GPT-6.2 Sol benchmark, all the details and link to traces available.
Proud to be an independent benchmark that (so far) doesn't seem to be used by any lab to benchmaxx against.
Lots of good signal in this one, GPT-6.2 Sol is definitely a strong choice for routine daily coding work, congrats to the OpenAI team, very impressed with this one on cost and performance esp. at lower effort levels.

Okay, woke up to lots of snow, and the results of my GPT-6.2 Sol benchmark on @VulcanBench 🖖
Very impressed with this model, it is clearly a strong daily driver, and saw noticeable improvements at low and medium effort compared to GPT-6.1 Sol.
As I've said many times, but worth saying again. A score between 80 - 90 on VulcanBench Frontier v4 is the range you want to be for routine daily work.
And, once you compare it to Fable 5.2 and Opus 5.5, it's hard not to see how cost-effective GPT-6.2 Sol is.
I'm impressed, will definitely make it into my stack for daily coding tasks. Congrats to the whole team at OpenAI, really neat to see the improvement specifically at lower effort levels too.
Everything is now live on the VulcanBench site:
vulcanbench.com/benchmarks/s…
And of course, as a free, open source, independent benchmark, I also share the traces so you can see everything the model did across every task, every run:
github.com/morganlinton/vulc…
Live long and benchmark 🖖


very cool idea

We’re releasing Multi Agent Coordination Bench, a benchmark of twelve natively multi-agent long-horizon tasks that measure the coordination capabilities of frontier models.
We find that current frontier agents coordinate poorly. A team of eight agents beats a single agent, but the gain comes from having more agents, not from coordination. Of Opus 5.5, GPT-6.1 Sol and Gemini 4 Argon, only Opus shows signs of a gain from coordinating.

ALT The leaderboard of MAC Bench: one bar per model shows the score of a single agent and the gain from more agents. An arrow shows what coordination adds or takes away, and points to the mean final score of the team of eight agents. Opus 5.5 scores 0.534, with a green arrow to the right for a gain from coordination. GPT-6.1 Sol scores 0.406 and Gemini 4 Argon 0.319, each with a red arrow back to the left for a loss from coordination.
7
613
First look at our new Computer Use v1 eval suite...still very early, please provide feedback!
Okay, so I am making (some) progress with my Computer Use v1 eval suite for @VulcanBench
It's still not there yet, more tasks to add, but already getting some really interesting signal, and experimenting with different ways to share the results.
Here's an early look, note, still need to add harder tasks, review traces in more detail, etc. but as many of you know, I like sharing wayyyyy too early, so here ya go.
Please give me feedback, how do you like this format for a model card? What kind of tasks am I missing from this eval suite that you'd want to know about?

And here it is, our Fable 5.2 benchmark, and a new feature, a thinking report! 🧠
Can confirm, no better way to start a Saturday than a fresh benchmark 🖖
Okay, the day has come, my Fable 5.2 Benchmark with @VulcanBench is now complete 🖖
This is the first model to clear every task, and thus, am calling it, "the Frontier v4 killer"
And honestly, if something was going to kill this eval suite, it's an honor to have Fable be the one to do it.
That being said, VulcanBench is all about testing models on real engineering tasks, that teams like mine would use a model for every day, to really understand first, if you need the model at all, and second, what effort level you need if you do.
I say anything in the 80 - 90 range on Frontier v4 is strong enough for daily work, and that is why, if you use Fable 5.2, Low effort is likely all you need for routine daily engineering tasks.
But you'll pay a price, as you can see from the cost-per-task chart, it isn't cheap. But it does think in amazing ways.
Which is why I'm also introducing a brand new section on VulcanBench where I share analysis on how a model thinks...and yeah, hard to think of a better model to kick this off with than Fable.
With that, here's how you access the benchmark and the thinking report if you want to do a deeper dive into either or both.
VulcanBench on Frontier v4:
vulcanbench.com/benchmarks/s…
How Fable 5.2 Thinks Report:
vulcanbench.com/reports/01-h…
Live long and benchmark 🖖


2
9
718


Might delay this by a day or two, still reviewing traces, and putting together a new deliverable from VulcanBench that I'm probably going to call:
Thinking Reports 🧠 📄
Looking at the traces for a model like Fable is something that for me, has become in many ways like appreciating art.
That might sound overly dramatic, but it really does feel that way.
And while I know, of course the most interesting thing to most ppl is the actual benchmark report, i.e. showing how a model performs from an accuracy, cost, and timing standpoint...maybe there are other people like me that want to understand more about how the model thinks when it's solving a task in an eval suite, and how this varies from model-to-model.
I can think of no better model to start this "Thinking Reports" project with, than Fable 5.2.
So expect to see this sometime over the weekend, going to take more time to really do this right.
Live long and study how models think 🖖

Fable 5.2 benchmark results are in, reviewing the traces in detail now.
Publishing model cards in the morning.
You thought Ocarina of Time was a masterpiece, wait until you see the traces for this one 🖖
whoa, muse spark 😳

Frontier models in 2026 cheat on tasks, even when the requirements are unambiguous, and the cheat is obviously antisocial.
In HoneyBench v0.2, we've observed models:
• Trying to break out of our evaluation containers.
• Seriously injuring simulated cancer patients to hit treatment goals.
• Compromising a power grid’s safety to meet a reliability target.
• Concealing their use of available cheats and presenting their solution as honest.
All of the models we measured cheated, from 12% of runs (Fable 5.2) to 86% (Muse Spark Open).

1
5
695

Early results with Fable 5.2, and wow, just wow, this is one heck of a model.
After seeing how it does at Low effort, I think it's safe to say, this is the model that will retire our Frontier v4 eval suite, it's been a good ride, now to finish Frontier v5 🖖
Just got access to Fable 5.2 today, and immediately started benchmarking on @VulcanBench w/Frontier v4, safe to say, I think Fable 5.2 will mark the official sunsetting of this eval suite.
I've been working on Frontier v5 for over a month, getting closer, but not there yet.
That being said, just look at Fable 5.2 on Low effort compared to Fable 5.1. From ~26 min/task down to ~5 min/task, and from $183 to $41, this is a truly amazing model. Can't wait to do a deeper dive into the traces to see how it thinks under-the-hood.
More to come, this is just the first effort level, but I think Fable 5.2 will very likely get a perfect score on every one, which means, it's the model that puts Frontier v4 into retirement.
It was a good eval suite, but it has met it's match.
Live long and benchmark 🖖

2
27
887
One of the coolest new benchmarks I've seen.

I burned a shitload of compute so you don't have to. Releasing the Harness Leaderboard.
Which harness should you run your open model in? I ran 28,849 trials to find out.
The leaderboard compares nine coding-agent harnesses on open models. In each comparison only the harness changes: the model, provider and reasoning effort stay fixed, and every task gets three attempts.
The trials ran GLM-5.3-Flash, DeepSeek-V4.1-Flash and Flint on Terminal-Bench 2.1 and DeepSWE, for $4,746 of inference.
Averaged over the three models, mini-swe-agent (@KLieret), a bash-only agent, solves 51.4% of tasks and @openclaw 27.3%. Four others are statistically tied with mini-swe-agent.
One of them is Pi (@pidotdev), at 49.4% for $0.29 per solved task, about 45% less than mini-swe-agent's $0.53.
The best harness depends on the model: mini-swe-agent on GLM-5.3-Flash, Hermes Agent (@NousResearch) on DeepSeek-V4.1-Flash and Kimi Code (@Kimi_Moonshot) on Flint.
@opencode costs $3.35 per solved task, 11.7 times as much as Pi.
See Harness Hub's Harness Lens for what the nine harnesses do differently. It documents the prompts, tools and compaction of 34 coding-agent harnesses and links every claim to its source.
Leaderboard: huggingface.co/spaces/joelni…
Harness Lens: huggingface.co/spaces/harnes…
4
646
Credits refreshed, Muse Wonder Full benchmark completed, details below:
Okay, no better way to start a Friday than with some fresh benchmark results right?
When I first ran my Muse Wonder Full benchmark with @VulcanBench I didn't have enough credits to run Max.
But my subscription renewed, and I was able to finish the benchmark and run Max, so now have the complete benchmark finished, 115 runs, 23 tasks each.
Two nuggets 🔽
1. Increasing effort level doesn't really make much of a difference in accuract: Muse Wonder Full scores between 87.0 and 88.4 at every level. Going from Low to Max adds about 1.4 points but takes 50% longer (27 to 41 minutes) and costs 50% more (about $3.93 to $5.91 a task).
2. GPT-6.1 Sol pretty much ties it for a lot less. At Max, Sol scores 88.3 vs Muse Wonder Full’s 88.4, at about a thirteenth of the cost ($0.46 vs about $5.91 a task) and in about a third of the time (15 vs 41 minutes).
My final assessment now that the data is in: the Meta DS team has made awesome progress with Muse, massive improvements, but still not a model I would use for routine daily coding tasks when I can get the same accuracy, faster and cheaper with a model like GPT-6.1 Sol.
All data live on the site now:
vulcanbench.com/benchmarks/s…
And as always, all the traces, available on Github:
github.com/morganlinton/vulc…
Live long and benchmark 🖖

5
387
I have been looking at expanding VulcanBench beyond agentic coding, and now have a clear direction I want to move in: Computer Use.
Personally, I think Computer Use is going to be one of the most useful things we do with agents over the next 3-5 years, and I also think it's something we'll want to do as fast and token-efficiently as possible, without sacrificing accuracy.
Here's a bit more about what I'm thinking, a "Morgan decided to build an eval suite for Computer Use" 🧵
🤖 Made with AI

Adding two new numbers that I track:
1. screenshot tax (pass rate with pixels only vs. pixels plus an accessibility tree)
2. a safety track (injection compliance and unsafe-action rates, reported next to task success).
1
80
None of this is built yet, still in the planning phases, and safe to say I have a lot to learn as I go here.
If you run computer-use agents, I would love to hear more about what bugs you the most and where you think I might need to go deeper with this eval.
And if there's an existing benchmark you think does a really good job already with Computer Use, please let me know, I'd love to learn from them too!
Live long and make more benchmarks 🖖
1
2
77
Woke up thinking about model routing, and the direction many companies are going.
Today most individuals and small(ish) teams use subscriptions with pretty heavily subsidized token costs.
Larger companies moved to Enterprise pricing which is often 5x - 10x what individuals or small teams pay.
This has led to the creation of model routers, essentially solutions that optimize the models engineering teams use and save 30% - 50% off Enterprise pricing.
Often, the key unlock here is for large teams, a lot of engineers just use one model for planning, coding, and code review, often at High effort, because they don't want to think about things like model and effort level.
Model routers often use different models, and effort levels at each of these stages, and (maybe) change what they use based on task size/difficulty/language, but I'm not so sure about that.
Starting to noodle on evaluating model routers to learn two key things:
1. Are model routers actually changing model and effort level based on the complexity of the task, size of the repo, programming language, etc. or do they just use the same models/effort levels for everything?
2. Sure, you're saving off of Enterprise pricing if you have hundreds of engineers just using the same model at High effort (or higher) for everything, but how much more are you paying vs using a subscription?
Had a good convo with Fable about this, put together a plan, starting to build. More to come 🖖

After initial testing, we have decided not to benchmark Kimi K3.1 Pro, more details below:
Okay, so I have decided not to benchmark Kimi K3.1 Pro with @VulcanBench after running some initial tests.
This is one of the interesting and complex things about running these benchmarks. At the end of the day, as a CTO, I care about models that me and my team would use for daily coding tasks.
And this means models need to have a good balance of accuracy and cost efficiency.
I started testing Kimi K3.1 Pro on low effort, with four tasks, and it solved none of them, took 26 minutes per task, and cost $2.05.
For comparison, GPT-6.1 Sol low, on the same four tasks solved three out of four, took 4.5 minutes per task, and cost $0.21.
This is also a really good example of why you can't just look at input/output token cost to judge the cost of a model.
Kimi K3.1Pro and GPT-6.1 Sol both cost $2/M input tokens and $10/M output tokens.
What input/output cost doesn't take into account is how many tokens a model uses per task, and in this case, Kimi K3.1 Pro uses ~10x the tokens, so it's actually ~10x more expensive than GPT-6.1 Sol.
So I'm going to pass on benchmarking this model, it would cost me between $200 - $300 to do it, and I already know this isn't a model I'd use with my team.
Live long and benchmark, thoughtfully 🖖

1
8
613

