

Build scrapers without having to manage proxies and headless browsers!
Joined May 2018
- Tweets756
- Following402
- Followers567
- Likes89




Thinking about switching web scraping tools?
We've compared #ScraperAPI with some of the most popular data collection infrastructures, covering pricing, features, and common use cases.
Take a look before making a decision: buff.ly/SWz3T2F
#webscrapingtools #comparison

No two #AI teams build the same way.
Whether you use MCP, LangChain, LlamaIndex, n8n, or the CLI, your web data layer should fit your stack, not force you to change it.
Find the right #ScraperAPI AI integration for your tech stack: buff.ly/qjn3xqZ
#ScraperAPI #llm

A drop from 4.5⭐️ to 3.9⭐️ is easy to spot.
Understanding why takes a closer look at the reviews.
Learn how to turn customer reviews into structured insights: buff.ly/q7p5xYc
#ScraperAPI #reviewanalysis #dataextraction

Building your own #proxy infrastructure is only the beginning.
Once it's live, you're responsible for monitoring, maintenance, scaling, and everything in between.
Before deciding to build in-house, understand the full operational commitment: buff.ly/qsIeNHY

Your marketplace data shouldn't have a single point of failure.
Whether it's pricing, operations, or commercial strategy, multiple teams depend on consistent access to reliable data.

ScraperAPI backs its infrastructure with enterprise SLAs, zero reported outages, and support that responds in under an hour, because reliable data collection doesn't end with successful requests.
Learn more: buff.ly/BpfwOqM
#ScraperAPI #marketplacedata #webscraping

There's no better validation than hearing how customers use ScraperAPI in the real world.
Feedback like this motivates us to keep building a product that's reliable, accessible, and delivers real value. 💙
#ScraperAPI #capterra #reviews

Stop asking, "What should we build?"
Start asking, "What is the market missing?"
Use competitor websites, customer reviews, and community discussions to validate ideas before you build.
See how #webscraping helps #startup: buff.ly/8knsty
#ScraperAPI

We're hiring a Growth Marketing Specialist at ScraperAPI, fully remote within Europe!
Full details and how to apply: buff.ly/Pot4ek5

A product page can look different depending on where you access it.
Prices, availability, promotions, and even product details can vary by country or ZIP code.

If you're building on web data, collecting one version of a page isn't enough.
Learn how to collect the right product data, not just any data: buff.ly/flmbSVD
#ScraperAPI #geoscraping #datacollection

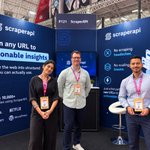
"Wait, I can actually get that data?"
We heard this again and again at Big Data London last week.
The ScraperAPI team talked with people from e-commerce, education, space manufacturing, commodity trading, and more.

Many didn't realize how much public web data was within reach:
• SKU-level pricing
• Market intelligence
• Product data across e-commerce sites
Datasets that could sit right next to what's already in their stack.
That's where ScraperAPI comes in. We handle pulling data from any URL, so you can focus on what you do with it: visualize it, share it with your team, and build insights on top.
Thanks to everyone who stopped by the booth! Explore our solutions and APIs: buff.ly/e5e9XTI

What's the difference between #webscraping and web data infrastructure?
Web scraping collects data.
Web #datainfrastructure keeps that data reliable, even as retailer websites change.
See how enterprise teams build for reliability, not just collection: buff.ly/nTruEsy
As AI and automation also become embedded across more business functions, access to reliable public web data is becoming critical far beyond technical teams.
Businesses increasingly need current external data to power AI applications, monitor markets, and automate decisions.
New AI search monitoring capabilities covering ChatGPT, Perplexity, Gemini, and Google AI Overviews will enable organisations to understand how their brands, products, and competitors are represented across AI-generated answers, supporting a growing need for AI visibility.