

navigating the frontier. cooking something personal
Joined July 2013
- Tweets1.6K
- Following1.1K
- Followers1.7K
- Likes6.8K

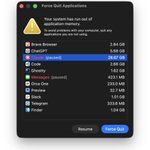


nah, but it's happening. mainly bc we it's hard and expensive af for people to own their own personal compute cluster. But i want to live in a world where everyone owns their intelligence by having a personal compute cluster, likely financed like how you would finance a car

we will get local and super fast computer use once they release the local version 👀

Announcing d1, our first decision model.
It's the first model to outperform Jev on @huggingface's Decision Index.
> wins on multilingual evals
> more robust against prompt injection
> handles longer inputs more effectively
> built for fast, structured decision-making in software environments
> Liquid API: console.liquid.ai
> Available on OpenRouter soon

Are the subsidies ending

Hi,
Tomorrow we are re-opening the Pro $200 subscriptions to new subscribers, but together with it we are also changing how we calculate the usage for it. In effect, if you do the math, it will net out at half the dollar in API spend compared to the old Pro $200 plan.
Now that it's said, let me explain why this is happening and why you will still get more work done than if you were on the Pro $200 subscription one month ago.
(a) We didn't want to compromise in other ways and are committing to not reintroducing the 5h limit, so that you can fully use the weekly usage when you want.
(b) On the subscription, we guarantee that over time you always get more work done and with an increasing level of quality. This means that you will continue to get more value per dollar spent as a result of models getting more efficient and us passing down the improvements in the form of API price reductions.
(c) We don't want to put an incentive on ourselves to artificially inflate the API list prices to make it look like you are getting a lot (and workaround it through discounts, etc). Instead we want to continue to both rapidly reduce prices and increase capabilities of models on the API. This week we introduced GPT-6 Sol and GPT-6 Luna at 50% of their previous price. Over time, we see prices go low enough that it makes sense for most to buy usage as needed without there being a significant gap between what you get in a subscription and what you get in the API for a dollar spent.
(d) Tomorrow, we are adding more things to the subscription that won't draw on the usage, I won't reveal what that is yet.
I wanted to be transparent before all the big announcements tomorrow. Lots of new exciting things are coming to the subscriptions that will make it super compelling, but I wanted to make sure to share this change ahead of time so you can all understand it before we shower you with good news.
Codexingly,
Tibo

Navigating this market where things are constantly in flux is like a war on attrition. Keep going anon.
RSI has a speed limit and it’s how quickly you can deploy compute. The algorithm is not the limiting factor. Elon understands this.

Elon, I'm going to be honest.
I don't think it's possible for Grok to catch up with OpenAI or Anthropic at this point.
They almost certainly have some impressive level of recursive self improvement going on internally. Their models are writing code, running experiments and speeding up research for the next model.
Every month they get faster. You're not just 3 months behind. You're 3 months behind a rocket that's still accelerating.
I genuinely hope you prove me wrong though. I'm rooting for Grok.


I am 99% certain that in the coming few years, the majority of daily work stuff will be managed using local LLMs, leaving the cloud frontier models to tackle the challenging stuff

Qwen3.8-27B now runs on 8GB of VRAM!
That's less than 500$ to run a model smarter and more capable than:
1. GPT-5.6-Luna High
2. Opus-4.6-Max
3. Gemini-3.1-Pro
And ties with:
1. GLM-5.2 Max
2. Gemini-3.6-Flash
PrismML has the mandate

Readers added context they thought people might want to know
The cited rankings reference Artificial Analysis benchmarks for full-precision Qwen3.8 27B (score 34), not PrismML's quantized ternary version which retains 98.2% of the base per its own benchmarks with no independent eval on this index.
artificialanalysis.ai/models/qwen3-8…
prismml.com/news/bonsai-2-…
testing different open source voice models on the apple silicon. getting 390X real-time factor using the neural engine 👀
Is this just BERT but trained at llm scale?

After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution

with astra and fable, it's actually the best time to make crazy advances in computer science stuff. you can just point astra at a paper and implement things
maikeru retweeted

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

maikeru retweeted

AI can make work faster, but a fear is that relying on it may make it harder to learn new skills on the job.
We ran an experiment with software engineers to learn more. Coding with AI led to a decrease in mastery—but this depended on how people used it.
anthropic.com/research/AI-as…


maikeru retweeted

What Claude Code has revealed is that most people either have mediocre ideas or no ideas at all. The tool is a force multiplier for those who already know what they want to build and how to think through it systematically; it elevates competence, rewards clarity, and accelerates execution for people who would have gotten there anyway, just slower. If you have a sharp vision and can break it into coherent steps, Claude Code becomes an extension of your own capability.
But there's another mode of use entirely. For people without that clarity, the appeal is precisely that the input can stay vague; you gesture at something, hit enter, and wait to see what comes out. This is structurally identical to a slot machine: low effort, variable reward, and that intermittent reinforcement loop that hooks the susceptible. So the same tool that elevates the focused and capable is also manufacturing a kind of gambling behavior in people prone to it.