
SIGMOD Systems Award for Amazon Aurora · Creator of AWS SimSpace Weaver · Prev. Microsoft Research + Amazon Research · High-school dropout → MSCS + AI, @UW ·
us-west-2
Joined February 2007
- Tweets2.8K
- Following1K
- Followers4.1K
- Likes7.9K




Pinned Tweet
If AGI kills us all, it won't be the model's fault. It'll be the duct tape and footguns we wrap it in.
You are paying a company $400/month for a data subscription that starts losing data.
You email support with the message:
>"We are experiencing problems with our data subscription, can you please take a look"?
Of course, this was the polite "royal we" usage of the word "we".
They email back:
<"We noticed your use of the word 'we'. Are you an individual? Do you have a team? We will need to send you an updated quote you for our more expensive team offering."
The missing data is still missing.
No update has been provided on fixing it.
What does this mean?
How would you respond?
A lot of people seem confused about the availability of larger context window sizes in Codex.
Please allow me to clear it up for you (with pictures).
Let me also clear up one other point of confusion: this has been available to you since early August.


Day 7/
We have increased default context length for GPT-6.1 Sol to 500k when used through Codex & Work, up from 272k or an ~ 80% increase.
We will go higher in the future, but it helps reduce occurrence of compactions and with tasks that require keeping a lot of context and nuance over periods of time. It was carefully tested and is the new sweet spot for most of our users. You can still override it if you want to be higher our lower, with maximum context length of GPT-6.1 Sol of 1M.
Folks, the entire 1.05m context window is already acceptable free of charge with your Codex subscription.
Stop allowing these companies to gate-keep shit that is already free.
Day 7/
We have increased default context length for GPT-6.1 Sol to 500k when used through Codex & Work, up from 272k or an ~ 80% increase.
We will go higher in the future, but it helps reduce occurrence of compactions and with tasks that require keeping a lot of context and nuance over periods of time. It was carefully tested and is the new sweet spot for most of our users. You can still override it if you want to be higher our lower, with maximum context length of GPT-6.1 Sol of 1M.
I regret letting Codex ever run with a /goal prompt or launch sub-agents.
It doesn't matter what model it is at this point. The Sol and Astra lineage are completely RL fried.
It doesn't matter how tight the prompt is or the agent instructions are. I've even had prompts and instructions externally reviewed and rewritten, but it doesn't change the behavior.
The model always goes off track, ignores scope, and finds a way to digress into scaffolding, certification machinery, evidence gathering or audits. Even with the literal words barring it from doing so are right there in the prompt, plan, or instruction file.
And it always ends in an absolute mess of junk files, slop code, and an account drained of limits.
Codex can only be used effectively through the tightest of handholding. Keep one-shotting whatever you want if it's working for you. But real work on an existing system is excruciating and nearly impossible.
They are shipping models they know don't follow directions and are nearly useless for real long-horizon work.
Exciting update: the safety check before the coding agent torches everything on your computer is now included at no additional charge!
Day 2.1/
We have made Auto-review free for all users signed in through a ChatGPT account. You can enable it in settings > permissions > auto-review. Auto-review improves upon the default sandbox setting that requires you to approve everything, which is prone to decision fatigue unless you spend a lot of time configuring specific rules.
It allows you to run long tasks while having a second agent review all actions taken by the primary agent. Its only goal is to prevent high-risk actions from being taken and to protect against unwanted actions that are not aligned with the original user intent. This Auto-review feature is now free and does not draw usage from your plan.

You have to be a real jerk to admit you've been operating subscription accounts at half speed and that all you had to do was flip a switch to fix it.
Day 1/
We have optimized the default speed to be ~50% faster across GPT-6 Astra and GPT-6.1 Sol through the subscription across all our products and partners using Sign in With ChatGPT (including OpenCode, Pi, Amp, Devin, ...).
No changes needed on your end and this should be felt within the next two hours.
Just in case the games aren't clear at this point:
xitter.cf/BrenBuilds/status/2107…

If you let these jamokes get away with this crap they will perpetually route you to the dumbest model they possibly can, using the tiniest reasoning budget they can plausibly allocate you, all while constantly compacting your context window usage.
The model will be slow, stupid, forgetful, and untrustworthy.
But, on the bright side, there probably won't be any usage limits to worry about.

Tibo confirmed that OpenAI plans to merge Codex and ChatGPT capabilities, with the goal of making the experience less complex for users:
“…and for Codex and ChatGPT, we have Chat and the Work toggle, and we’re going to merge them. We’ve heard the feedback loud and clear: people love the capabilities in Work, but sometimes you want to use Chat because it’s a little faster and more pleasant to use. So we’re merging the two and reducing that complexity.”
Feeling underwhelmed by DevDay announcements and product reveals? Are 50% plan cuts getting you down?
Maybe you're tired of seeing Tibo stroke his little reset button? Perhaps you're ready to see OpenAI get totally mogged by a rando on the internet instead?
Well, be ready to ditch your Dots and upgrade to the coding experience OpenAI should have built.
The countdown to launch starts now...

Why do I have to find out from some rando on the internet that my account is automatically spending down the brand new credits I just received to compensate for OpeanAI's decision to cut Pro plan limits in half?
If you have anything in Codex running, and you have a Pro plan, you should probably take a look before OpenAI scams back the credits they just gave you two days ago.
Absolute garbage customer treatment. Without even the courtesy of a reach-around or lube.
Scott, I don't know you, and I also have never argued in public before, but I am a betting man. And I and am willing to lay you odds, given the relative correctness of our positions, to debate you publicly, anywhere, anytime.
My position is: If AI is going to kill us all, it will be the direct result of human actions and decision making, not because of intrinsic AI properties. Further, the presumption of inevitability encourages fatalism, panic, and distraction from human responsibility and accountability. And from this lack of clear-eyed responsibility and accountability, we are driving towards our own demise.
I am happy to put up $25,000 to your $5,000 (ie, 5:1 odds in your favor) that I'll win by some standard of audience opinion change.
This is a 100% serious offer if you are interested. But I feel its time to have public pushback against unqualified AI hysteria.

I think you've done enough calling us paranoid and preposterous. The next step is for you to defend your position in public against someone who will push back against it. I'm happy to meet you for a debate anywhere, anytime.
You're a world-famous veteran of dozens of debates against the world's top intellectuals, and I've never argued in public before, so adjusting for the relative correctness of our positions, if you're a betting man I'm happy to put my $5000 against your $1000 (ie 5:1 odds in your favor) that I'll win by some standard of audience opinion change. Let me know if you're interested and we can hash out details.
I was consistently using an xhigh or max effot level, but when I looked deeper, I found that most invocations to the model were receiving little to no thinking tokens at all.
And when longer thinking runs did happen, they almost never reached published benchmark levels.

This unfolded across a six week data capture and analysis odyssey, and led to a number of surprising findings.
Next time the model feels dumber, don't ask if the model was "nerfed".
Ask about the inference regime you were served, instead.
xitter.cf/Lon/status/21010349332…

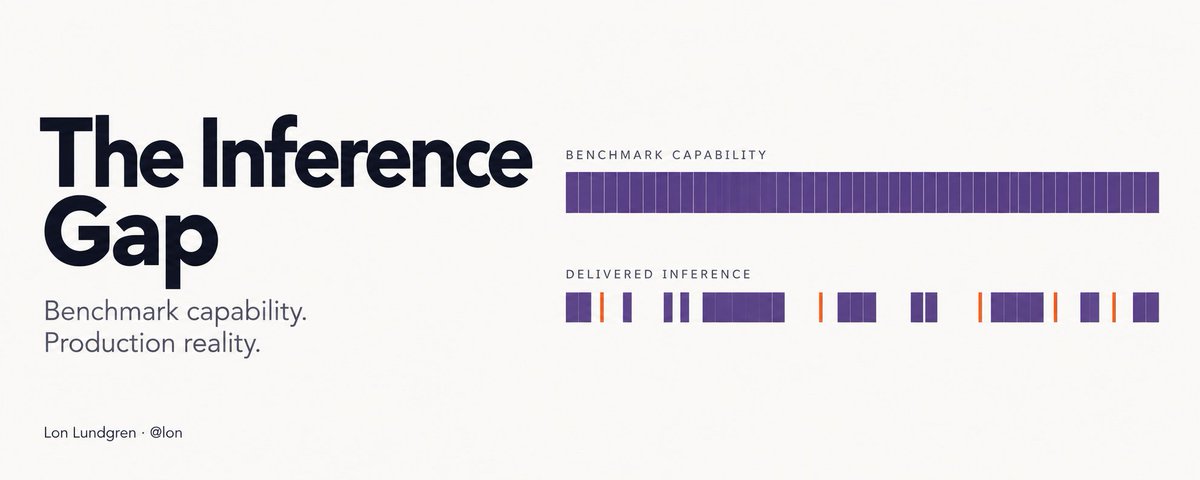
After Anthropic made Fable 5 permanently available in subscription plans, I noticed a large drop in performance. The model felt dumber, and I couldn't explain why.
Measured five different ways, August delivered dramatically fewer thinking tokens than July.

