

COO @codos_ai | Investing @Delphi_Ventures Prev: @delphi_labs, @IBM, @HPE, @McKinsey, @CarnegieMellon, reformed CFA
Joined March 2015
- Tweets8.5K
- Following943
- Followers21.2K
- Likes29.6K




Do AI models and agents like your [company / product]?
I had Instinct buy a gift recently, I have no idea why it recommended that particular product, but I bought it
There is so much opportunity for people who get this right for their company / products
Based on everything I've seen and heard from joining @codos_ai, I'd highly recommend @speedrun to any founders who want to accelerate their early stage journey

.@speedrun has been an incredible adventure!
In 12 weeks we grew 3x, launched, got 1.6M views on X, saw real market pull and nailed the Demo day.
I'll decompress and share more later, but the program is designed to help you speedrun to your dreams. Get traction, launch, pitch, repeat.
But the best is the people. SR007 batchmates and the team is ❤️
Grateful!


The productivity jump from personal agents come from giving it the keys to everything
It's the same thing you'd eventually give a great human assistant, once there's history and trust: your passwords, your calendar, the keys to the house
Most people stop short of this and are then underwhelmed with what agents can do
Reminds me of when people in the early dotcom era were afraid to buy online with a credit card
Curious where people draw the line with sharing info with agents?
What have you actually handed over, and what won't you?
To be relevant in the AI/SI era, companies need two things:
1. Shared context layer
2. Agent control plane
Once those are in place, everything builds and compounds on top
Just don’t get locked into a vendor that owns and controls all of it
Agree the Jensen / Gerstner pod was a great listen and these are some good notes below
But just remember, they're both talking their book, so do your own independent thinking on how the scenarios and numbers may play out

Just finished listening to Jensen Huang with Brad Gerstner on the BG2 podcast
Probably one of the best things you can spend 90 minutes of your time listening to this weekend. Highly recommend.
Some of my takeaways from the conversation
1. The demand for compute will continue to be exponential. He once again cited inference as the biggest reason. Reasoning takes a lot more compute than simply spitting out answers from stored memory of knowledge
2. As more compute is used, the work and answer quality will also be better. This will lead to higher demand for that compute, leading to the exponential cycle that Jensen is referencing
3. The harness and tool usage have been the two biggest unlocks in AI over the last year. AI used to simply be a brain of knowledge. Now it has a skeleton around it that allows it to be useful. It is learning how to use existing tools to do better work without having to recreate tools from scratch each time.
4. The cost of intelligence will fall fairly quickly in the coming years. This will be driven by a combination of more compute coming online and better efficiency of models. No different than Moore's Law. Jensen still believes that the consumption of the intelligence (volume) will more than make up for the decline in pricing
5. The original GPT-1 cost $20M to train. If you train GPT-1 today, that number would be closer to $100. That is how fast the cost of intelligence is coming down.
6. The offset to this has been usage of the models and human ambition to build even better models. Despite cost coming down, usage of models has gone up 1M (x) times since GPT-1.
7. Jensen disagrees that work hours are going to come down. The more you learn, the more you want to do. Human ambitions have always existed to achieve and earn more. The bottleneck was the opportunity to do it.
8. Robotics is entering its ChatGPT moment. Similar to what Elon did with cars, every physical aspect of the world will soon be digitized with software and compute. Every massive corporation will have to reinvent itself as a technology company with AI
9. Safety is a core component of accelerating AI technology. When you think of a car, you don't just think of the engine. The airbags and braking systems are components of this car. Similarly, regulation and safety are core components of AI
10. NVIDIA's share of capex with the Neocloud customers is roughly 80%. With the cloud service providers, it is closer to 40%. Both of these numbers are growing every single year.
11. Even without AI, the semiconductor industry was already on its path to becoming the largest industry in the world. AI is the "X factor" that has accelerated that.
12. Moore's law is over. Before you could wait a year for your transistor cost to become cheaper. Today, if you wait a year, you will pay 2x as much
13. Analyst consensus estimates have been revised nearly 200% higher for future revenue and free cash flows vs. this time last year. Despite that, the stock is only +20%
14. Analysts questioned the need for general-purpose chips vs. custom chips. The reason that Jensen remains focused on general purpose is because it is fungible. Fungible = lower risk, which matters a lot when you are putting hundreds of billions of dollars to work
15. Global compute infrastructure spend was roughly $1T/yr. That old world was the retrieval way of doing computation. Jensen sees this number closer to $10T/yr in the near term, with roughly half of that spent on intelligence capex
Imagine if we could get Hagglebot working inside government
Maybe this is the agentic version of DOGE and who better to bring it into the world

We are putting a lot of effort into a specialized Hagglebot for business use, as we think it could improve enterprise cost-efficiency by 5% or more.
Applied to the global GDP, this could be up to $6 trillion/year in savings, delivering an immediate and measurable advantage to any company using Grok @Bot.
Anthropic: ~30 PRs per person per day
Spawn: ~900
Many enterprises we run AI-native diagnostics on are typically doing 1–2 PRs per engineer per WEEK
We try to explain what's happening on the frontier but they honestly have no idea


152 days
That's the gap between the Hermes Agent launch and the Grok Bot launch
In the 60 days since we got: Instinct, Muse, Dots, Hark, Fo, and more
Most of them are hard to tell apart
So this isn't a product race anymore, it's a distribution race, and the biggest digital land grab since the browser
The prize is the surface billions of people will talk to every day and the ability to monetize that in so many ways
Who wins it?
Cool map of the personal agents landscape
There’s really one key distinction - do you own the computer that it runs on, and thus own your data?
If you own the computer, that’s a cost to you, so what you get in return is privacy and flexibility
If you don’t own the computer, that’s a cost to the provider, so they have to monetize you directly or indirectly


That was too easy!
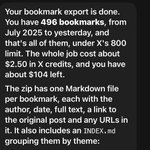
Added 496 X bookmarks to my second brain with one prompt and $2.50 in API credits
Now I might actually get some use out of them


Why not just use the Claude app for your "company brain/OS"
I'll give you 4 reasons and explain why a company brain/OS will be critical foundational infrastructure for every company
1. Context that works at company scale
Connectors help, but once your real context exceeds what the model can hold accurately, you get partial answers that compound into bad workflows, you need entity relationships and conflict resolution, not just search
2. Model-agnostic by design
Claude is great, but locking the company to one [expensive] provider isn't, the company brain/OS can embed smart routing by task and cost
3. Multiplayer, not single-player
Shared skills, shared projects, permissioned apps built natively on top, and all of it built for the org, not one power user
4. Agents with guardrails
Spinning up coworker-like agents without ownership, permissions, and governance is how you get chaos, and the company brain/OS solves for this
You can use a frontier lab app as a start, but if you want to own your intelligence and have maximum flexibility, the company brain / companyOS / whatever we call it becomes obvious infrastructure in hindsight
We're building a version of this at @codos_ai and if you want to learn more reach out

after switching our approach to building a "FirmOS", I'm increasingly confident that the future of agent collaboration within organizational settings is going to be a "company operating system" or CompanyOS, designed for agent and human collaboration
instead of a "company brain" that holds everything, the OS is for storing rules, processes, decisions made, which tools to use and how. it can mirror some data, but the source of truth is often best held in your existing tools (CRM, etc.). it's continuously updated and used by your agents
i think of this as a "flipped playbook" where instead of writing down the company rules first and following them (which is kind of like waterfall development), you're constantly updating the playbook as you decide or learn new things day-to-day running the business
Be an AI lab with 5 people and $300k
>take a good base model like GLM 5.3 Flash
>focus on non-verifiable domains instead of math and coding
>don’t hire expensive experts and buy datasets for RL
>instead create the environments and build synthetic data
>do the RL on your synthetic data and aimed specifically at knowledge work
>publish a frontier class model at 60x lower cost

We are releasing Ultramarine 1 Flash, a frontier-class model built for knowledge work. It is open-source and achieves similar performance to Fable 5, while being 60x cheaper.
It was post-trained by a team of 5 for ~$300k all-in. Available on API now, with weights releasing in 2 weeks.
“Every company I talked to wants to pipe its internal data into one place and expose it to agents through MCP”
We have this solution at @codos_ai
“Then they look at the data and realize it's a mess: five versions of the same customer, old Slack channels, PDFs nobody can search. Cleaning that up feels like a big consulting opportunity!”
Agreed!

I spent 48 hours in SF hanging out with billionaires, data labs and AI founders and execs running $1B to $100B companies.
My observations:
1. Sooo MANY stories of data brokers making like $2M a WEEK selling company data to labs. I can't tell if it's the beginning or a bubble, and I kept wondering which niches are left. Digging into it actively.
2. At dinner, someone asked the table, "If a new model drops next month, does your company get better or worse?" HALF the table went quiet! I think that's the best question to ask about any AI startup right now.
3. The bar people talk about now is hitting $1B in revenue in 12 months (I guess that's the new unicorn?). What I didn't hear much about is retention. AI revenue can come in fast and leave fast, and I think we're going to see a lot of stories of AI companies with huge revenue and terrible retention.
4. It's pretty clear we're living through the reinvention of the computer. The model is the CPU, the harness is the operating system, and skills and plugins are the apps. Thinking about it that way makes it easier to see where the whitespace is.
5. We're maybe 12 months from an agent that can watch you work for a week and then do your job without any instructions. The screen recording plus agent memory plus local model combination makes this possible right now.
6. Agent harnesses feel like the new GPT wrappers, in a good way, especially vertical ones. The best teams I talked to treat the model as swappable. One founder walked me through routing different models to different jobs: one for taste and visuals, a cheaper one for the everyday stuff, another for text.
They use prompts they can move across models over fine-tuning, and A/B test the output on what users actually do with it: do they edit it, export it, share it? A vertical harness is basically four things: the connectors for that industry's data, evals written by people who know the work, rules for what the agent can and can't touch, and a clean screen for a human to review. The model is maybe 20% of it.
7. There's a lot of reverse engineering going on/cloning going on more than I've ever seen. People are decompiling software and rebuilding it with agents, and someone showed a suite of like 10 apps that are worth $5B+ each all that he cloned open source. Me and everyone are still thinking through what it means when software gets this easy to copy.
8. My guess is the value moves to data. If the software can be rebuilt quickly, what's worth paying for in a legacy SaaS company is the years of customer data and workflows inside it. Some SaaS companies are secretly data companies.
Gets me thinking about how do you truly value data for this saas companies? Like if we were buying these dying saas companies at 2x ARR before (as example), maybe there is a better metric. Idk, just thinking out loud here.
9. It feels like a good chunk of legacy software won't make it to the agentic era, especially anything built around people clicking through a lot of screens.
10. Every company I talked to wants to pipe its internal data into one place and expose it to agents through MCP. Then they look at the data and realize it's a mess: five versions of the same customer, old Slack channels, PDFs nobody can search. Cleaning that up feels like a big consulting opportunity!
11. A lot of founders are building the basic building blocks for agents: APIs, data layers and tools. Some of the companies I saw barely have a UI because the main user is an agent. I really believe the startups that build primitives to this agentic era will do extremely well. Building blocks is the best way to think about it.
12. Labs can get plenty of training data, but it's harder to get real examples of agents failing inside companies. Whoever has those logs has something valuable.
13. Someone running a big consumer company told me the next fight is over memory. The model that remembers the most about you wins, and the smartest model matters less than people think.
14. Physical AI came up a lot. Astra I think was the first model that got people into AI can actually do CAD, and I think a lot of people are thinking what does vibe manufacturing really look like. The line I keep thinking about came from a robotics founder: the hardest problems in AI are deployment problems now, not research problems. Their robots work on their own, call a human when they get stuck, and every one of those calls becomes training data.
15. Cybersecurity companies are having a moment and are actually cool companies to build now, especially the ones that clean up after a breach. Every agent with access to your systems is a new door into your company, and a lot of those doors were left open.
16. Some startups are worth more dead than alive now. A shutdown company with 5 years of Slack, email and code can get paid for licensing all of it. I wouldn't be surprised if founders start factoring that into when they shut down.
17. People are starting to talk about monetizing the agent web. It feels really early, but when the most popular user of the internet is an agent, what startups should you be building?
18. I think agent insurance is coming. Once an agent makes an expensive mistake, insurers will want audits before they cover anyone.
19. Several people said the hire they want most is someone with taste who can write evals. The models are getting good at generating ideas, so the hard part is judging which ones are good.
20. New trend I observed: startup raises VC, uses venture dollars to become a creator, startup fails, founder falls back on being a full-time creator and incubates other products bootstrapped.
21. Getting SIGNIFICANT distribution is HARD right now. Founders are sponsoring buses, buying billboards like crazy and throwing parties with famous DJs to get noticed. Kinda feels dotcom era in that sense.
Attention is what's scarce! The growth guy going viral sharing his UGC strategy from Wispr Flow is a good example. It's the sauce everyone wants, and I truly believe there are probably only 50 people on the planet who know how to scale these types of businesses efficiently in this era.
Always good to get that dose of SF. I felt sooo lucky to have such an incredible trip during such an incredible time in building businesses. Surreal in so many ways.
Happy to be home and locked in.
Until next time!


Data is one of the last real moats in AI, but the market for it seems like a black box
Random "$100M ARR" claims from companies I’ve never heard of and vague posts about making millions a week brokering data for labs
So this is the first thing I've seen that maps this opaque corner of the market
Surprised to find there’s 159 vendors selling training data, RL environments and evals
Fastest-growing corner from what I can see is enterprise workflow environments
Curious what you think is the next category once this becomes saturated?
My guess is agent trace data in dynamic environments

if you sell AI training data, see how you compare: we found 159 companies selling data, RL envs and evals, every fact sourced
plus 38 programs that pay companies for their data: whosellsdata.com
8 of the 14 that pay companies directly publish a dollar range. most of the rest set terms per deal. unknowns are marked and nothing is ranked
the other page: what each program wants, who qualifies and what it offers: whosellsdata.com/buying
missing something, or something wrong? fix it on the site, a person reviews every change
we built this at @Secludy. if you buy, broker or license company data and need the names out before it reaches a lab, dm me
My 12yo son is becoming a power user of AI, which is great and I’ve supported him in his journey, but I do worry about safety, especially around images and video
Very happy to see projects like @whitecircle coming at this from an independent angle

We are open-sourcing RISE, our red-teaming algorithm that breaks the safeguards of the latest image models from OpenAI, DeepMind, and others.
RISE uses readily available models like Qwen and Gemini Flash under the hood, with no additional training required.
Read more: whitecircle.com/research/bre…
We’re doing this internally with Hermes agents inside Slack, connected to our benchmark-winning company brain as a shared context layer
There are options besides using an expensive frontier lab tool that also allow you to own your data

Had to turn off CLAUDE TAG in SLACK... as a usage-based product, it was burning far too many tokens.
Is there a better, more flat-rate solution inside Slack that anyone recommends?
SLACKBOT doesn't work like an agent inside of Slack for some reason... and i just don't like giving my data to frontier labs.
is there a hosted LLM / agent platform we can contain in SLACK yet or do i have to roll my own?
Since joining @codos_ai I’ve talked with dozens of enterprises about AI
Some ramblings from these convos:
> most still view AI as a productivity tool and think incrementally (10-20% ish boost) rather than in reinvention terms and orders of magnitude improvement
Partial explanation is that most are not exposed to the frontier so they don’t see what many of us see, their view is based on the reality of their world vs the reality being shaped at the frontier
The other part is it’s hard to think in OOM terms when you’re in the weeds, it all sounds so unrealistic, and that’s an exposure that AI native firms will exploit
> using AI is not the same as really using AI
Everyone has licenses and people in the org using AI, but the vast majority of usage is Q&A and working with docs
The real opportunity for most enterprises is in uplifting the REAL usage across the org and unlocking what that can do for the business at scale
> the stated sense or urgency doesn’t match the actions on the ground
Most everyone agrees AI is happening fast and will impact their industry/company, but the observed sense of urgency in actions isn’t there, most go about their day the way they always have
> AI at mid enterprises is rarely owned by anyone, it’s fragmented across the company
Most don’t have a head of AI or coordinated strategy for applying AI across the company, but almost all say they want/need more structure around AI and some level of leader+program for running it
> most enterprises are delusional on hiring a head of AI
They want someone with executive experience, plugged into the frontier, who can roll up their sleeves and build and deploy, but also talk board-level strategy and link outcomes to P&L
And they want to pay this role like a typical mid/sr exec
This is a unicorn role and anyone fitting the description has incredibly demand and optionality right now, very tough to find this person and near impossible to do it quickly
I have more ramblings but will stop here for now, I’ll formulate these more cohesively into an article at some point
Would love to hear other’s views and experiences on this topic
Model aggregators will need to do more than just aggregate to remain competitive
I like this move by @straitlyai to develop a creative use case to drive token consumption
Aggregation is just a pure price/volume business unless you give people another reason to come

Today I'm opensourcing Consensus: the first truth engine built on real human opinions.
Ask it anything. It reads 10,000+ posts and comments across X and Reddit to surface what people actually believe.
For example you can ask:
"Will AI destroy humanity?"
> 61% believe YES
> 28% believe NO
> 10% say that humans are the real risk
> 1% hold other beliefs
Every % is linked to the exact posts and comments behind it.
Consensus is completely free and open-source for anyone to use
Try it at: useconsensus.io
Choose your fighter:
Opus/Fable
Sol/Astra
Muse/Wonder
Gemini/Argon
Pretty common to have both Claude and OpenAI monthly plans, but most won’t have all 4
So now we must choose

Most new apps will have some form of embedded inference in the product
As usage scales, so does inference cost
Selling data is how many apps will pay for inference

Tokens or Data (or both :))?
Heard rumors that some of the top vibe-coded app builders are selling production traces to the labs. (in addition to their core revenue stream of selling credits)
It doesn't surprise me in the least. That's incredibly valuable data for the labs.
As my friend @quxiaoyin posited, there are truly only two business models in AI:
1. Selling tokens
OR
2. Selling data
So far, app builders were selling tokens (credits are a proxy for tokens). Logical that they would sell data too.