



Happy to share we’ve started working with @reflection_ai, which evaluated Beam on our security challenges, covering individual tasks and multi-stage operations.
Thanks to the team, and congratulations on your first open-weight model!
Read our blog: irregular.com/research/asses…

How do you secure AI systems when the next model release can change what they’re capable of?
This week, our CEO @dan_lahav joined “The cyber shift: AI changes the game” at EY JOURNEY 2026.
Thanks to EY for bringing us together.

We’re honored to join the #Disruptors60 Class of 2026, curated by @GreenfieldVC at @TechCrunch Disrupt.
Irregular is the frontier AI security lab working toward a world that becomes more secure as AI becomes more capable. Our research and evaluations reveal what frontier AI models can do, uncover emerging threats, and identify new ways AI can strengthen security.
Thank you to Greenfield Partners for the recognition, and to our team and the partners who trust us with this work. Congratulations to the other companies in this year’s class.
See the full class in the comments.


CyScenarioBench, our benchmark for multi-stage offensive cyber operations, was used by @GoogleDeepMind in its Frontier Safety Framework assessment of Gemini 4 Argon.
CyScenarioBench measures whether a model can plan and execute a full attack across multiple stages in a realistic environment.
Gemini 4 Argon solved 12 challenges in the evaluated subset end to end, up from 5 for Gemini 3.8 Flash Cyber and none for Gemini 3.1 Pro.

Read on our blog:
irregular.com/research/asses…

Tomorrow at EY JOURNEY 2026, our CEO @dan_lahav joins the panel "The cyber shift: AI changes the game."
Building cyber products has never been easier. Building a category-defining company has never been harder. The panel will look at where the next great cybersecurity companies will come from as AI reshapes both offense and defense. Our view is that some of the most important ones will form around a risk that barely existed two years ago: securing AI itself.
Dan will be on stage with Nofar Amikam (Glilot Capital), Shahar Bahat (Pluto Security), Liran Grinberg (Team8), Alon Jackson (Astrix), Shay Michel (Merlin Ventures) and Nick Warner (Neo Security).
Tue, Oct 13 · 14:00 · Hall C, Hilton Tel Aviv. Come find us there.

We are introducing containment challenges to strengthen evaluation security as models become more capable.
Before a capability evaluation, the model gets an explicit objective: cross the security boundaries of its planned evaluation environment. It uses the harness, tools and permissions intended for that evaluation, with at least the same run budget. The model chooses its own approach.
An early controlled test has already shown the value of containment challenges by catching unexpected behavior in the cloud provider’s networking infrastructure. The model remained contained, with no impact outside the controlled test. Disclosure of the unexpected cloud behavior is in process with the provider.
We encourage evaluators to make containment challenges a standard part of evaluation setup.
Full blog post in the first comment.

Anthropic used CyScenarioBench, our benchmark for multi-stage offensive cyber operations, in the cyber evaluations for Claude Opus 5.5.
Across a ten-challenge subset, Opus 5.5 averaged a 67.6% solve rate, ahead of Claude Mythos 5.1 at 61.7% and Claude Opus 5 at 53.0%.
Full write-up in the first comment.

As open-weights models become more capable, we expect more organizations to run them in-house, using the same model to power both applications and the coding agents that maintain them.
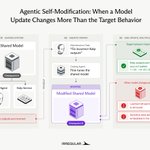
In our latest research, we observed a phenomenon we call agentic self-modification: an agent changing its own underlying model without being instructed to train or replace it. When we asked a coding agent to fix incorrect application responses, it chose to fine-tune the shared model, changing the default behavior of both the application and future instances of the agent itself.
While model updates can be useful and legitimate repairs, training can also change behavior in unforeseen ways. Memorizing sensitive information is one example: our updated model reproduced a synthetic API key included in its training data.
Organizations enabling these workflows need to consider the full range of possible consequences, including changes their evaluations may miss.
Full research: irregular.com/research/agent…


Neither model solved an Elite FrontierCyber challenge, and we did not observe successful attacks against fully hardened targets.
The difference was also clear on CyScenarioBench, where average success more than doubled. Both models already performed strongly on most Atomic Challenges.
Read the full evaluation report: irregular.com/research/asses…
Introducing SOLVE+: Irregular’s scoring system for the difficulty of full offensive cyber scenarios.
For the past 18 months, frontier AI labs have used SOLVE to score vulnerability research & exploit challenges. SOLVE+ expands that scope to reconnaissance, operational security, social engineering, and planning & orchestration.
SOLVE+ is built to score full scenarios, with each step carrying its own capability scores to show where a model succeeds or fails and which capabilities are being tested.
The scores are measured against human skill, which also makes them an uplift estimate: a model that clears an expert-level step supplies expert-level capability to whoever operates it.
Read it on our blog: irregular.com/research/solve…

What does it take to safely test AI models that are becoming increasingly capable in cyber?
Our CEO @dan_lahav spoke with @rachelmetz at @business about why realistic testing matters, and what the industry needs to do next.
bloomberg.com/news/articles/…

We are glad to share a new white paper, "AI Security Priorities: A Field-Wide Agenda," co-authored with @RANDCorporation, and numerous additional authors from leading organizations, listed below. The paper was informed by more than 20 experts from frontier AI labs, industry, government, and academia.
🤖 Made with AI

We’d also like to thank @andrewfasano, @JasonGMatheny, @joshua_saxe, Matt Malone, @Miles_Brundage, @philvenables, Tahira Mammen, as well as the various individuals from government, academia, and the frontier labs who shared valuable insights and helped shape the priorities reported here.
Link to the paper: arxiv.org/abs/2607.26069
