Doing linear algebra & optimizing GPU kernels. Court jester @SFTensor

Tensor Cores
Joined September 2019
while benchmarking our AutoResearch harness we noticed that there was a ~1.1pt jump in benchmark performance when the agent's name is Ilya. it's kind of funny to think about the set of circumstances that made that happen
51
38
31
1,160
116,031
these guys are insane
Introducing XPU Grasshopper, an AI chip co-designed with AI for the era of recursive self-improvement It went from its first tokens to 816x faster in 13 weeks Pre-order the FPGA devkit: zscc.ai/grasshopper
3
10
239
33,530
Join us at @SfTensor :)
I'm lucky to be working with 8x NVIDIA B200 GPUs for R&D and kernel optimization, while enterprise GPUs are quite scarce and expensive. #B200 #GPU
4
1
67
5,098
If you're not getting blocked even by Sonnet 4.6, are you really working at the frontier?
10
399
this was obviously just a fun experiment and we're mostly focused on post-training real LLMs and are seeing exceptional results there, but sometimes it's fun to play around and see what's possible xitter.cf/BenKoska/status/210363…
Replying to @BenKoska
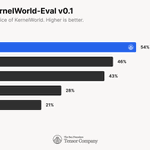
We held out a slice of those tasks to evaluate how good a model truly is at kernel optimization without any contamination on a non-saturated benchmark.
1
94
10,632
also, we're hiring someone to answer 'is this fp8 accumulation actually stable' and 'will this run diverge at step 40k' with rigor instead of the way I do it (a 🤷‍♂️). yes the title is Member of Mathematical Staff, yes it's a real job
1
10
629
if you enjoy doing stupid stuff and want to have fun while also figuring out how to prove the correctness of the next frontier training runs, formalize hardware behavior and perform numerical analysis on low-precision floats, we're hiring a Member of Mathematical Staff sf-tensor.com/careers/member…
turns out when you have too many GPUs for your own good you can do stupid stuff such as pre-training a foundation model with constrained decoding on PTX -- that is, it does not speak natural language, it's tokenizer is PTX, it's thoughts are PTX, it's all PTX 🧵
2
26
1,984
keeping in alignment with our strong commitments around alignment and observability, we've invested at least 1 GPU hour into alignment research and are releasing some examples of the models chain-of-thought and how we're analyzing it
turns out when you have too many GPUs for your own good you can do stupid stuff such as pre-training a foundation model with constrained decoding on PTX -- that is, it does not speak natural language, it's tokenizer is PTX, it's thoughts are PTX, it's all PTX 🧵
1
1
33
2,566
pretty numbers?
1
10
172
how we're thinking about it: I have no idea how to understand any of that but it works so 🤷‍♂️
9
160
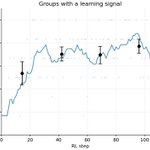
looking at the results of reinforcement learning we see that, despite applying techniques designed for language models it... kind of works?
1
91
8,012
turns out, it actually kind of works? despite not having been trained on natural language or natural language reasoning, it was able to produce kernels that passed all tests 28% of the time and produced speed ups of up to 66x compared to triton kernels
5
5
2
232
28,656
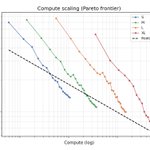
looking at the results across data, compute and model size we see quasi-scaling laws emerge. Given the nearly deterministic nature of the data, despite being well past the Chinchilla-optimal point, the models are not flattening off yet as even small models have plenty of capacity left
1
1
1
110
9,440
we first pre-trained on a lot of synthetic and real PTX data, then ran SFT using high-quality PTX from our pool of millions of agent steps optimizing real tasks and finally ran reinforcement learning putting our massive pool of RL environments to use
1
87
11,355
Given the fact that it does not speak natural language, it only speaks PTX, there is no way for us to give it instructions, it simply gets a PTX kernel and then produces a, hopefully, faster PTX kernel, or at least that was the theory
1
1
3
118
14,428